

Introducing TypeSafe Jev: Typed Judgments as Programming Primitives
Learn about TypeSafe Jev, a typed AI model that uses probabilities for structured decisions, with examples of code review comment analysis.
 CORE
·
What Is TypeSafe Jev?
Jev is a model that answers questions about text with typed values and probabilities instead of generated output. It is TypeSafe’s flagship model and the first of its System One models, a class of models built “to make fast, structured decisions that software can use directly” (Reference 2).
A general-purpose LLM such as GPT or Claude also understands natural language, but it answers by generating text. When a program needs a decision, the usual pattern is to prompt for JSON, parse the reply, validate it, and handle the cases where the model wrote something else. Jev removes that step. You send a state (the data to judge) and a set of named questions, and each answer comes back in the exact type the question declared.
The differences that matter for a developer:
- No text generation. Jev does not write replies, produce code, or explain its reasoning. It returns a decision and the probabilities behind it.
- Typed contract. The question type fixes the shape of the answer, so there is nothing to parse and no output format variation.
- Calibrated probabilities. The models are trained so that their probabilities “reflect uncertainty” against real outcomes. Code can further set thresholds and route low-confidence cases to humans.
- Parallel, independent questions. Questions in one request are evaluated separately and in parallel. Adding questions “barely changes the response time” and avoids context-rot (Reference 1).
The division of labor is simple. Your code owns the workflow, rules, and calculations. Jev supplies the semantic judgment that ordinary code cannot. Ultimately the code decides.
The Three Primitives: Noul, Choice, and Score
Every question has a type, instructions (the question itself) and where the type needs it, criteria (the possible answers). The question name is a key for your code only. It is not sent to the model, so the instructions must carry the full meaning (Reference 3).
| primitive | asks | CRITERIA |
Returns |
|---|---|---|---|
noul |
Does a condition hold? | Optional object with true and false descriptions |
noul: probability of yes, 0 to 1 |
choice |
Which one of a fixed set of options applies? | Required map of option name to description | choice, probabilities per option, confidence |
score |
Where does the state sit on an ordered scale? | Required ordered list of levels (up to 10) | score, legend, probabilities per level, confidence |
Noul (Reference 4) is a yes/no question that returns the probability that the answer is yes. Phrase the question so a high value means yes, ask one condition per noul, and set thresholds in code according to the cost of being wrong. For multi-label problems, ask one noul per label in the same request.
Choice (Reference 4) picks exactly one option from the set you define. The full distribution shows how the options compete and confidence summarizes how concentrated it is. Include a catch-all option for when nothing fits.
Score (Reference 4) places the state on ordered levels numbered from 0. The score is the probability-weighted average of the level numbers, so it can fall between levels:
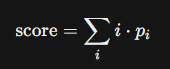
The model judges each level on its own and does not see its number, so each level should describe a concrete situation rather than a degree like “moderately”. Because different distributions can give the same score, read probabilities and confidence alongside it.
Confidence on choice and score describes how peaked the answer is, not whether it is correct (Reference 5).
Experimenting in the Playground
The fastest way to try Jev is the TypeSafe Playground (Reference 7), which runs real requests from the browser without any code. You need a TypeSafe account and an API key, which you generate in the console. Keep the same key for later API or SDK work, ideally in a TYPESAFE_API_KEY environment variable.
A typical session:
- Open the Playground and log in.
- Paste the text to evaluate as the state.
- Add a question: give it a name, pick the type (noul, choice, or score), write the instructions and, where needed, the criteria. The questions editor also accepts JSON, so you can paste a whole questions object directly.
- Add more questions of any mix. They all run against the same state in one request.
- Run it and read every answer side by side: the value, the probability distribution, and, for choice and score, the confidence.
The Playground is ideal for tuning questions before writing code. Change one word in an instruction or a criterion, rerun, and see how the probabilities move. Once the questions behave, the same JSON goes unchanged into a call as the one below (Reference 6).
POST https://api.typesafe.ai/v1/systemoneFrom code, the same request is a single HTTP call. The example below sends a request containing only the blocking question:
curl https://api.typesafe.ai/v1/systemone \
  -H "Authorization: Bearer $TYPESAFE_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "jev-preview",
    "state": "This builds the SQL query by concatenating `userId` from the request, which allows SQL injection. Please switch to a PreparedStatement before we merge.",
    "questions": {
      "blocking": {
        "type": "noul",
        "instructions": "Does this code review comment require a change before the pull request can be merged?"
      }
    }
  }'
The response holds one entry per question under answers, for example "blocking": {"type": "noul", "noul": 0.98}.
Additionally, GET /v1/models lists the available model names.
Concrete Example: Analyzing Code Review Comments
Three code review comments go to Jev in three separate requests, each asking the same three questions:
- Is it blocking? (noul)
- What is it about? (choice)
- How constructive is it? (score).
A tool built on these answers could hold a merge until blocking comments are resolved, label comments by topic, or flag a hostile tone to the other team members.
The States (The Comments)
| request | state |
|---|---|
| a |
“This builds the SQL query by concatenating userId from the request, which allows SQL injection. Please switch to a PreparedStatement before we merge.” |
| b |
“Nit: I’d rename tmp to pendingOrders so the loop reads better. Not a blocker.” |
| c |
“Did you even run this? The cache is never invalidated, so users will see stale prices.” |
The Questions
All three requests share this questions object. Only the state changes.
{
  "blocking": {
    "type": "noul",
    "instructions": "Does this code review comment require a change before the pull request can be merged?",
    "criteria": {
      "true": "Points out a defect or risk that must be fixed, or explicitly asks for a change before merging",
      "false": "An optional suggestion, nit, question or praise that does not block the merge"
    }
  },
  "category": {
    "type": "choice",
    "instructions": "What is the main concern of this code review comment?",
    "criteria": {
      "bug": "Incorrect behavior, a logic error or a missing case",
      "security": "A vulnerability such as injection, leaked secrets or missing authorization",
      "performance": "Speed, memory or resource usage",
      "readability": "Naming, formatting, structure or style",
      "other": "Anything else, such as tests, documentation or a question"
    }
  },
  "tone": {
    "type": "score",
    "instructions": "How constructive is the tone of this code review comment towards the author?",
    "criteria": [
      "Hostile: insults or mocks the author",
      "Curt: dismissive or sarcastic, no explanation",
      "Neutral: states the problem without explaining or suggesting a fix",
      "Constructive: explains the problem and suggests a fix",
      "Very constructive: explains the problem, suggests a fix and is encouraging"
    ]
  }
}
The three primitives each do a different job here. Blocking is a yes/no condition, so it is a noul with a threshold set in code. Category is one of five exclusive options, with other as the catch-all. Tone is ordered, so it is a score from 0 (hostile) to 4 (very constructive).
Expected Results
| Request |
blocking (noul) |
category (choice) |
tone (score, 0–4) |
|---|---|---|---|
| a |
High, near 1: a vulnerability and an explicit “before we merge” |
security |
About 3, Constructive: explains the risk and names the fix |
| b |
Low, near 0: labelled a nit and “Not a blocker” |
readability |
About 3, Constructive: suggests a rename and says why |
| c |
High: stale prices are a real defect even without an explicit request |
bug |
Low, about 1, Curt: the opening question is sarcastic, and no fix is offered |
Comment c is the interesting one. It mixes a valid bug report with a dismissive tone, and Jev should separate the two: blocking and bug on one side, a low tone score on the other.
Actual Results
Request a, the SQL injection comment:
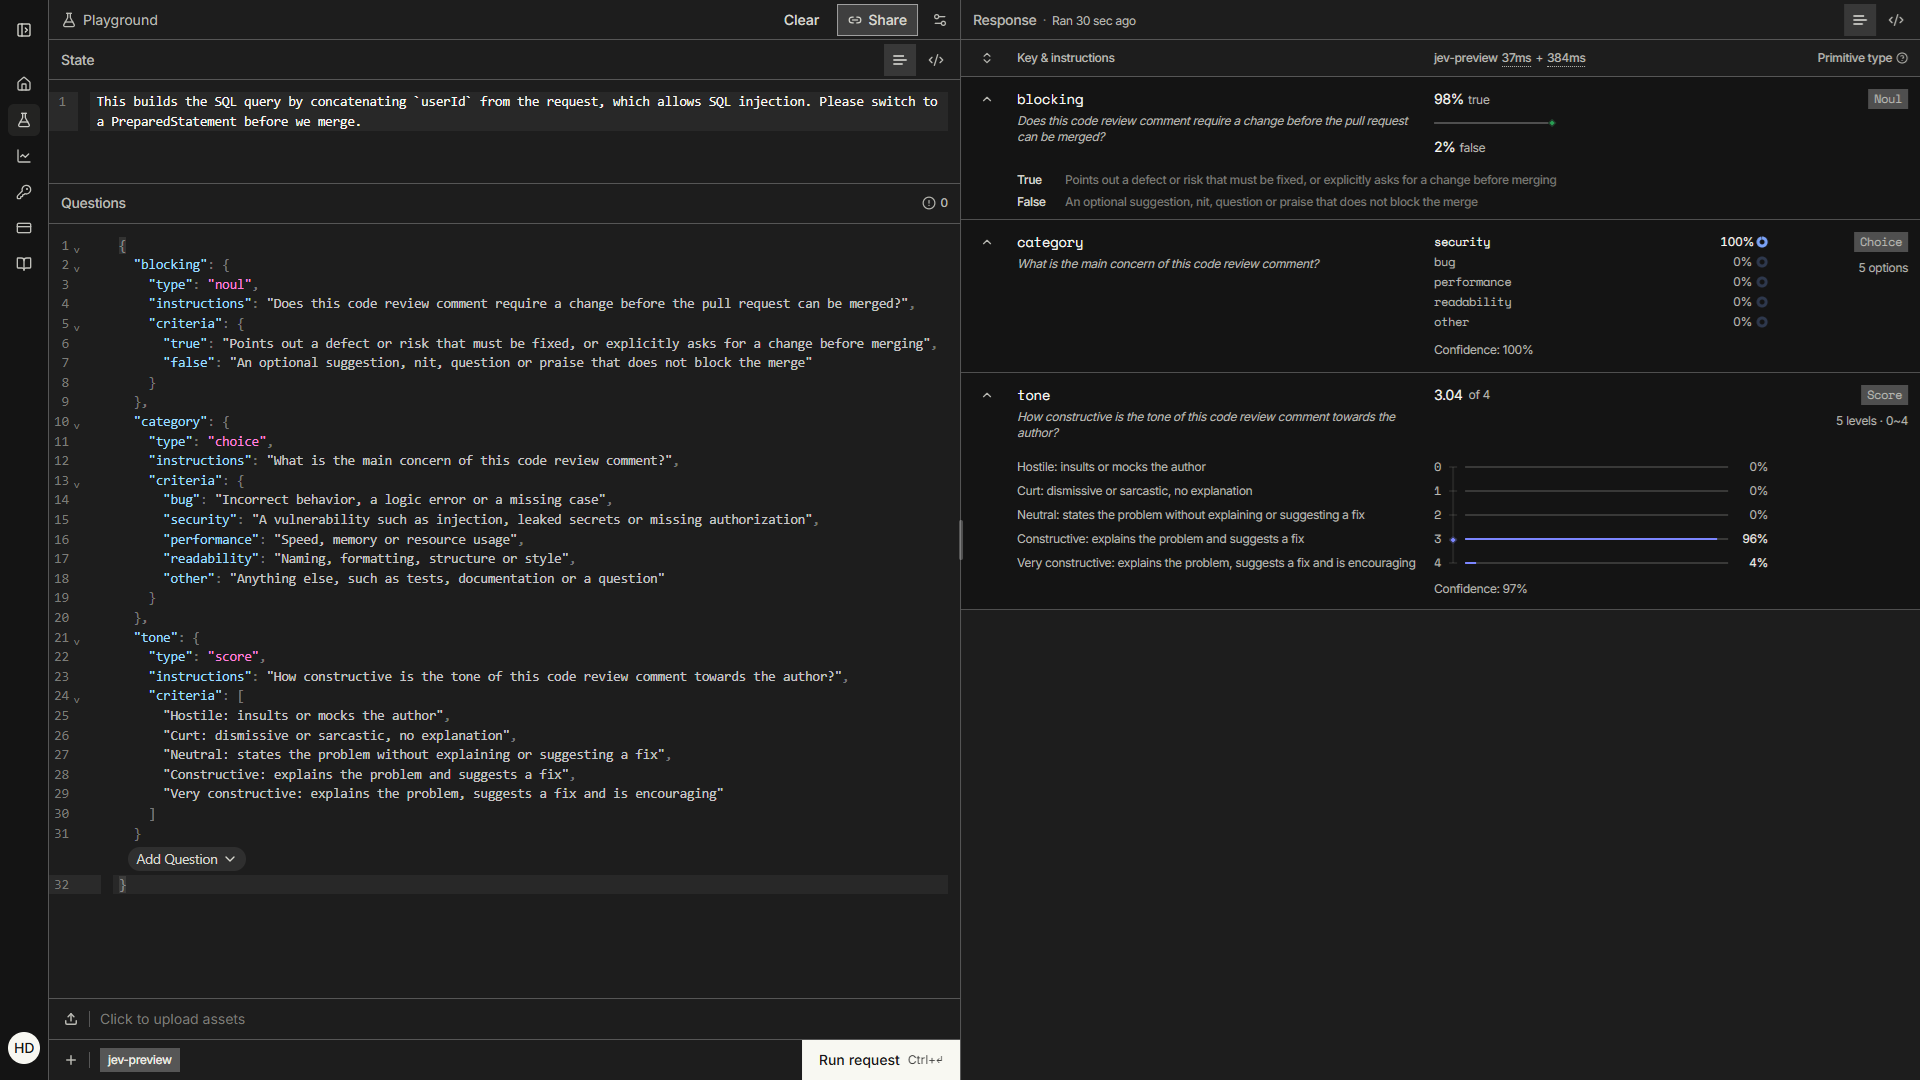
Jev matched all three predictions. blocking is 98% true, category is security at 100%, and tone scores 3.04: 96% Constructive and 4% Very constructive, with 97% confidence. All three runs used the jev-preview model.
Request b, the naming nit:
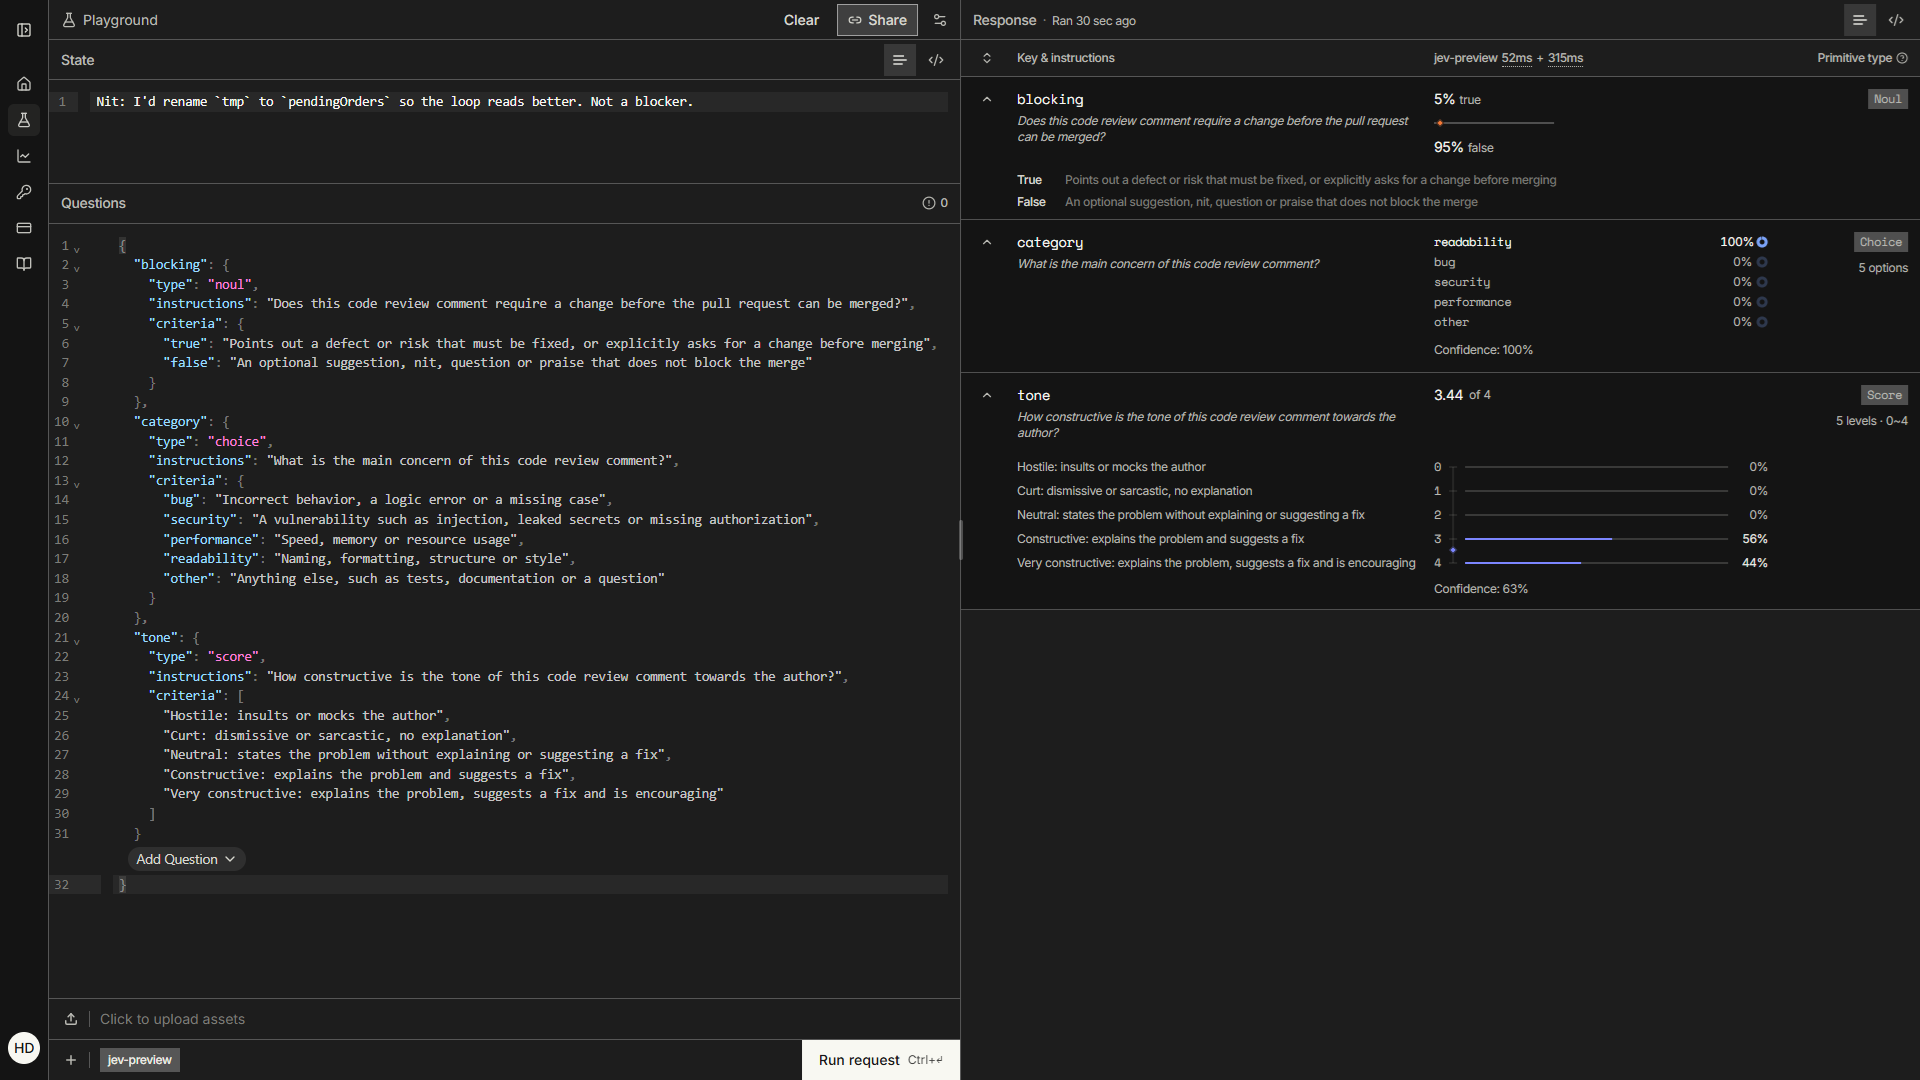
blocking is 5% true and category is readability at 100%, as expected. tone scores 3.44, higher than predicted: probability splits 56% Constructive and 44% Very constructive, so confidence drops to 63%. The friendly “Not a blocker” reads to Jev as partly encouraging, and the split is an honest signal that this comment sits between two levels.
Request c, the stale cache comment:
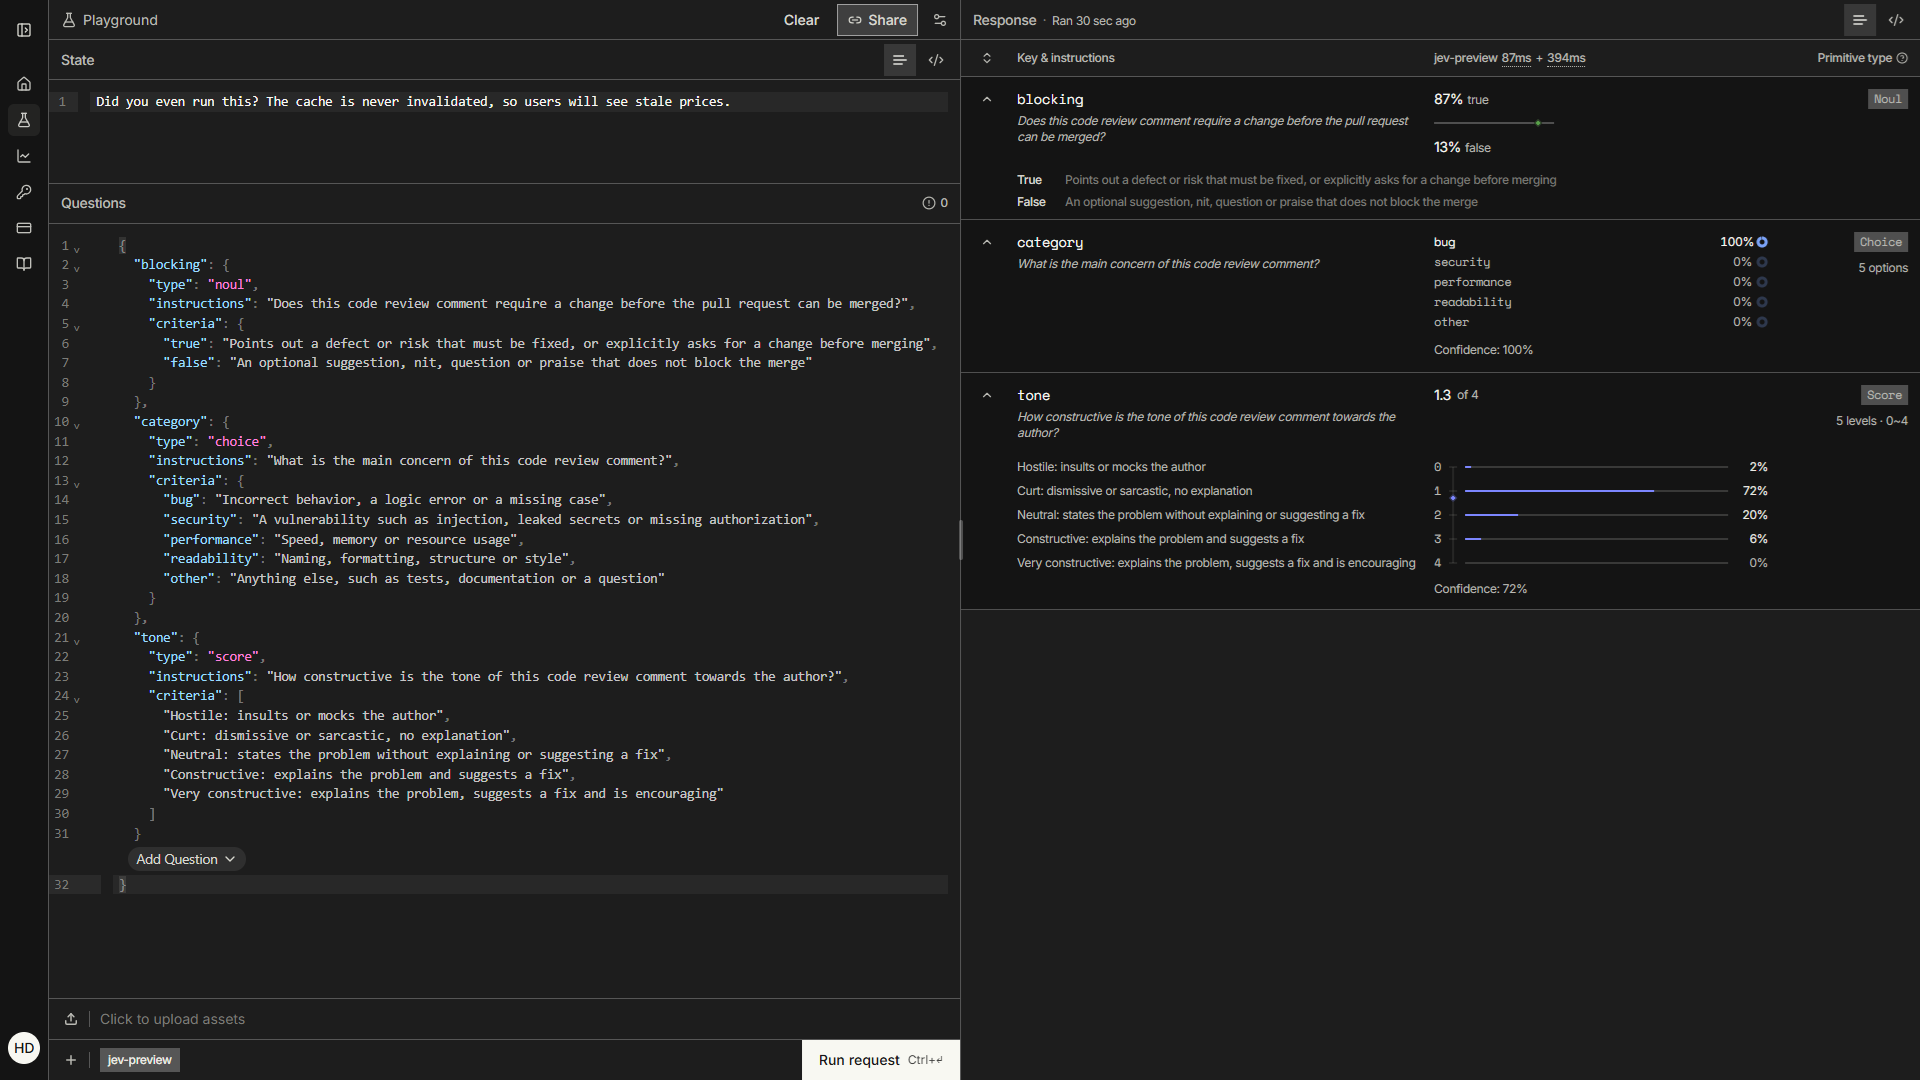
Jev separated the defect from the tone, as expected. blocking is 87% true and category is bug at 100%, while tone scores 1.3: 72% Curt, 20% Neutral, 6% Constructive, and 2% Hostile, with 72% confidence. The spread went toward Neutral rather than Hostile, so Jev reads the comment as sarcastic but not insulting. The lower blocking value (87% versus 98% for request a) also fits, since this comment reports a defect without explicitly asking for a change.
Conclusion
Jev turns a semantic judgment into a function call with a typed return value. Three primitives cover most needs: noul for conditions, choice for categories, and score for degrees. Each answer comes with probabilities that code can threshold, combine, or escalate.
The code review example shows the pattern in miniature: one request, three independent judgments, no parsing. The Playground is the quickest way to design and tune such questions before moving them into an application. As with any model, validate the answers and thresholds on your own data before relying on them.
Resources
[1] – TypeSafe Introduction
[2] – TypeSafe System One
[3] – TypeSafe Primitives (Questions)
[4] – TypeSafe Noul, Choice and Score
[5] – TypeSafe Confidence
[6] – TypeSafe HTTP API
[7] – TypeSafe Playground and API keys
[8] – The picture was taken in Zakynthos, Greece
Published at DZone with permission of Horatiu Dan. See the original article here.
Opinions expressed by DZone contributors are their own.