

Building a 2KB Histogram with Sub-0.2% Percentile Error
It uses float-like encoding for O(1) bucket indexing and trapezoid interpolation for accurate percentile estimation — with no floating-point math on the recording path.
The Problem: Tracking Request Latency Without Slowing Things Down
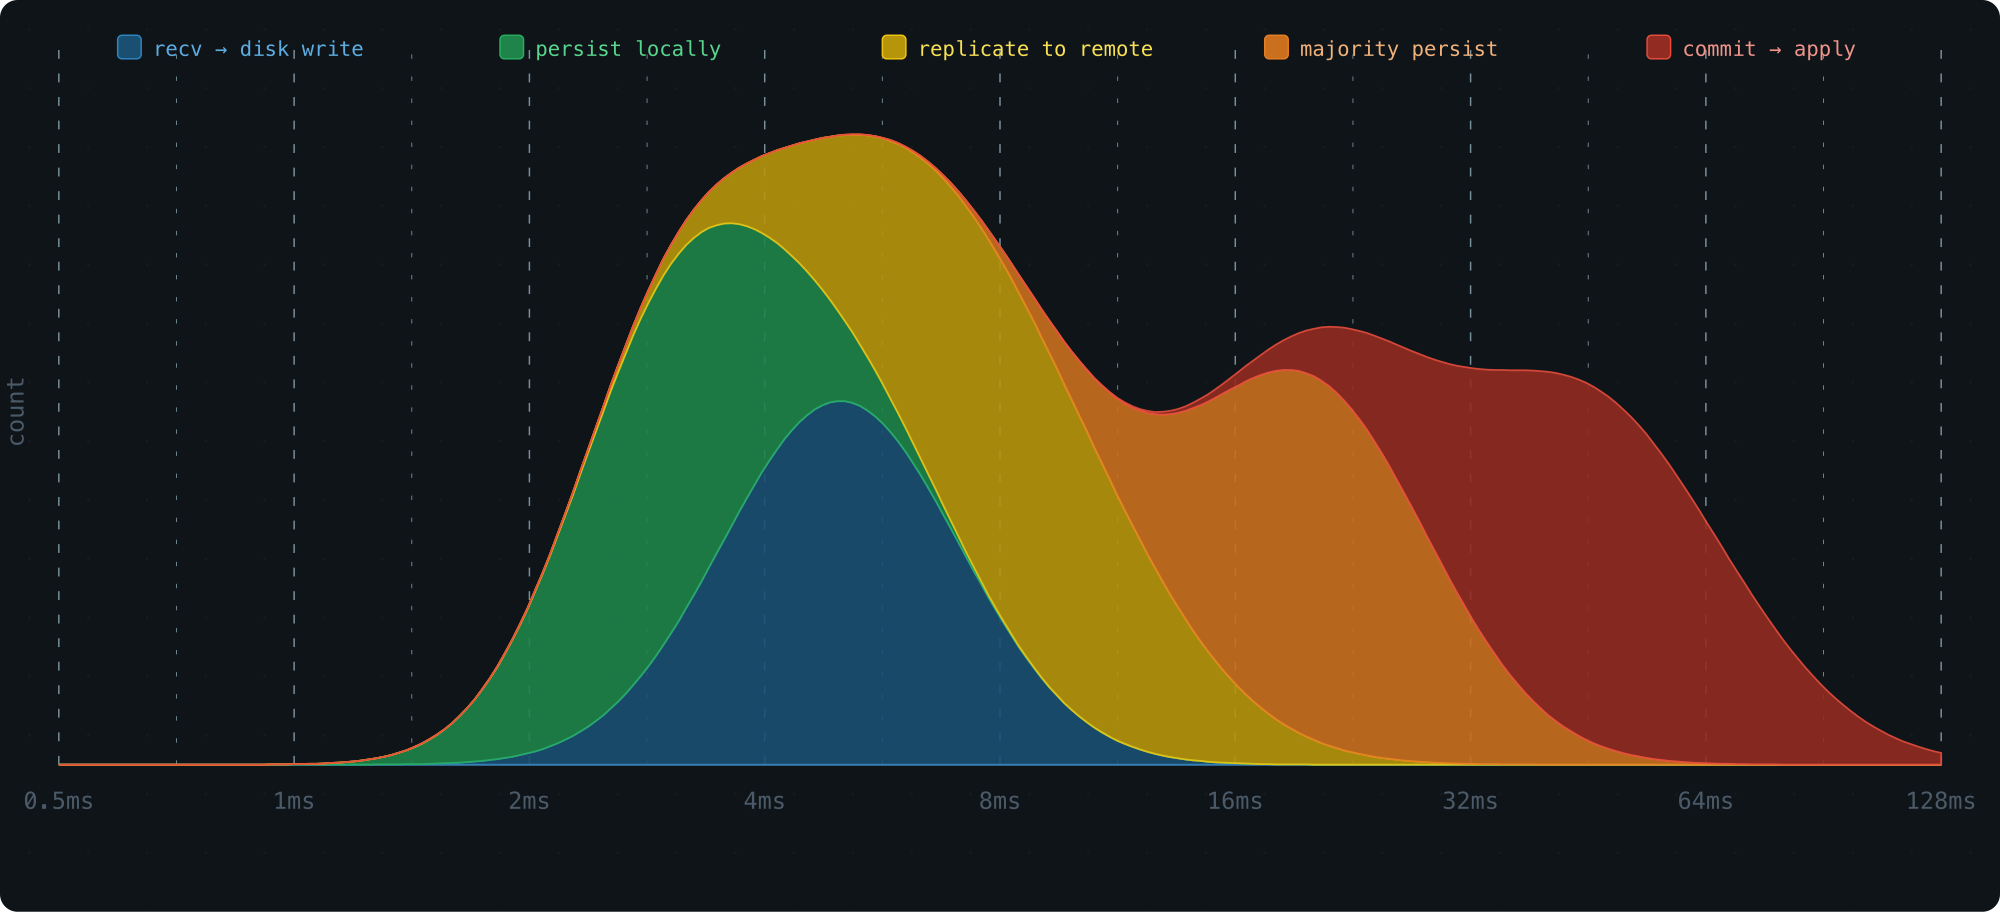
For a cloud data warehouse, performance is not just about average query time. What often matters more is tail latency, predictability, and the ability to pinpoint where things go wrong. In a cloud-native data warehouse like Databend, a single request may pass through multiple stages: SQL planning, distributed execution, remote storage, Raft logging, and state machine apply. Tail latency in any one of these stages can affect the query stability users actually experience.- Received → written to storage
- Persisted to local disk
- Replicated to remote nodes
- Acknowledged by a majority quorum
- Committed → applied to the state machine
- O(1) to record: No sorting, no rebalancing, and nothing that can stall a hot path
- Tiny in memory: A system may run hundreds or thousands of histograms at once
- Queryable for percentiles: P50, P95, P99
Recording: Getting Samples Into Buckets
Why Log-Scale Buckets
Most requests cluster around a typical latency, with a few outliers on both ends. This often produces a log-normal distribution: take the log of the latency values, and the shape becomes a classic bell curve.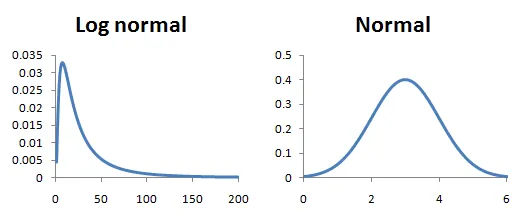
[0,1), [1,2), [2,4), [4,8), [8,16), ...Why powers of 2? Because multiplying by 2 is cheap on a CPU, and mapping a value to its bucket takes a single leading-zero-count instruction.
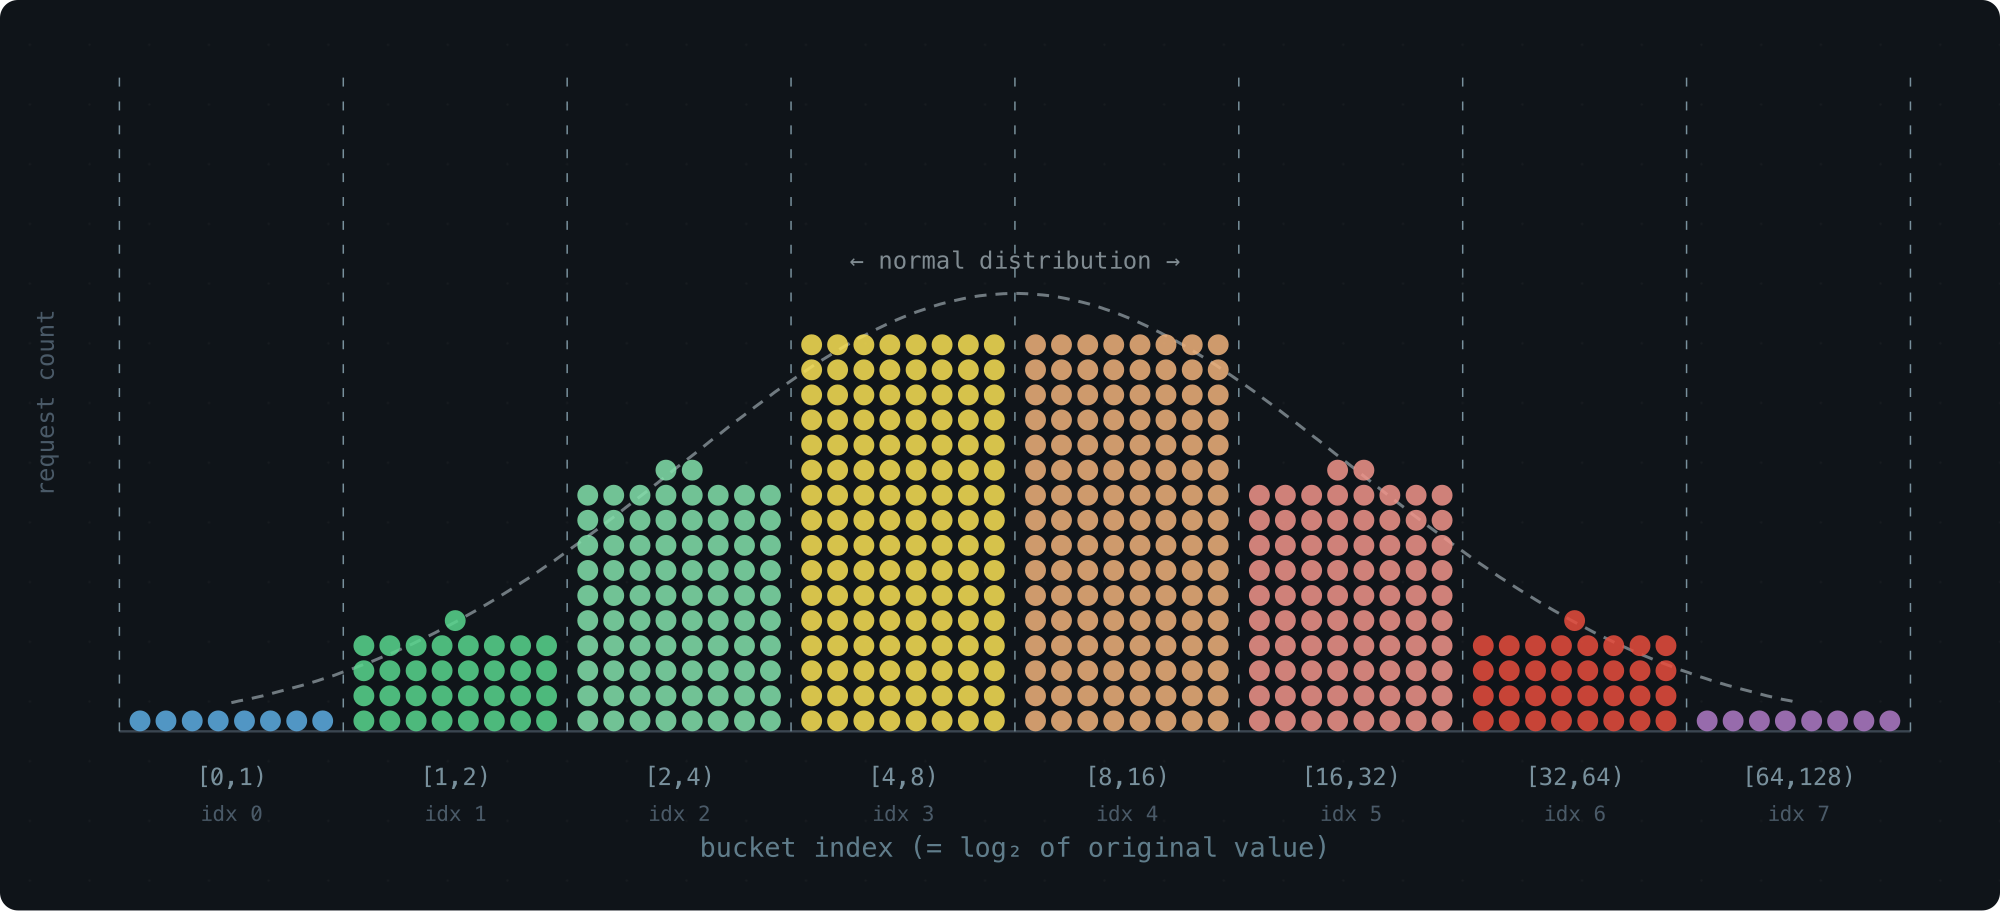
u64range.
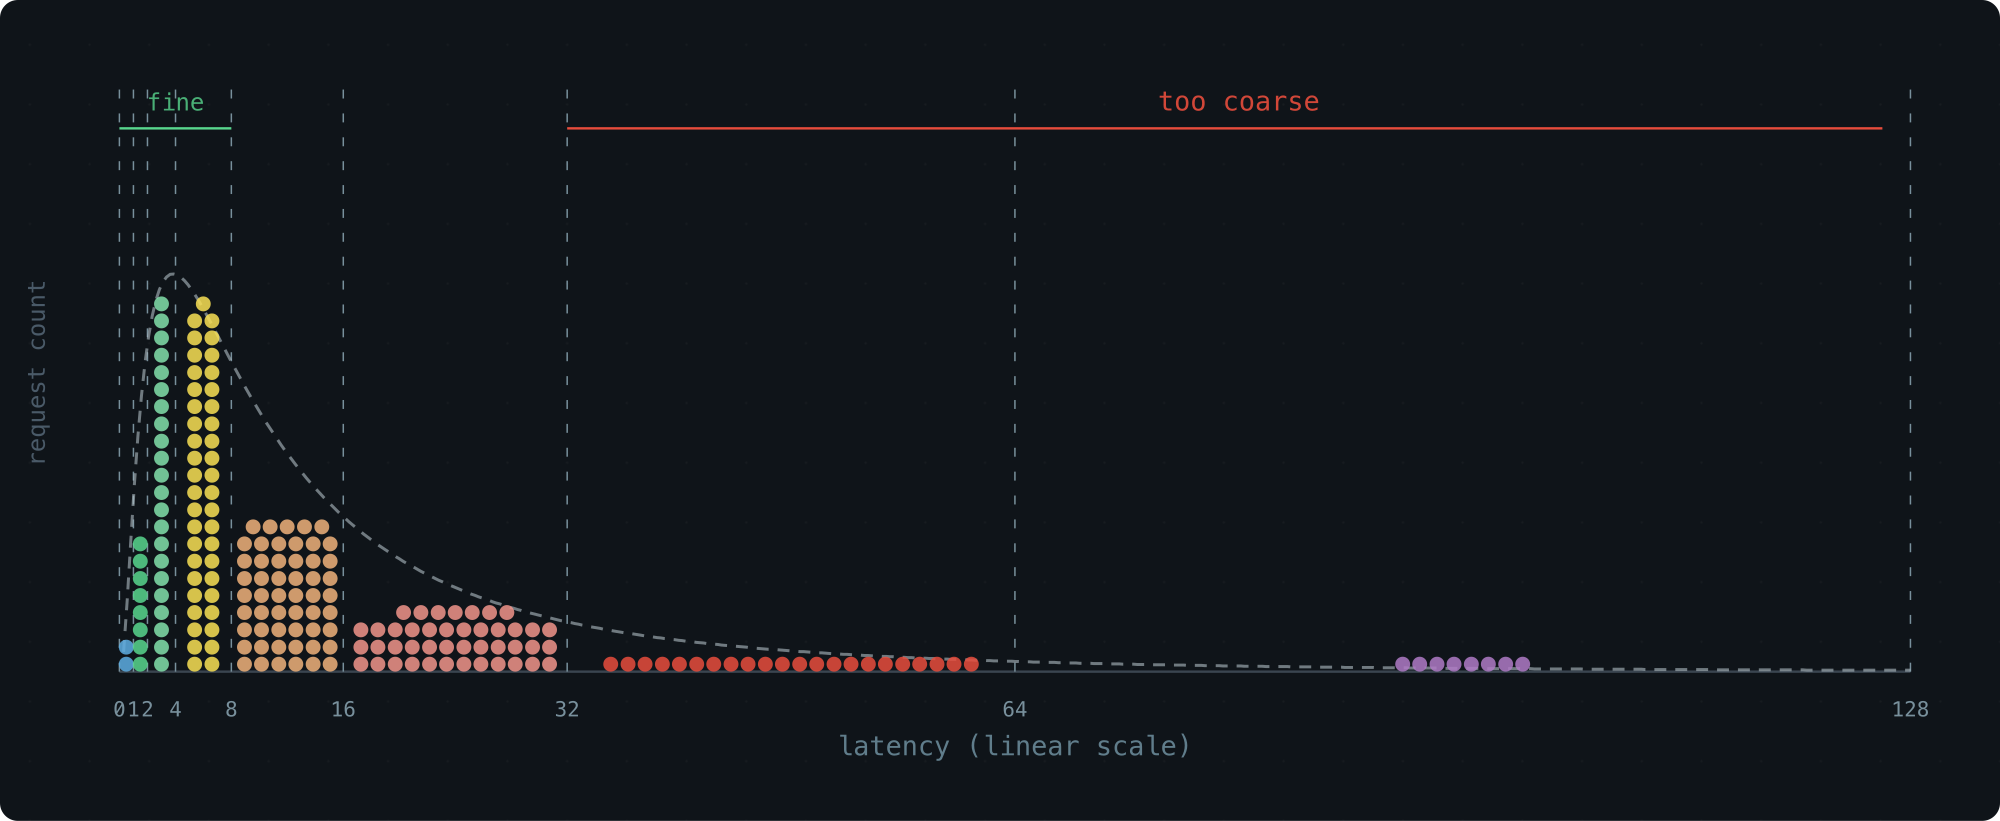
A Tempting Fix We Passed On
An obvious improvement is to use a smaller growth factor, such as 1.1× instead of 2×. That gives us more buckets and finer resolution: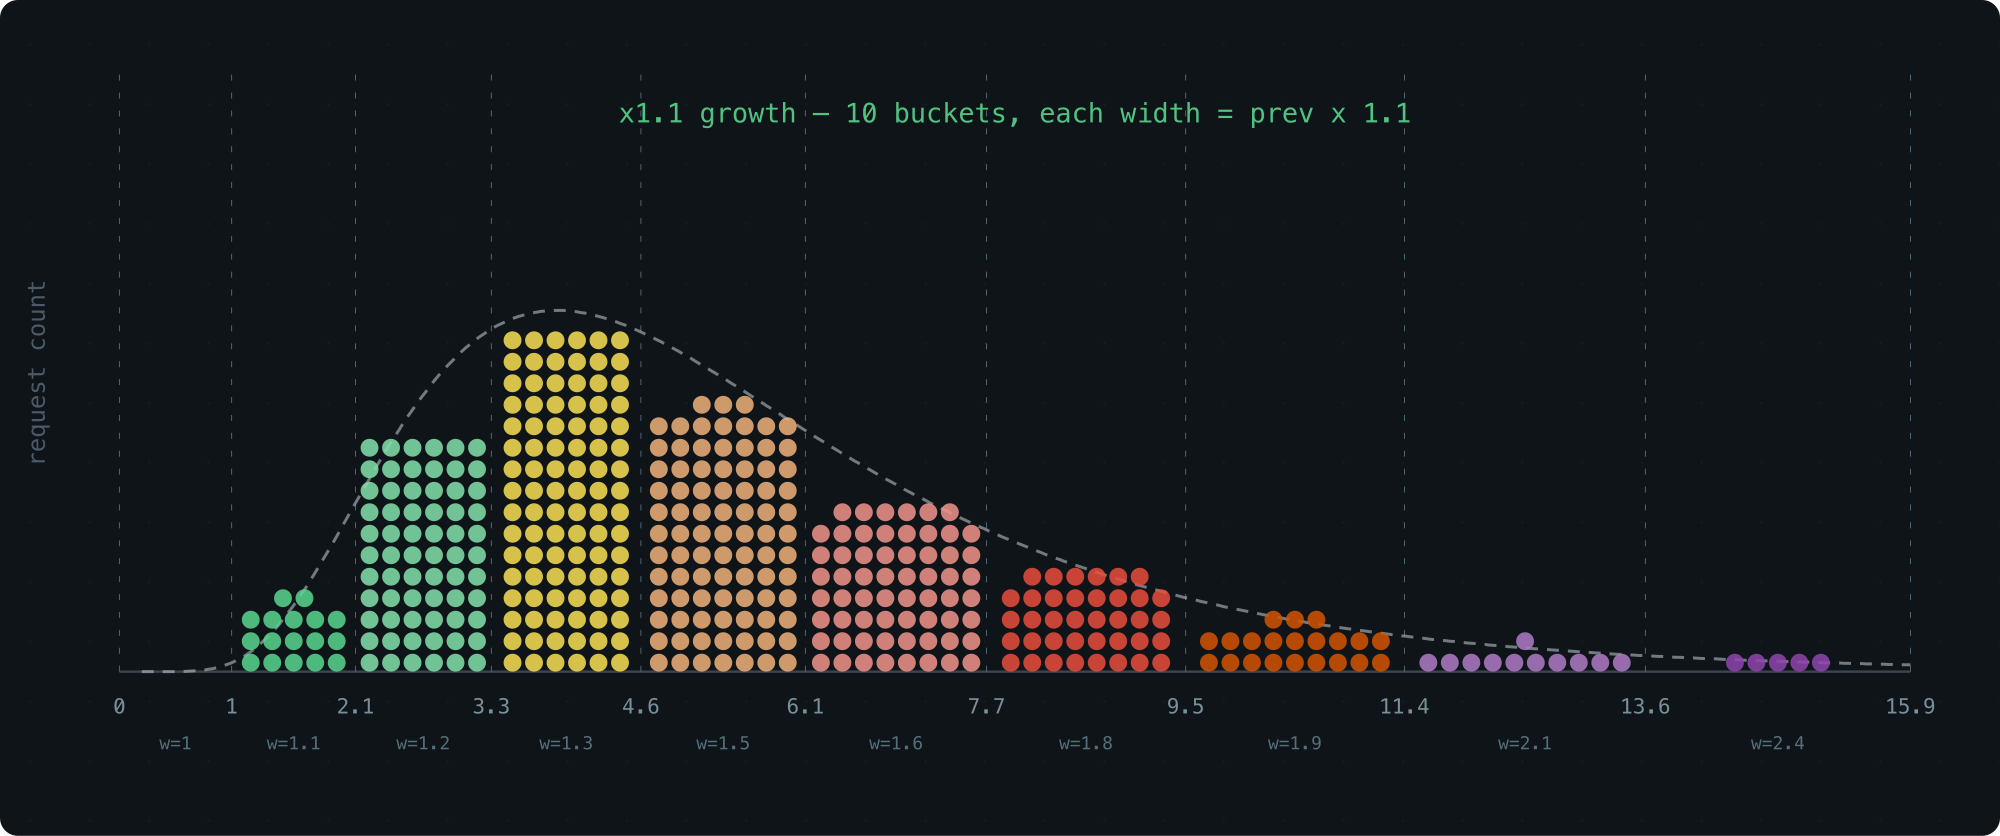
l means solving for the smallest x where 1 + 1.1 + 1.1^2 + ... + 1.1^x >= l, which requires floating-point logarithms. That is real overhead on a hot path.
The Trick: Float-Like Encoding
Here is the idea that makes the design work: keep bucket sizes roughly exponential, but encode each bucket using a fixed number of bits — a parameter we call WIDTH.00..00 1 xx 00..00
|
MSB
<- significant1selects the group. The two bits that follow select the bucket within the group.
WIDTH = 3:

range     bucket index        bucket size
[0, 1)     0  0b0 ..... 000    1
[1, 2)     1  0b0 ..... 001    1
[2, 3)     2  0b0 ..... 010    1
[3, 4)     3  0b0 ..... 011    1

[4, 5)     4  0b0 ..... 100    1
[5, 6)     5  0b0 ..... 101    1
[6, 7)     6  0b0 ..... 110    1
[7, 8)     7  0b0 ..... 111    1

[8, 10)    8  0b0 .... 1000    2
[10, 12)   9  0b0 .... 1010    2
[12, 14)  10  0b0 .... 1100    2
[14, 16)  11  0b0 .... 1110    2

[16, 20)  12  0b0 ... 10000    4
[20, 24)  13  0b0 ... 10100    4
[24, 28)  14  0b0 ... 11000    4
[28, 32)  15  0b0 ... 11100    4

[32, 40)  16  0b0 .. 100000    8
[40, 48)  17  0b0 .. 101000    8
[48, 56)  18  0b0 .. 110000    8
[56, 64) 19 0b0 .. 111000 8- Each group contains
2^(WIDTH-1) = 4buckets - The two bits after the MSB select the bucket within the group
- It behaves like a 3-bit float: 1 implicit leading bit + 2 fractional bits
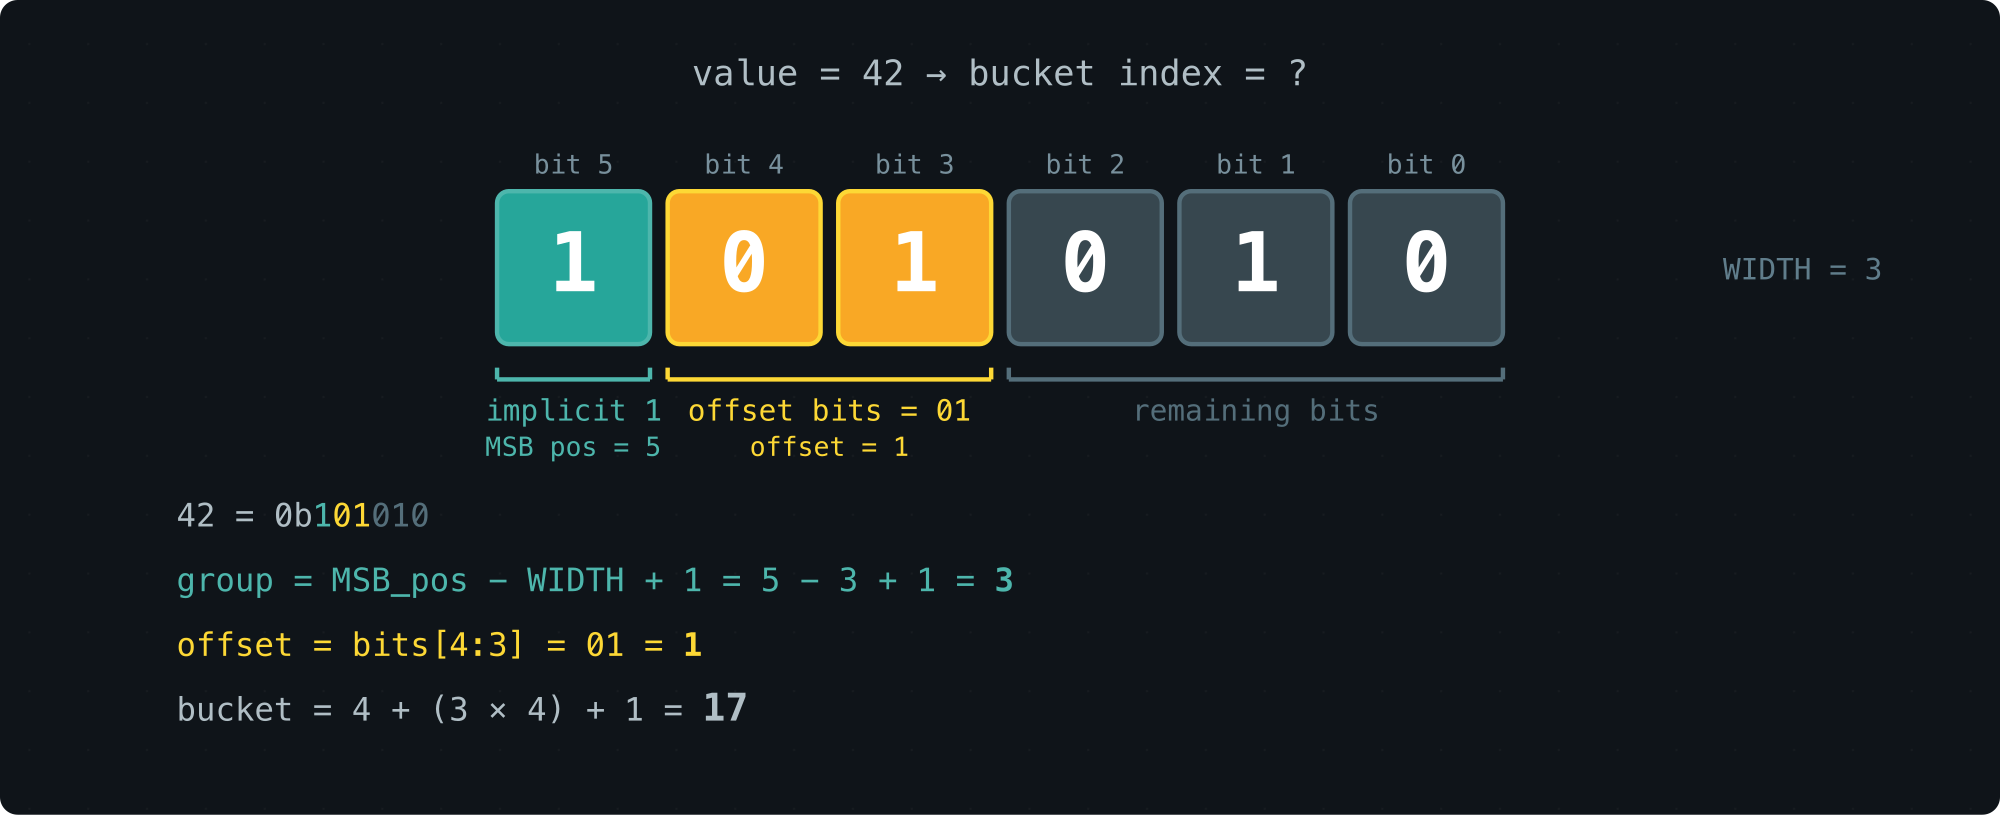
value = 42 (binary: 0b101010)
  MSB position: 5
  group: 5 - 2 = 3
  2 bits after MSB: 01 (from 1[01]010)
  offset in group: 1
  Bucket index: 4 + (3 × 4) + 1 = 17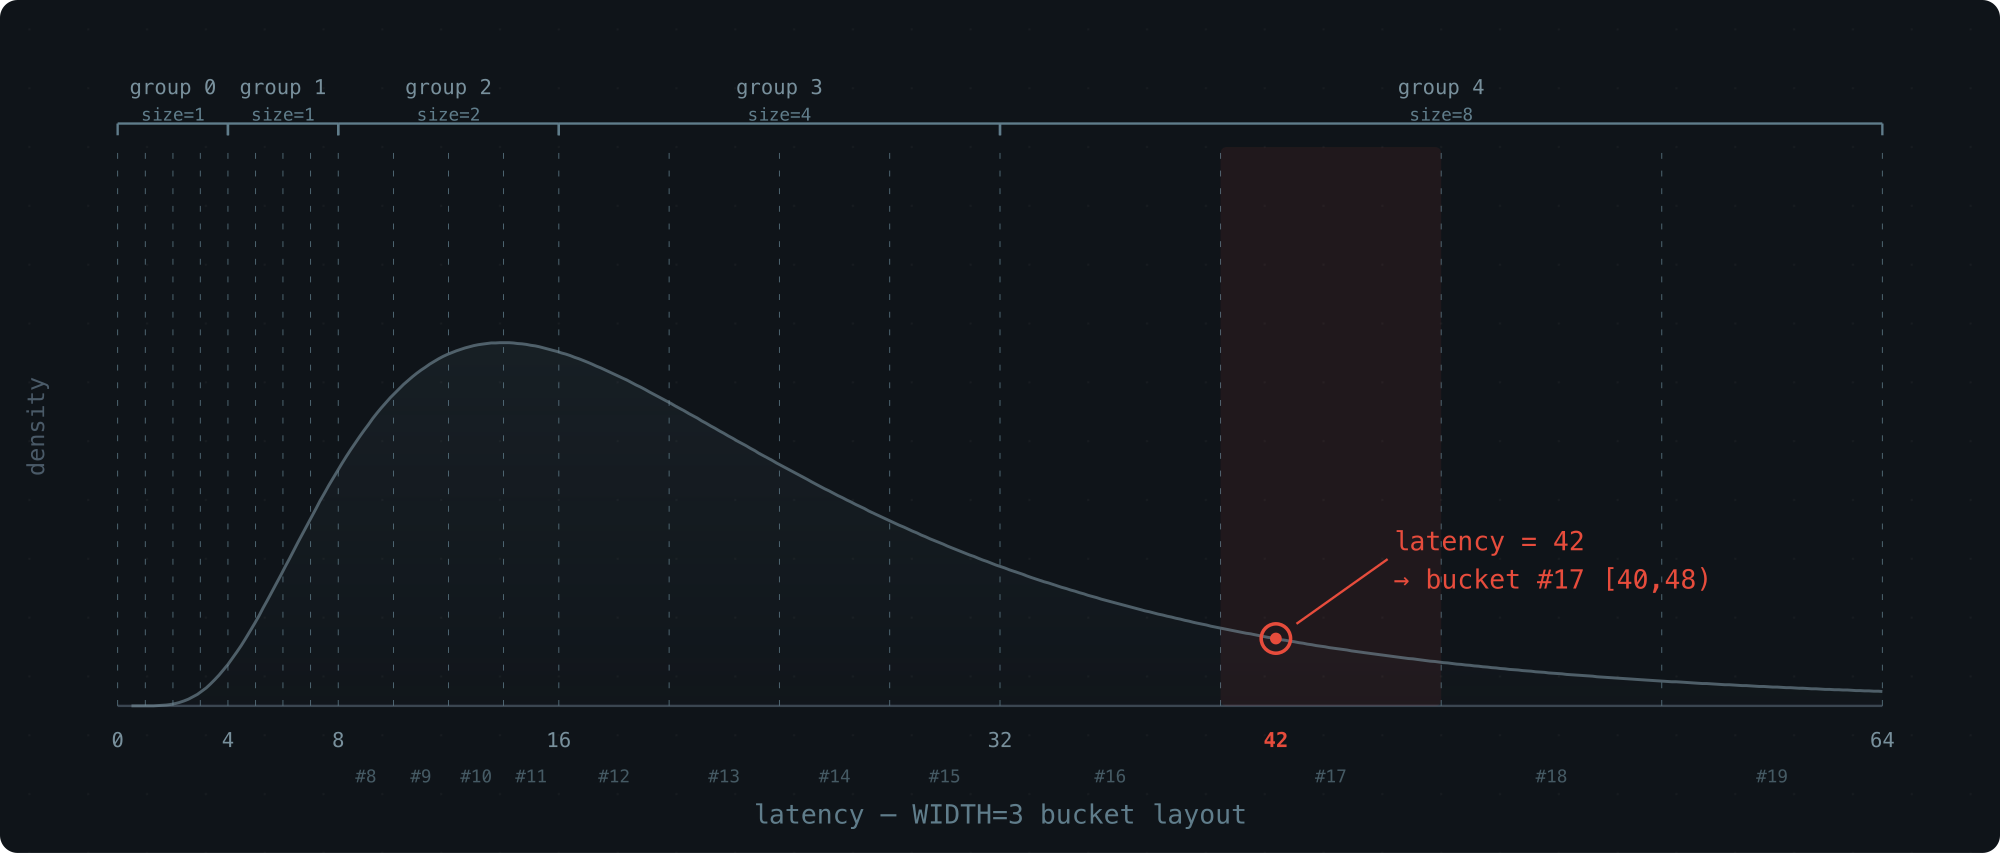
Tuning WIDTH: The Precision–Memory Knob
WIDTH controls how many buckets each group contains:2^(WIDTH-1). The number of groups is capped at 64, so the histogram still covers the full u64range. Increasing WIDTH gives each group more buckets, improving resolution at the cost of memory.
|
WIDTH |
Buckets |
Mem/slot |
Buckets per group |
|
1 |
65 |
520 B |
1 |
|
2 |
128 |
1.0 KB |
2 |
|
3 |
252 |
2.0 KB |
4 (default) |
|
4 |
496 |
3.9 KB |
8 |
|
5 |
976 |
7.6 KB |
16 |
|
6 |
1920 |
15.0 KB |
32 |
Percentile Estimation: Getting Answers Out
Once we have collected the counts, we want to query percentiles: at what latency have 50% of requests completed (P50)? What about 90% (P90) or 99% (P99)?Locating the Right Bucket
The basic idea is simple.p, then scan the buckets from the beginning and accumulate counts until you pass p. That gives you the target bucket. But a bucket spans a range, not a single point. We still need to estimate where inside the bucket the percentile falls.
(min + max) / 2.
|
|
P50 |
P95 |
P99 |
|
midpoint |
5.018% |
7.732% |
4.861% |
estimate = min + (max - min) × rank / countThis is better than midpoint because it uses the target rank within the bucket. But the assumption is still rough: log-normal data is skewed, even inside a single bucket.
Trapezoid Interpolation (Our Approach)
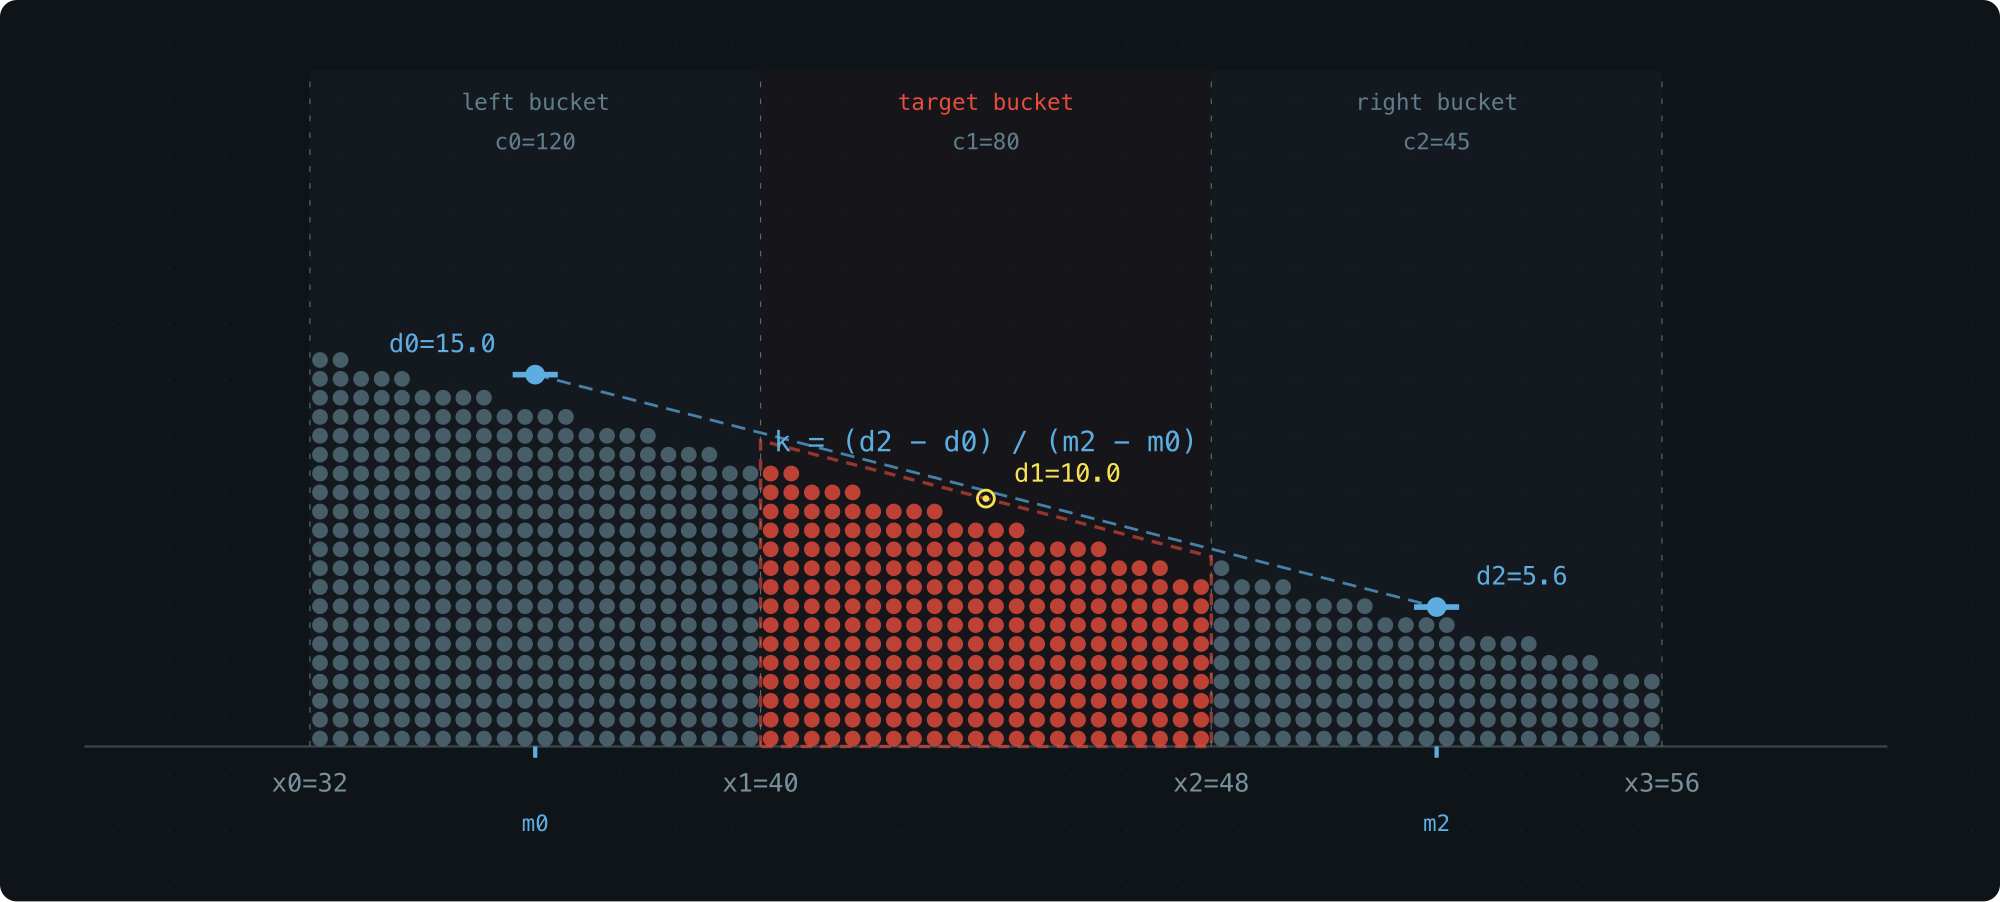
Uniform interpolation treats density inside a bucket as flat. In reality, density is often sloped: higher on the side closer to the peak of the distribution.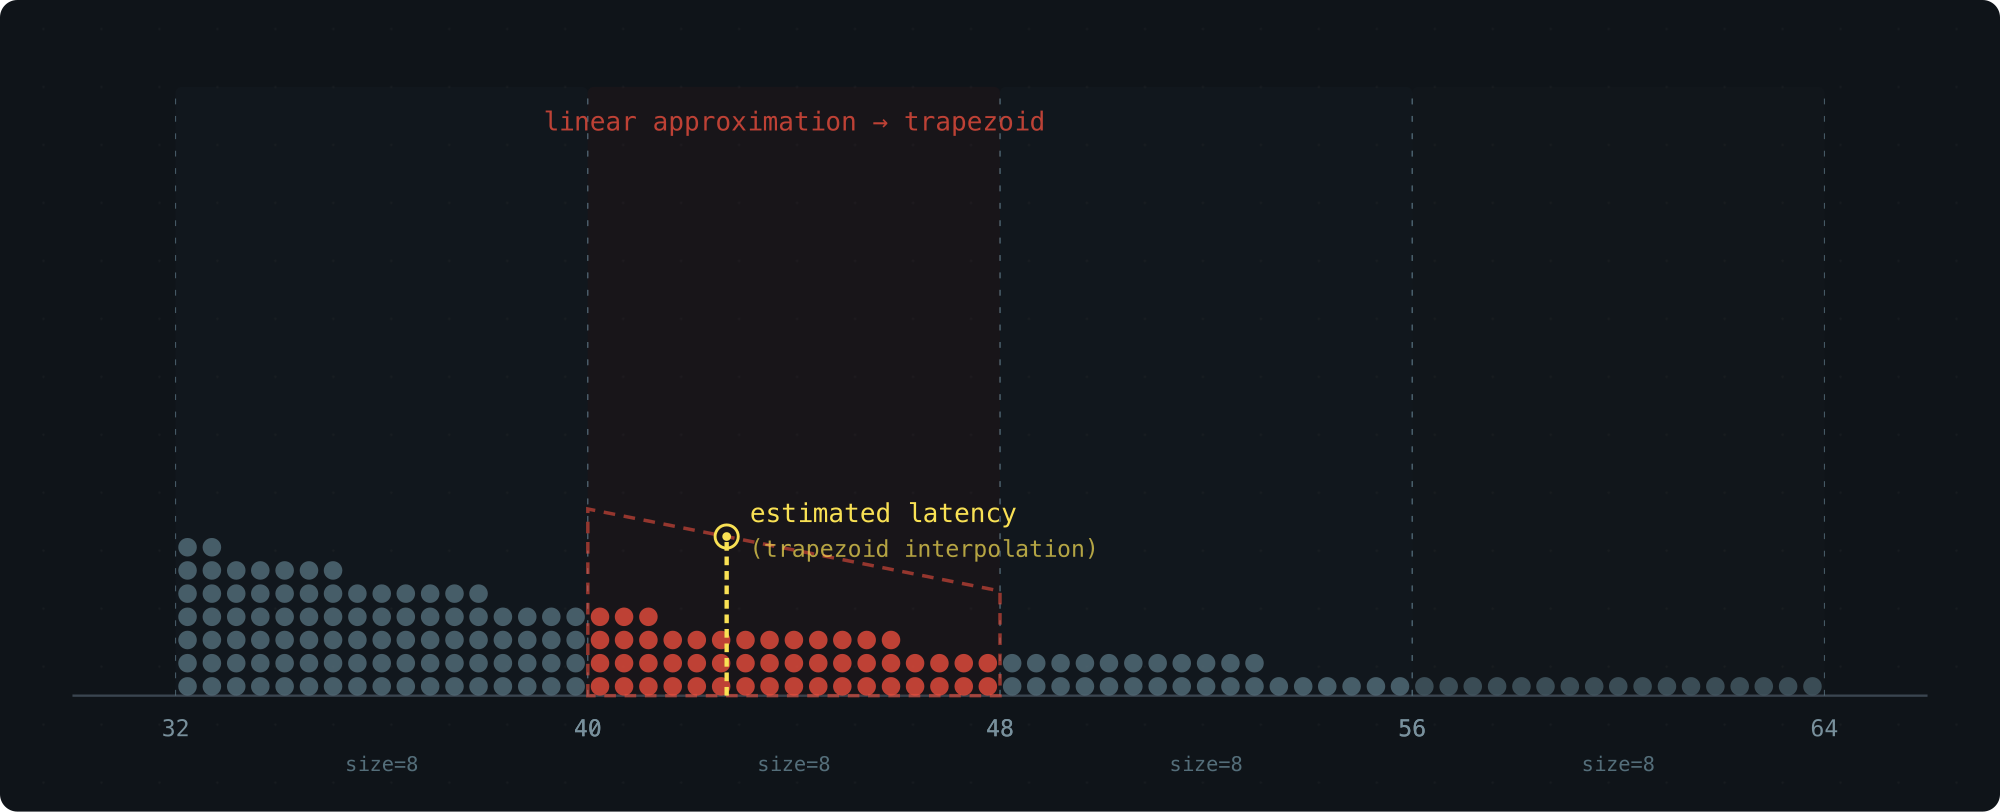
d0 = c0/(x1-x0), and treat it as the density at that bucket's midpoint, m0.
d2 = c2/(x3-x2) at midpoint m2.
m0 to m2. Over this short range, this is a reasonable approximation. It gives us the slope k.
k, anchored so that the density at the target bucket's midpoint (x1+x2)/2 equals the bucket's own average density d1 = c1/(x2-x1). For a linear function, the midpoint value is equal to the average over the interval.
x1equals the target rank.Same distribution, same buckets — here is how the results compare:
|
|
P50 |
P95 |
P99 |
|
midpoint |
5.018% |
7.732% |
4.861% |
|
trapezoid |
0.000% |
0.080% |
0.086% |
|
Variable |
Meaning |
|
|
Boundaries of the three adjacent buckets |
|
|
Bucket widths: |
|
|
Sample counts in each bucket |
|
|
How many samples into the target bucket the percentile falls |
d0 = c0 / w0       -- left bucket density
d1 = c1 / w1       -- target bucket density
d2 = c2 / w2 -- right bucket densitym0 = (x0+x1)/2, m2 = (x2+x3)/2.
k = (d2 - d0) / (m2 - m0)x1equals the target rank.
Benchmarks: Seven Distributions, Six WIDTH Settings
We tested the algorithm across seven representative distributions, each with 1,000,000 samples, using trapezoid interpolation.| W=1 W=2 W=3 W=4 W=5 W=6
| ------------------------------------------------------------------
| Uniform P50 0.108% 0.028% 0.012% 0.018% 0.019% 0.002%
| P95 2.317% 1.988% 1.035% 0.475% 0.005% 0.005%
| P99 4.290% 4.129% 3.706% 1.486% 0.298% 0.162%
|
| LN-API P50 2.281% 0.182% 0.000% 0.000% 0.000% 0.000%
| P95 20.256% 3.963% 0.080% 0.040% 0.040% 0.000%
| P99 11.951% 3.594% 0.086% 0.000% 0.029% 0.000%
|
| Bimodal P50 1.381% 0.394% 0.394% 0.197% 0.197% 0.197%
| P95 3.918% 0.172% 0.012% 0.028% 0.038% 0.008%
| P99 1.521% 1.344% 0.543% 0.078% 0.016% 0.014%
|
| Expon P50 1.012% 0.000% 0.145% 0.145% 0.145% 0.000%
| P95 10.989% 0.200% 0.000% 0.000% 0.033% 0.033%
| P99 18.665% 4.574% 0.824% 0.022% 0.022% 0.022%
|
| LN-DB P50 2.018% 0.034% 0.000% 0.000% 0.000% 0.034%
| P95 2.027% 0.368% 0.039% 0.006% 0.019% 0.026%
| P99 3.764% 1.066% 0.187% 0.007% 0.003% 0.062%
|
| Sequent P50 0.095% 0.000% 0.000% 0.000% 0.000% 0.000%
| P95 2.271% 1.967% 1.011% 0.496% 0.000% 0.000%
| P99 4.272% 4.118% 3.696% 1.521% 0.305% 0.169%
|
| Pareto P50 10.127% 1.899% 0.633% 0.633% 0.633% 0.000%
| P95 9.239% 0.272% 0.000% 0.136% 0.000% 0.000%
| P99 3.517% 0.879% 0.231% 0.093% 0.046% 0.046%
|
| ------------------------------------------------------------------
| Buckets 65 128 252 496 976 1920
| Mem/slot 520 B 1.0 KB 2.0 KB 3.9 KB 7.6 KB 15.0 KB
| Mem total 1.0 KB 2.0 KB 3.9 KB 7.8 KB 15.2 KB 30.0 KB- Uniform (uniform distribution): synthetic benchmarks
- LN-API (log-normal σ=0.5): API and microservice latency
- Bimodal (bimodal distribution): cache hit/miss — 90% fast path around 500 μs, 10% slow path around 50 ms
- Expon (exponential distribution): network and I/O waits
- LN-DB (log-normal σ=1.0): database query latency with a wider tail
- Sequent (sequential): adversarial worst case
- Pareto (Pareto distribution α=1.5): heavy-tailed workloads, such as request sizes
Summary
- 2 KB memory: WIDTH=3, 252 buckets of
u64, with P50/P95/P99 error under 0.2% for log-normal latency workloads - O(1) recording, O(buckets) querying
- Trapezoid interpolation delivers over 10× better accuracy than midpoint, with zero extra storage
- WIDTH is tunable: from 520 B for minimal tracking to 15 KB for maximum precision
Published at DZone with permission of bingxi Wu. See the original article here.
Opinions expressed by DZone contributors are their own.