

CART and Random Forests for Practitioners
Both CART and Random Forests help data scientists better understand algorithms and work with dirty data. However, they still have some key differences.
On January 26, 2017, Salford Systems had an excellent webinar called "Improving Regression Using CART and Random Forests." It was one-of-a-kind, explaining dead on what is needed for data science practitioners to understand the pros and cons of algorithms for implementations. I have noted some key points that I grasped in the webinar. You can register from this link to get a recorded copy of the video and slides.
Key Takeaways
Using CART and Random Forests, one can prepare great models with dirty data. Dirty data includes missing values, correlated values, outliers, etc.
CART and Random Forests are best suited for variables with nonlinear relations and work well with a lot of predictors.
Key issues with the OLS Regression model are:
Missing values: Requires handling such as missing value treatment and record deletion. For more information on missing values treatment, you can go through my previous article.
Nonlinearity and local effects: OLS regression cannot model nonlinear relationships. Either some transformation has to be done or other regression models such as logistics regression, GLM, etc. have to be used.
Interactions: Manually adjusted in a model or through some automated procedures.
Variable Selection: Have to be done manually or through some other procedure.
CART can be utilized for both Regression and Classification problems. For Regression, the best split points are chosen by reducing the squared or absolute errors. For Classification, the points that best separate (Entropy/Gini) the classes are chosen as best split points.
Grow a large tree and prune it. Pruning can be done by randomly selecting a test sample and computing the error by running it down the large tree and subtrees. The tree with the smallest error will be the final tree.
Some of CART's advantages include that the rules are easily interpretable and that it offers automatic handling of variable selection, missing values, outliers, local effect modeling, variable interaction, and non-linear relationships.
Missing values in a variable are handled by Surrogate splits. It is the similar split on another variable for the missing values in a variable that doesn't have the missing values at the same split.
CART is more sensitive to outliers at the target variable (Y) than the predictors (X). It might treat them at the terminal nodes that limit their effect on the tree. CART is more robust to outliers in the predictors (independent variables) due to its splitting process.
We can use a Relative error to evaluate a CART model. A Relative error close to Zero is considered good — it means that the algorithm is doing a better job than predicting only the overall average/median for all records. A Relative error close to One is considered bad — it means that the algorithm is not better than the average model results.
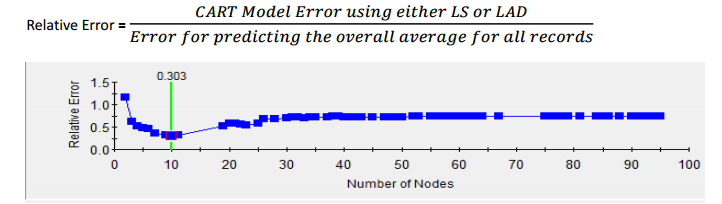
LS: Least Squares; LAD: Least Absolute Deviation.
Variable importance in a CART model helps in judging the influence of a variable in a model. It is calculated by summing the split improvement score for each variable across all splits in a tree.
Random Forest creates multiple CART trees based on "bootstrapped" samples of data and then combines the predictions. Usually, the combination is an average of all the predictions from all CART models. A bootstrap sample is a random sample conducted with replacement.
Random Forest has better predictive power and accuracy than a single CART model (because of random forest exhibit lower variance).
Unlike the CART model, Random Forest's rules are not easily interpretable.
Random Forest inherits properties of CART-like variable selection, missing values and outlier handling, nonlinear relationships, and variable interaction detection.
Other than these primary notes, the instructor had a demo on predicting Concrete strength, as Concrete is one of the most important ingredients for infrastructure projects and its strength is important for the overall stability of these structures. Charles Harrison presented the point and covered a lot of useful topics without delving much into complexities. Overall, it was an excellent webinar to attend, and I am looking forward to their future webinars.
Opinions expressed by DZone contributors are their own.