

Catching Query Regressions Before Your Users Do
Users can receive a list of regressions as objects that can be processed through various pipes, enabling automatic checking of all queries.
 ·
Join the DZone community and get the full member experience.
Join For FreeAll database administrators have experienced something like this at one point. A query that was running well suddenly starts to create problems. No error, failure, or warning appears on the dashboard, and the only noticeable sign is users complaining that the application is running slowly today. Now the DBA must determine which of the countless queries is causing the problem.
The best solution here is the Query Store tool. Since its implementation in 2016, this special feature has been storing data about SQL query text, execution plans, and statistics. In addition, unlike the plan cache, it retains this information even after a server restart. However, the trick is to get this data in a user-friendly format.
Looking is easy. Automating is the hard part.
When you launch SSMS, you will see the built-in "Regressed Queries" report — a GUI pane you open, filter by a metric and time window, and read. It's genuinely useful for firefighting: when something's slow right now, it's a fast way to see what changed.
There are scriptable options too. Erik Darling's free, open-source sp_QuickieStore is a stored procedure that digs into Query Store and hands back result sets you can filter in ways the GUI won't let you. It's excellent, and if you're comfortable in T-SQL, it's well worth knowing.
But notice what both leave on the table. The built-in report is something you open and stare at — fine for one database in the moment, useless for checking 150 of them every morning unattended. And even a scriptable stored procedure returns a result set for you to look at, not an object you can pipe onward. What most of us actually want is a job that runs autonomously, checks the whole estate overnight, and hands the result straight to a report or an alert without anyone pressing buttons.
This is the gap. Plenty of tools let you see regressions; a stored procedure lets you query them. Far fewer let you script them as objects — things you can filter, sort, pipe, and schedule as part of a pipeline. Once you're working with objects instead of screens or result sets, a lot becomes possible.
What Actually Counts as a Regression
Before initiating the automation process, it's wise to be truthful about what you're measuring, since the simple way is often misleading.
The obvious approach is "compare yesterday's average duration to today's." Two things are wrong with that. First, a plain average hides spikes — a query that's usually fast but occasionally awful gets smoothed into looking fine. Second, and worse, it treats every query as equal. A query that ran twice yesterday and a query that ran fifty thousand times yesterday both get one vote, so a query that happened to be slow on its two executions shows up as a giant "regression" next to nothing, and drowns out the query that quietly got 30% slower across fifty thousand real executions and is actually hurting you.
The fix is to weight by how often a query actually runs. Give the fifty-thousand-execution query the influence its volume earns, and filter out the low-count noise that produces false alarms. You're not asking "did the average change," you're asking "did something people actually run a lot get meaningfully slower." That's the difference between a signal you trust and an inbox full of cries of wolf.
One should also consider the lower limit of the two parameters chosen for the comparison. One might think it is enough to set the criterion of "servicing at least N times not long ago." However, even if the baseline was executed only a few times, it is still not a reliable indicator for comparison.
Doing It in PowerShell
This is the basis for Find-SqlQueryStoreRegression — the command in SqlReliabilityKit, a small command-line module available for free under the MIT License that provides a mechanism for reliability analysis. The command processes Query Store DMVs, executes a weighted baseline, removes any irrelevant noise, and produces output in the form of results.
Install-Module SqlReliabilityKit -Scope CurrentUserQueries that ran meaningfully slower in the recent window vs. the baseline window:
Find-SqlQueryStoreRegression -SqlInstance localhost -Database QsTest
It is not editable. It only reads the Query Store and generates results; it neither changes plans nor performs any modifications of its settings. What you do with that information is up to you, which is the whole point. As the results are presented as various objects, the most interesting part is the pipe.
The ten worst regressions, by how many times slower they got:
Find-SqlQueryStoreRegression -SqlInstance localhost -Database QSTest |
    Sort-Object SlowdownFactor -Descending |
    Select-Object -First 10
Only the serious ones, on queries that actually run a lot:
Find-SqlQueryStoreRegression `
    -SqlInstance localhost `
    -Database QSTest `
    -SlowdownThreshold 2.0 `
    -MinExecutionCount 50
That second one reads as plainly as it runs: show me queries that at least doubled, and only ones that ran fifty-plus times so I'm not chasing noise. Schedule that, pipe the result to an email or a Teams webhook, and you've turned "stare at a dashboard" into "get told when something's wrong."
Watching It Actually Catch One
One is justified in doubting tools that claim to spot issues. A tool that always fails to go off in trials is simply a tool that has not had its lies caught yet. So here is how you can ensure that your device will catch regressions that you will cause intentionally — and that is also the only honest way for you to trust any monitoring device.
The trick is to take a query that's fast because it uses an index, then pull the index out from under it:
Baseline: Run a query many times while it's fast (index present).
1..300 | ForEach-Object {
     Invoke-DbaQuery -SqlInstance localhost -Database QSTest -Query "SELECT COUNT(*) FROM dbo.Orders WHERE CustomerId = $($_ % 5000)"
}
Now break it: Drop the index so the same query scans the whole table.
Invoke-DbaQuery -SqlInstance localhost -Database QSTest -Query "DROP INDEX IX_Orders_CustomerId ON dbo.Orders"Run it slow, flush Query Store, then check 300 more executions, then:
Find-SqlQueryStoreRegression `
    -SqlInstance localhost `
    -Database QSTest `
    -WindowUnit Minute `
    -BaselineStart 15 `
    -BaselineEnd 3 `
    -MinExecutionCount 10 `
    -SlowdownThreshold 1.5 |
    Format-Table -AutoSize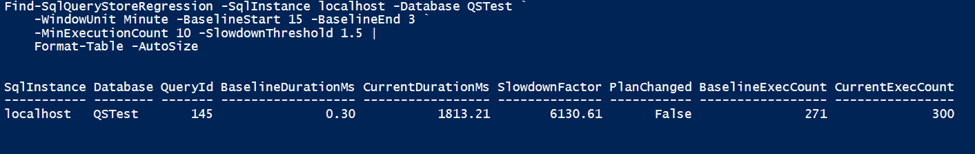
The query text is the same. Only the cost varies now because we are using the same plan, which now scans a couple hundred thousand rows instead of seeking. Therefore, we see the same query in the output, along with a baseline of the milliseconds it would take to complete the same request compared with the current milliseconds spent. This is exaggerated, for sure, since in real life we see no more than 2 or 10 times. However, this proves that the detection works for the appropriate query.
One more detail in the output is worth noting. It shows whether the plan changed during the process. In this case, it did not change, as there was no need. All that we did was drop the index; it did not change the plan, but it made it more expensive in terms of cost. This is why it is important to note that the two situations differ.
The Point
The Query Store is already familiar with your performance history. The problem has never been data. The issue has always been finding a way to convert data into actionable information that can be used without human intervention. The first step is giving weights according to executions so that the volume matters, making sure both windows are floored so that the noise does not matter.
Next, return objects instead of a downloadable report. This makes the difference between investigating which query failed at 2 o’clock in the morning and adding this process to a scheduled job.
Find-SqlQueryStoreRegression is one command in an early, actively developed module, so feedback and issues are genuinely welcome — SqlReliabilityKit on the PowerShell Gallery, source on GitHub.
Opinions expressed by DZone contributors are their own.
Comments