

Save Your Memory in JVM with Atomic*FieldUpdater
Learn how to be memory efficient when writing Java code with Atomic*FieldUpdater.
 CORE
·
A lot of people talk/write about premature optimization when they need to write "advanced" code and be a bit more memory efficient. But I am asking: Where does premature optimization start and where does it end? Is there any difference when you write an application or library?
Actually, I don't know the answer; I just want to put together some facts in today's blog and give a clue as to how to write a bit more memory efficient code. Let's introduce a not-so-familiar class from the java.util.concurrent package and compare it to the well-known java.util.concurrent.atomic.AtomicInteger.
A Very Common Implementation of AtomicCounter in Java
public class AtomicCounter {

    private final AtomicInteger counter = new AtomicInteger();

    public int incrementAndGet() {
        return counter.incrementAndGet();
    }

    public static void main(String[] args) {
        System.out.println(VM.current().details());
        System.out.println(ClassLayout.parseClass(AtomicCounter.class).toPrintable());
        System.out.println(ClassLayout.parseClass(AtomicInteger.class).toPrintable());
    }
}
Let's look at the Java object layout library (jol-core)to see what it looks like inside:
-XX:+CompressedOops
====================

pbouda.cracking.atomicupdater.AtomicCounter object internals:
 OFFSET  SIZE                                        TYPE DESCRIPTION           VALUE
      0    12                                             (object header)       N/A
     12     4   java.util.concurrent.atomic.AtomicInteger AtomicCounter.counter N/A
Instance size: 16 bytes
Space losses: 0 bytes internal + 0 bytes external = 0 bytes total

----------------------------------------------------------------------------------------------------

java.util.concurrent.atomic.AtomicInteger object internals:
 OFFSET  SIZE   TYPE DESCRIPTION                               VALUE
      0    12        (object header)                           N/A
     12     4    int AtomicInteger.value                       N/A
Instance size: 16 bytes
Space losses: 0 bytes internal + 0 bytes external = 0 bytes total

-XX:-CompressedOops
====================

pbouda.cracking.atomicupdater.AtomicCounter object internals:
 OFFSET  SIZE                                        TYPE DESCRIPTION           VALUE
      0    16                                             (object header)       N/A
     16     8   java.util.concurrent.atomic.AtomicInteger AtomicCounter.counter N/A
Instance size: 24 bytes
Space losses: 0 bytes internal + 0 bytes external = 0 bytes total

----------------------------------------------------------------------------------------------------

java.util.concurrent.atomic.AtomicInteger object internals:
 OFFSET  SIZE   TYPE DESCRIPTION                               VALUE
      0    16        (object header)                           N/A
     16     4    int AtomicInteger.value                       N/A
     20     4        (loss due to the next object alignment)
Instance size: 24 bytes
Space losses: 0 bytes internal + 4 bytes external = 4 bytes total
16 bytes (-XX:+UseCompressedOops) in total can be divided into several groups:
Our class AtomicCounter:
- 12 bytes — an object's header
- 8 bytes — MarkOOPS
- 4 bytes — KlassOOPS (
-XX:+UseCompressedOops) - 4 bytes — a reference to
AtomicInteger(only 4 bytes because of enabledCompressedOops)
AtomicInteger:
- 12 bytes — an object's header (
-XX:+UseCompressedOops) - 4 bytes — an integer value
Optimized Implementation With AtomicIntegerFieldUpdater
public class AtomicUpdater {

    private volatile int counter = 0;

    private static final AtomicIntegerFieldUpdater<AtomicUpdater> ATOMIC_COUNTER =
            AtomicIntegerFieldUpdater.newUpdater(AtomicUpdater.class, "counter");

    public int incrementAndGet() {
        return ATOMIC_COUNTER.incrementAndGet(this);
    }

    public static void main(String[] args) {
        System.out.println(VM.current().details());
        System.out.println(ClassLayout.parseClass(AtomicUpdater.class).toPrintable());
        System.out.println(ClassLayout.parseInstance(ATOMIC_COUNTER).toPrintable());
    }
}
-XX:+CompressedOops
====================
pbouda.cracking.atomicupdater.AtomicUpdater object internals:
OFFSET SIZE TYPE DESCRIPTION VALUE
0 12 (object header) N/A
12 4 int AtomicUpdater.counter N/A
Instance size: 16 bytes
Space losses: 0 bytes internal + 0 bytes external = 0 bytes total
----------------------------------------------------------------------------------------------------
=> Static variable => we pay only once
java.util.concurrent.atomic.AtomicIntegerFieldUpdater$AtomicIntegerFieldUpdaterImpl object internals:
OFFSET SIZE TYPE DESCRIPTION VALUE
0 4 (object header) 05 00 00 00 (00000101 00000000 00000000 00000000) (5)
4 4 (object header) 00 00 00 00 (00000000 00000000 00000000 00000000) (0)
8 4 (object header) 81 64 22 00 (10000001 01100100 00100010 00000000) (2253953)
12 4 java.lang.Class AtomicIntegerFieldUpdaterImpl.cclass (object)
16 8 long AtomicIntegerFieldUpdaterImpl.offset 12
24 4 java.lang.Class AtomicIntegerFieldUpdaterImpl.tclass (object)
28 4 (loss due to the next object alignment)
Instance size: 32 bytes
Space losses: 0 bytes internal + 4 bytes external = 4 bytes total
-XX:-CompressedOops
====================
pbouda.cracking.atomicupdater.AtomicUpdater object internals:
OFFSET SIZE TYPE DESCRIPTION VALUE
0 16 (object header) N/A
16 4 int AtomicUpdater.counter N/A
20 4 (loss due to the next object alignment)
Instance size: 24 bytes
Space losses: 0 bytes internal + 4 bytes external = 4 bytes total
----------------------------------------------------------------------------------------------------
=> Static variable => we pay only once
java.util.concurrent.atomic.AtomicIntegerFieldUpdater$AtomicIntegerFieldUpdaterImpl object internals:
OFFSET SIZE TYPE DESCRIPTION VALUE
0 4 (object header) 05 00 00 00 (00000101 00000000 00000000 00000000) (5)
4 4 (object header) 00 00 00 00 (00000000 00000000 00000000 00000000) (0)
8 4 (object header) e0 2d df 39 (11100000 00101101 11011111 00111001) (970927584)
12 4 (object header) f3 7f 00 00 (11110011 01111111 00000000 00000000) (32755)
16 8 long AtomicIntegerFieldUpdaterImpl.offset 16
24 8 java.lang.Class AtomicIntegerFieldUpdaterImpl.cclass (object)
32 8 java.lang.Class AtomicIntegerFieldUpdaterImpl.tclass (object)
Instance size: 40 bytes
Space losses: 0 bytes internal + 0 bytes external = 0 bytes total AtomicUpdater:
- 12 bytes — an object's header (
-XX:+UseCompressedOops) - 4 bytes — an integer value
Static variable (one-off cost)
- 32 bytes for
AtomicIntegerFieldUpdater
Where Are Those Savings?!
It's pretty obvious that if you use only one object (e.g. a singleton bean) with a counter, then the overhead for AtomicIntegerFieldUpdater is slightly bigger than in the case of AtomicInteger. However, what if we have a different case? What if we need to support atomicity in some certain object that is duplicated/cached thousands/millions of times on our heap? Let's see some results again:
public class Duplicator {

    public static void main(String[] args) throws InterruptedException {
        int count = 1_000_000;
        AtomicCounter[] cache = new AtomicCounter[count];
        for (int i = 0; i < count; i++) {
            cache[i] = new AtomicCounter();
//            cache[i] = new AtomicUpdater();
        }

        System.out.println("DONE!");
        Thread.currentThread().join();
    }
}
Let's see what is the objects' layout and class histogram in both solutions.
----------------------------------------------------------------------------------------------------
Class Statistics (JCMD)
----------------------------------------------------------------------------------------------------

-XX:+CompressedOops
====================

 num     #instances         #bytes  class name (module)
-------------------------------------------------------
   1:       1000003       16000048  java.util.concurrent.atomic.AtomicInteger (java.base@12)
   2:       1000000       16000000  pbouda.cracking.atomicupdater.AtomicCounter
   3:             1        4000016  [Lpbouda.cracking.atomicupdater.AtomicCounter;

-XX:-CompressedOops
====================

 num     #instances         #bytes  class name (module)
-------------------------------------------------------
   1:       1000003       24000072  java.util.concurrent.atomic.AtomicInteger (java.base@12)
   2:       1000000       24000000  pbouda.cracking.atomicupdater.AtomicCounter
   3:             1        8000024  [Lpbouda.cracking.atomicupdater.AtomicCounter;
----------------------------------------------------------------------------------------------------
Class Statistics (JCMD)
----------------------------------------------------------------------------------------------------
-XX:+CompressedOops
====================
num #instances #bytes class name (module)
-------------------------------------------------------
1: 1000000 16000000 pbouda.cracking.atomicupdater.AtomicUpdater
2: 1 4000016 [Lpbouda.cracking.atomicupdater.AtomicUpdater;
-XX:-CompressedOops
====================
num #instances #bytes class name (module)
-------------------------------------------------------
1: 1000000 24000000 pbouda.cracking.atomicupdater.AtomicUpdater
2: 1 8000024 [Lpbouda.cracking.atomicupdater.AtomicUpdater;Summary
We can see that for an absolutely negligible price (one instance of AtomicIntegerFieldUpdater), we are able to save 50 percent memory in this example. In some cases, it's very likely we don't have such small objects (only one counter), which means the ratio between both solutions could be smaller, but still, it can be worthwhile to implement it this way.
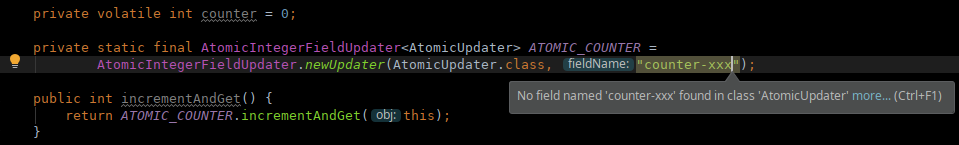
The only negative thing is reflection access to the class's field, which is written just like a string in our code. IntelliJ IDEA is able to mark a non-existing field as a warning, but understand it's still not the optimal solution. We need to pay some price for efficiency.
If you are interested in some other Atomic*FieldUpdater options, please look into the package called java.util.concurrent.atomic — you can get inspired to make your code more efficient.
And be sure to check out the source code for this post on GitHub.
Thank you for reading my article and please leave comments below! If you like being notified about new posts, then start following me on Twitter: @p_bouda.
Opinions expressed by DZone contributors are their own.