

Spark Streaming: Windowing
A tutorial on how data scientists can implement windowing functions in their Spark Streaming data sets using the Python language.
In our previous article, we talked about real-time streaming data.
Now, let's consider the idea of windows. In Spark Streaming, we have small batches to come in, so we have RDD and then we have another RDD and so on.
Spark batches the incoming data according to your batch interval, but sometimes you want to remember things from the past. Maybe you want to retain a rolling thirty second average for some of your streaming data, but you want results every five seconds. In this case, you’d want a batch interval of five seconds, but a window length of thirty seconds. Spark provides several methods for making these kinds of calculations.
What if I want to see the highest value after every thirty minutes, and also update us with the highest value every five seconds?
Then it's a real problem, as every five seconds we are going to get a new brand RDD but we need to remember the data from previous RDDs.
So the solution we have here is to use window functions.
Windows allow us to take a first batch and then a second batch and then a third batch and then create a window of all those batches based on the specified time interval. So this way we can always have the new RDD and also the history of the RDDs which existed in the window.
Window
The simplest windowing function is a window, which lets you create a new DStream, computed by applying the windowing parameters to the old DStream. You can use any of the DStream operations on the new stream, so you’ve got all the flexibility you could ever want.
For example, you want to POST all the active users from the last five seconds to a web service, but you want to update the results every second.
sc = SparkContext(appName="ActiveUsers")
ssc = StreamingContext(sc, 1)

activeUsers = [
    ["Alice", "Bob"],
    ["Bob"],
    ["Carlos", "Dan"],
    ["Carlos", "Dan", "Erin"],
    ["Carlos", "Frank"],
]

rddQueue = []
for datum in activeUsers:
    rddQueue += [ssc.sparkContext.parallelize(datum)]

inputStream = ssc.queueStream(rddQueue)
inputStream.window(5, 1)\
    .map(lambda x: set([x]))\
    .reduce(lambda x, y: x.union(y))\
    .pprint()

ssc.start()
sleep(5)
ssc.stop(stopSparkContext=True, stopGraceFully=True)
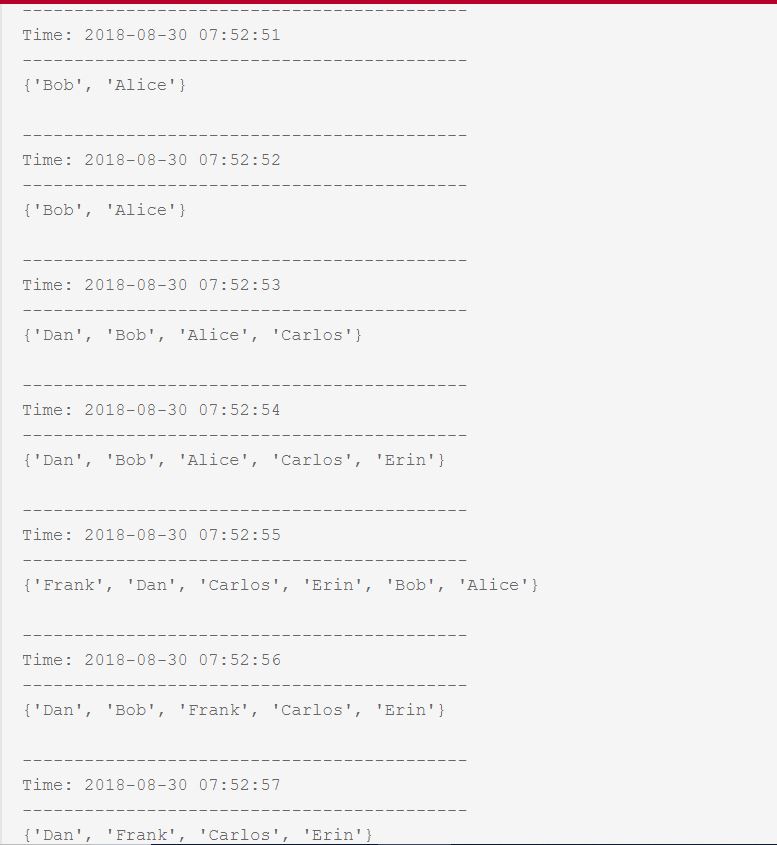
So we want to keep a list of Active Users, and print a list of all the users who are online. Also, if a new user checks in, we want to make sure the online users list gets updated with it. However, there could be some users who are online from the past couple of minutes but they are not active. That does not mean they are not online, so we want to keep all the online users in a list, even when they are not active. Keep on updating the list with any new users, as well, for every second. This is the implementation of the use case.
This example prints out all active users from the last five seconds, but it prints it every second. We don’t have to manually track state, because the window function keeps old data around for another four intervals. The window function lets you specify the window length and the slide duration, or how often you want a new window calculated.
Stay tuned for the reduceByKeyandWindow() function!
Opinions expressed by DZone contributors are their own.