

Using Mule 4 Batch for Loading a CSV File to a Database
See how to load a CSV file to a database using a batch.
In this article, I will explain how to load a CSV file to a database. For this, we will be using a CSV input file that contains a list of employees, and then we will insert that data into the MySQL database (you can use any database of your choice).
Mule can process messages in batches. It splits the large messages into individual records that are processed asynchronously within batch jobs.
Phases of Batch Jobs
Each batch job contains three different phases:
1. Load and Dispatch: This is an implicit phase. It works behind the scenes. In this phase, Mule turns the serialized message payload into collection of records for processing in the batch steps.
2. Process: This is the mandatory phase of the batch. It can have one or more batch steps to asynchronously process the records.
3. On Complete: This is the optional phase of the batch. It provides the summary of the records processed and helps the developer to get an insight which record was successful and which one failed so that you can address the issue properly.
failedRecords, loadedRecords, processedRecords, successfulRecords, totalRecords
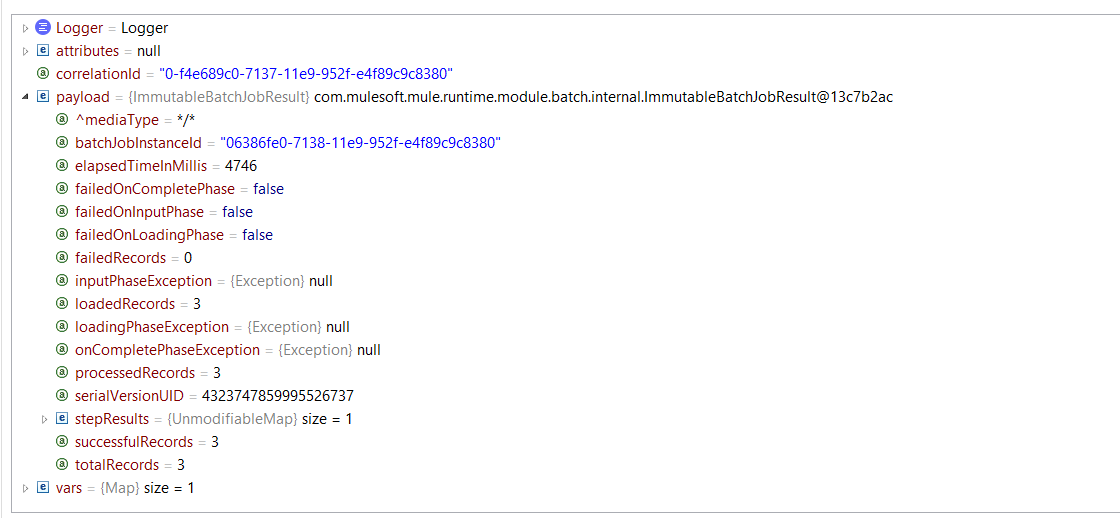
Sample CSV File:
id, name, department
10, Anil Singh, 10
20, Kuldeep Rana, 20
30, Ajay Bisht, 30
Mule Flow:
Create a Mule project in Anypoint Studio. The flow would look like this:
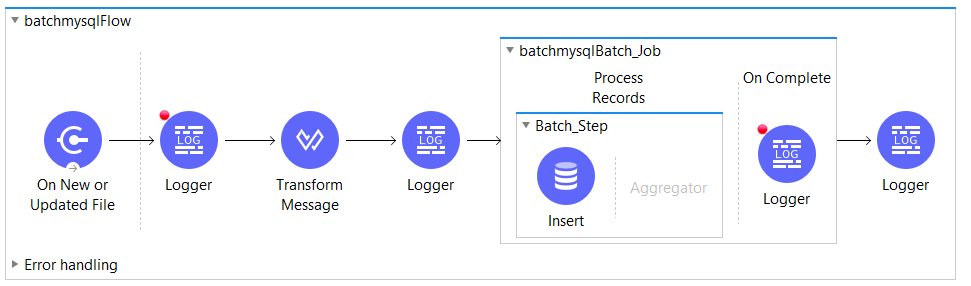
On New or Updated File Listener: In the Listener, configure the working directory (that contains the file) and make sure to move the input file to another directory after the file has been processed or else the flow will be recursive in nature and will be processed many times.
<file:listener doc:name="On New or Updated File" doc:id="0b3dd4ee-6a9e-448b-9344-044f7598f5ed" config-ref="File_Config" moveToDirectory="H:\mule-batch\archive">
<scheduling-strategy >
<fixed-frequency />
</scheduling-strategy>
<file:matcher filenamePattern="*.csv" />
</file:listener>
Transform Message (Dataweave 2.0): The Transform Message component transform the CSV file JSON payload, which then will be used by the batch job to insert the data into the database.
<ee:transform doc:name="Transform Message" doc:id="94fffbf0-8d2d-4123-94bc-f64a5a79587d" >
<ee:message >
<ee:set-payload ><![CDATA[%dw 2.0
output application/json
---
payload map {
id: $.id,
name: $.name,
department: $.department
}]]></ee:set-payload>
</ee:message>
</ee:transform>
Batch Job: Splits the transformed JSON payload into individual records to be processed inside the batch job.
<batch:job jobName="batchmysqlBatch_Job" doc:id="337e976a-2b15-4bba-acc3-041b5b321b36" >
<batch:process-records >
<batch:step name="Batch_Step" doc:id="a6b1973f-f04b-4e80-9fd9-3ad20fd91ca5" >
<db:insert doc:name="Insert" doc:id="1aac2fe1-1d5f-4800-82d5-525612cd4692" config-ref="Database_Config">
<db:sql >INSERT INTO developer3(id, name, department)
VALUES(:id, :name, :department)</db:sql>
<db:input-parameters ><![CDATA[#[payload]]]></db:input-parameters>
</db:insert>
</batch:step>
</batch:process-records>
<batch:on-complete >
<logger level="INFO" doc:name="Logger" doc:id="bbbcc89c-8005-4642-b930-ca2e17628b71" message="#[payload]"/>
</batch:on-complete>
</batch:job>
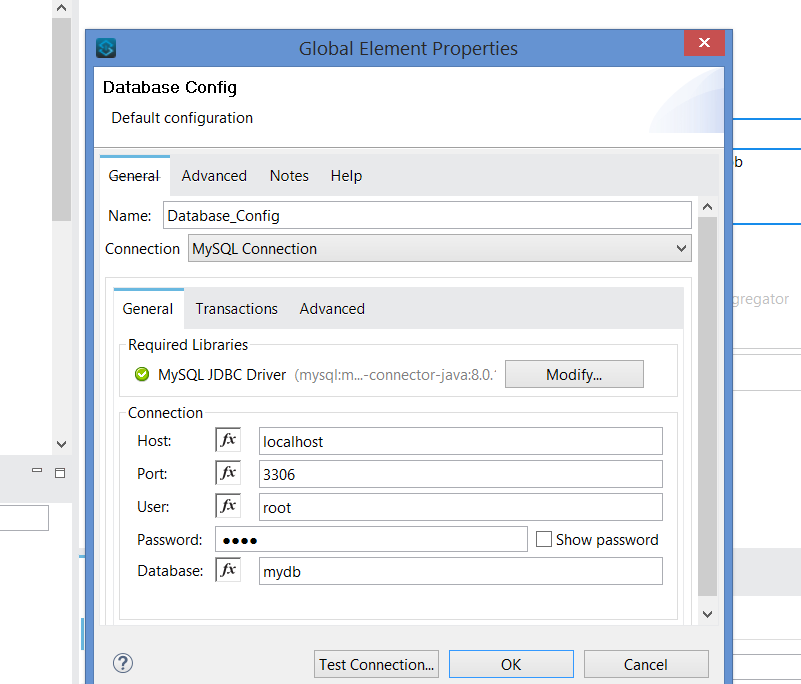
Database Insert: The database inert component lets us insert the data into our database by configuring the database connector with the required libraries and connection that include host, port, username, and password. Create the required table in the database to insert the data.
Database Configuration:
The Complete Code:
<?xml version="1.0" encoding="UTF-8"?>

<mule xmlns:batch="http://www.mulesoft.org/schema/mule/batch" xmlns:ee="http://www.mulesoft.org/schema/mule/ee/core"
xmlns:file="http://www.mulesoft.org/schema/mule/file"
xmlns:db="http://www.mulesoft.org/schema/mule/db" xmlns="http://www.mulesoft.org/schema/mule/core" xmlns:doc="http://www.mulesoft.org/schema/mule/documentation" xmlns:xsi="http://www.w3.org/2001/XMLSchema-instance" xsi:schemaLocation="http://www.mulesoft.org/schema/mule/core http://www.mulesoft.org/schema/mule/core/current/mule.xsd
http://www.mulesoft.org/schema/mule/db http://www.mulesoft.org/schema/mule/db/current/mule-db.xsd
http://www.mulesoft.org/schema/mule/file http://www.mulesoft.org/schema/mule/file/current/mule-file.xsd
http://www.mulesoft.org/schema/mule/ee/core http://www.mulesoft.org/schema/mule/ee/core/current/mule-ee.xsd
http://www.mulesoft.org/schema/mule/batch http://www.mulesoft.org/schema/mule/batch/current/mule-batch.xsd">
<db:config name="Database_Config" doc:name="Database Config" doc:id="a0756454-d6c9-477e-b1ed-bcf5ad58c23c" >
<db:my-sql-connection host="localhost" port="3306" user="root" password="test" database="mydb" />
</db:config>
<file:config name="File_Config" doc:name="File Config" doc:id="d8b07c72-be07-4465-a804-9094f65395a2" >
<file:connection workingDir="H:\mule-batch\input" />
</file:config>
<flow name="batchmysqlFlow" doc:id="6173077a-1d32-4e50-b123-4cc55436dc6d" >
<file:listener doc:name="On New or Updated File" doc:id="0b3dd4ee-6a9e-448b-9344-044f7598f5ed" config-ref="File_Config" moveToDirectory="H:\mule-batch\archive">
<scheduling-strategy >
<fixed-frequency />
</scheduling-strategy>
<file:matcher filenamePattern="*.csv" />
</file:listener>
<logger level="INFO" doc:name="Logger" doc:id="9d4a3e61-498c-4477-b84a-368bb7ffcd54" message="#[payload]"/>
<ee:transform doc:name="Transform Message" doc:id="94fffbf0-8d2d-4123-94bc-f64a5a79587d" >
<ee:message >
<ee:set-payload ><![CDATA[%dw 2.0
output application/json
---
payload map {
id: $.id,
name: $.name,
department: $.department
}]]></ee:set-payload>
</ee:message>
</ee:transform>
<logger level="INFO" doc:name="Logger" doc:id="9366b293-9ea8-4a25-bdec-e93553163962" message="#[payload]" />
<batch:job jobName="batchmysqlBatch_Job" doc:id="337e976a-2b15-4bba-acc3-041b5b321b36" >
<batch:process-records >
<batch:step name="Batch_Step" doc:id="a6b1973f-f04b-4e80-9fd9-3ad20fd91ca5" >
<db:insert doc:name="Insert" doc:id="1aac2fe1-1d5f-4800-82d5-525612cd4692" config-ref="Database_Config">
<db:sql >INSERT INTO developer3(id, name, department)
VALUES(:id, :name, :department)</db:sql>
<db:input-parameters ><![CDATA[#[payload]]]></db:input-parameters>
</db:insert>
</batch:step>
</batch:process-records>
<batch:on-complete >
<logger level="INFO" doc:name="Logger" doc:id="bbbcc89c-8005-4642-b930-ca2e17628b71" message="#[payload]"/>
</batch:on-complete>
</batch:job>
<logger level="INFO" doc:name="Logger" doc:id="d3e78f71-13f0-40ee-a1e1-639230370708" message="#[payload]"/>
</flow>
</mule>
The above Mule flow will successfully load your CSV file data into the database using the Batch job.
Happy learning!
Opinions expressed by DZone contributors are their own.