

Valkey: Bringing Key-Value Databases to Enterprise Java
Valkey provides high-performance key-value storage for Enterprise Java, with portable APIs and flexible persistence through Eclipse JNoSQL.
 CORE
·
Join the DZone community and get the full member experience.
Join For FreeEnterprise applications commonly face multiple data challenges. Some data requires transactional integrity and relationships, while other data prioritizes fast, predictable access. Sessions, counters, rate limits, temporary state, often-accessed objects, and coordination data may not benefit from the complexity of a relational model. In these cases, a key-value database's simplicity becomes an architectural advantage.
This simplicity is especially valuable in distributed and cloud-native systems, where latency, throughput, plus scalability directly shape user experience and infrastructure costs. A key-value database offers a focused approach: identify data by a key and retrieve or update it efficiently. The challenge is selecting a technology that delivers this performance while meeting the operational maturity, ecosystem support, and governance standards required for enterprise applications.
Valkey meets these needs successfully. Originating from the Redis OSS lineage and developed as a vendor-neutral open-source project under the Linux Foundation, Valkey delivers a high-performance key-value platform suitable for caching, application state, messaging, and primary data storage. Beyond being another database option, it lets organizations explore how key-value persistence fits into modern enterprise architecture and lets Java applications use its benefits without tightly coupling to a specific datastore.
Why Key-Value Databases Matter
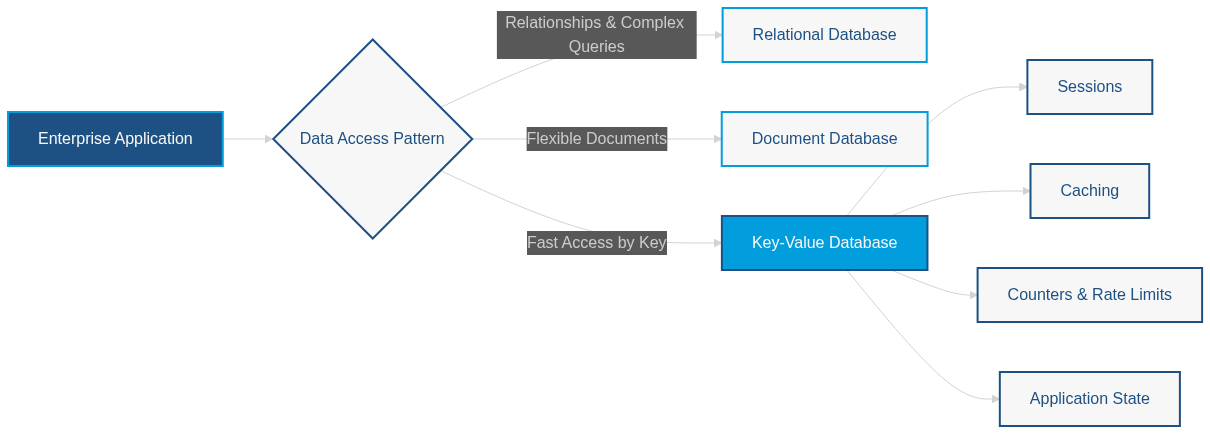
Key-value databases use a simple data model in which each unique key identifies a value. This simplicity is effective when applications can directly locate the required data. By enabling direct reads and writes, key-value databases typically deliver low latency, high throughput, and a horizontally scalable operational model.
In enterprise systems, this model suits scenarios such as distributed sessions, caching, counters, rate limiting, feature flags, shopping carts, temporary workflow state, idempotency keys, leaderboards, and frequently accessed application data. These workloads prioritize fast access by identifier over joins, ad hoc queries, or complex relational constraints.
The main architectural advantage of key-value databases is their specialization for specific access patterns, rather than universal speed or simplicity. When the primary requirement is to retrieve the current value for a given key, adding a more complex persistence model can introduce unnecessary overhead. As part of a polyglot persistence strategy, key-value stores enable architects to align the database model with the workload, rather than forcing all workloads into a single database.
Putting Valkey Into Practice With Jakarta NoSQL
A key advantage of using Valkey in enterprise Java is that it does not require a new programming model. With Jakarta NoSQL and Eclipse JNoSQL, Valkey serves as another key-value implementation behind a consistent API and mapping model. Domain annotations remain unchanged, so switching between key-value databases usually involves only updating the driver and its configuration, not rewriting the application.
This abstraction is valuable architecturally. The application relies on the Jakarta NoSQL contract, while Eclipse JNoSQL manages integration with the database. Although database-specific features may introduce some coupling, applications that use the portable API can switch key-value implementations with minimal impact.
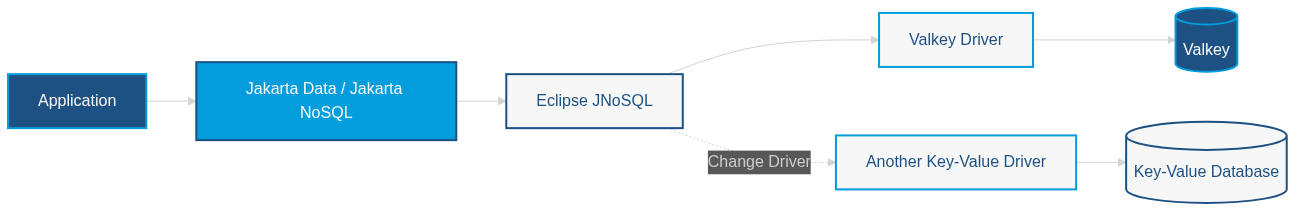
For this article, we will use a simple Java SE example. This persistence layer can later support a REST API, messaging consumer, scheduled process, or other enterprise architecture without altering the core database interaction.
Starting Valkey
The first step is to make a Valkey instance available. Docker provides a convenient way to start one locally:
docker run --name valkey-instance \
  -p 6379:6379 \
  -d valkey/valkey:latest
With Valkey running, add the Eclipse JNoSQL Valkey driver to the Jakarta NoSQL infrastructure, which includes CDI, Eclipse MicroProfile Config, and Jakarta JSON Processing.
<dependency>
    <groupId>org.eclipse.jnosql.databases</groupId>
    <artifactId>jnosql-valkey</artifactId>
    <version>${jnosql.version}</version>
</dependency>
Configure the connection externally:
jnosql.keyvalue.database=developers
jnosql.valkey.port=6379
jnosql.valkey.host=localhost
Since Eclipse JNoSQL integrates with Eclipse MicroProfile Config, you do not need to hard-code these values. They can be provided through configuration sources such as environment variables, in line with the Twelve-Factor App methodology.
Mapping an Entity
The mapping model for a key-value database is intentionally simple. Identify the class as an entity and specify the field that represents its key:
@Entity
public class User {

    @Id
    private String userName;

    private String name;

    private List<String> phones;

    // constructors, getters, setters...
}
Importantly, @Entity and @Id are part of the mapping abstraction, not Valkey itself. The domain model does not require Valkey-specific annotations.
Using Jakarta NoSQL
Eclipse JNoSQL provides KeyValueTemplate, a specialization of the Jakarta NoSQL Template API for key-value databases. This allows direct persistence and retrieval of entities:
User user = User.builder()
        .phones(Arrays.asList("234", "432"))
        .username("username")
        .name("Name")
        .build();

KeyValueTemplate template =
        container.select(KeyValueTemplate.class).get();

User userSaved = template.put(user);

System.out.println("User saved: " + userSaved);

Optional<User> userFound =
        template.get("username", User.class);

System.out.println("Entity found: " + userFound);
For applications that prefer a repository abstraction, Eclipse JNoSQL integrates with Jakarta Data:
@Repository
public interface UserRepository extends CrudRepository<User, String> {
}
This approach allows the application code to focus more directly on domain operations:
User user = User.builder()
        .phones(Arrays.asList("234", "432"))
        .username("username")
        .name("Name")
        .build();

UserRepository repository = container
        .select(
            UserRepository.class,
            DatabaseQualifier.ofKeyValue()
        )
        .get();

repository.save(user);

Optional<User> userFound =
        repository.findById("username");

System.out.println("User found: " + userFound);
Notably, this code includes no Valkey-specific API in the entity or repository. Valkey is an infrastructure choice, while Jakarta NoSQL and Jakarta Data remain the application-facing abstractions. This separation guarantees the architecture remains reusable if the underlying key-value technology changes.
Conclusion
Key-value databases are highly effective for workloads that require direct access, low latency, and high throughput, rather than complex queries or relational navigation. This article examined how this model fits within enterprise architecture and how Valkey can integrate via Eclipse JNoSQL, allowing applications to avoid direct dependencies on vendor-specific APIs. By maintaining consistent entity mapping and using Jakarta NoSQL or Jakarta Data abstractions, switching key-value implementations becomes mainly a matter of infrastructure and configuration.
This shift reflects a broader evolution in enterprise Java, as the platform expands its persistence capabilities beyond traditional relational databases. With Jakarta Persistence, Jakarta Data, Jakarta NoSQL, and tools like Eclipse JNoSQL, architects can choose the best data model for each workload while keeping familiar programming abstractions. Valkey enhances this ecosystem by providing a robust key-value option, making polyglot persistence both feasible and practical.
Opinions expressed by DZone contributors are their own.
Comments