
DZone
Thanks for visiting DZone today,
Edit Profile
  • Manage Email Subscriptions
  • How to Post to DZone
  • Article Submission Guidelines
Sign Out View Profile
  • Post an Article
  • Manage My Drafts
Newsletter
Log In / Join
Refcards Trend Reports
Events Video Library
Refcards
Trend Reports

Events

View Events Video Library

Related

  • Why Round-Robin Won't Save You: Load Balancing Challenges in Data Streaming Services With Heterogeneous Traffic
  • Beyond Partitioning and Z-Order: A Deep Dive into Liquid Clustering for Unity Catalog Managed Tables
  • Data Partitioning and Bucketing: How Modern Data Systems Organize and Optimize Your Data
  • Optimizing Data Storage With Hybrid Partitioned Tables in Oracle 19c

Trending

  • Managing Technical Debt in AI-Generated Code
  • Designing a Polling Pipeline for Rate-Limited APIs Without Losing Data
  • Java 27 Makes G1 the Default Everywhere: How to Test Your Small Containers Before You Upgrade
  • Member Spotlight: Srinivas Chippagiri

Draft This article hasn't been published, so readers can't see it.

In moderation This article is waiting for review, so readers can't see it yet.

Deleted This article has been deleted, so readers can't see it.

  1. DZone
  2. Data Engineering
  3. Databases
  4. Apache Spark: Spark Union Adds Up the Partition of Input RDDs

Apache Spark: Spark Union Adds Up the Partition of Input RDDs

Learn about the behavior of Apache Spark's RDD partitions during a union operation and the different cases in which you might find unknown results during the operation.

By 
Rishi Khandelwal
·
Apr. 13, 17 · Tutorial
Post on X (opens in a new tab) Share on LinkedIn (opens in a new tab)
11.6K Views

Join the DZone community Save articles, join the discussion, and download Refcards and Trend Reports with a free account.

Join for free Already a member? Log in

Back when I was doing a union of two-pair RDDs, I found a strange behavior regarding the number of partitions. The output RDD got a different number of partitions than the input RDD.

For example, suppose rdd1 and rdd2 each have two partitions. After the union of these RDDs, I was expecting the same number of partitions for the output RDD. But the output RDD showed the number of partitions as being the sum of the partitions of the input RDDs.

After doing some research, I found that the partitioner has an impact on this strange behavior. More details on the partitioner can be found here.

I found two cases, which are described below, in which that strange behavior can happen.

Case 1

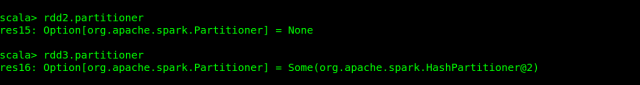
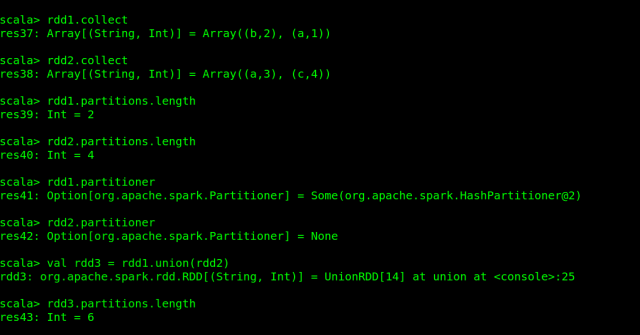
If the partitioner is different for both input RDDs, then the output RDD will have partitions as the sum of the partitions of the input RDD. To check the partitioner, do the following:
1

Here, different partitioners have two meanings:

  1. Both input RDDs have different partitioners. For example, rdd1 has a hash partition and rdd2 has a range partitioner.
  2. One RDD has partitioners and the other one doesn't.
2

You can see in above example, that rdd1 has HashPartitioner with two partitions while rdd2 does not have any partitioner with four partitions. After the union of these two, the output rdd3 has 6 (2 + 4) partitions.

Case 2

If the partitioner is the same for both input RDDs but the number of partitions is different, then the output RDD will get the partitions as the sum of the partitions of input RDDs.

3

As you can see in the above example, both input RDDs have the same partitioner but with a different number of partitions — rdd1 has 2 while rdd2 has 3. So, after union, the output rdd3 has 5 (2 + 3) partitions.

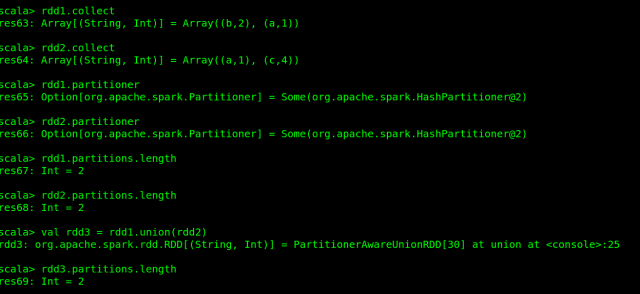
You can see below that what happens when both partitioners and the number of partitions are the same for both input RDDs.
4

In above example, the output rdd3 has the same number of partitions as the input RDD.

Partition (database)

Published at DZone with permission of Rishi Khandelwal. See the original article here.

Opinions expressed by DZone contributors are their own.

Related

  • Why Round-Robin Won't Save You: Load Balancing Challenges in Data Streaming Services With Heterogeneous Traffic
  • Beyond Partitioning and Z-Order: A Deep Dive into Liquid Clustering for Unity Catalog Managed Tables
  • Data Partitioning and Bucketing: How Modern Data Systems Organize and Optimize Your Data
  • Optimizing Data Storage With Hybrid Partitioned Tables in Oracle 19c

Partner Resources

×

Comments

Loading comments

The comments didn't load

Please try again in a moment.

Likes

Loading

The next likes didn't load. Please try again.

The likes didn't load

Please try again in a moment.

See who liked this

Log in or join DZone for free to see who liked this article.

Log in Join for free
  • RSS
  • X
  • Facebook

ABOUT US

  • About DZone
  • Support and feedback
  • Community research

ADVERTISE

  • Advertise with DZone

CONTRIBUTE ON DZONE

  • Article Submission Guidelines
  • Become a Contributor
  • Core Program
  • Visit the Writers' Zone

LEGAL

  • Terms of Service
  • Privacy Policy

CONTACT US

  • 3343 Perimeter Hill Drive
  • Suite 215
  • Nashville, TN 37211
  • [email protected]

Let's be friends:

  • RSS
  • X
  • Facebook