

Mule 4: Fixed Width Data to JSON Transformation Using CopyBook
Let's take a quick look at the fixed width data to JSON transformation using CopyBook. Explore the use case and the Mule flow.
CopyBook is nothing but a section of code written in high-level language. It gives the schema structure and used in Mainframes for accessing the backend data into other applications. And it is originated from COBOL on IBM mainframe operating systems.
Use Case:
Transforming Fixed Width data to JSON format using COBOL CopyBook schema.
Mule Flow:
Step 1:
Configure the HTTP Listener with by giving hostname, port number and path along with this specify allowed methods (Optional) at the Advanced tab of HTTP connector.
Step 2:
Drag and drop the Set Payload from Mule Palette to validate the input payload using COBOL CopyBook Schema. And specify the schema path at MIME Type tab. In my case, it is like below:
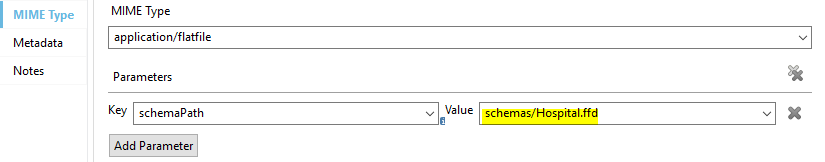
From the above line:
schemas --> It is a directory
Hospital.ffd ---> It is CopyBook schema for validation.
Below is the Hospital.ffd schema for the reference:
form: COPYBOOK
id: 'HOSPITALSCOPYBOOK'
values:
- name: 'HOSPITALS'
  values:
  - name: 'BASIC-INFO'
    values:
    - { name: 'NAME', type: String, length: 4 }
    - { name: 'ADDRESS', type: String, length: 4 }
    - { name: 'PHONE-NUMBER', type: Integer, length: 10, format: { justify: ZEROES, sign: UNSIGNED } }
    - { name: 'ADMIN', type: String, length: 4 }
- name: 'WARDS'
  values:
  - name: 'BASIC-INFO'
    values:
    - { name: 'NAME', type: String, length: 4 }
    - { name: 'ADDRESS', type: String, length: 4 }
    - { name: 'NUMBER', type: Integer, length: 10, format: { justify: ZEROES, sign: UNSIGNED } }
    - { name: 'ADMIN', type: String, length: 4 }
Step 3:
Drag and drop the Transform Message component for data format conversion.
Step 4:
Drag and drop the Logger component to log the resultant payload after validation.
Final Config.xml:
<?xml version="1.0" encoding="UTF-8"?>

<mule xmlns:ee="http://www.mulesoft.org/schema/mule/ee/core" xmlns:http="http://www.mulesoft.org/schema/mule/http"
xmlns="http://www.mulesoft.org/schema/mule/core"
xmlns:doc="http://www.mulesoft.org/schema/mule/documentation" xmlns:xsi="http://www.w3.org/2001/XMLSchema-instance" xsi:schemaLocation="http://www.mulesoft.org/schema/mule/core http://www.mulesoft.org/schema/mule/core/current/mule.xsd
http://www.mulesoft.org/schema/mule/http http://www.mulesoft.org/schema/mule/http/current/mule-http.xsd
http://www.mulesoft.org/schema/mule/ee/core http://www.mulesoft.org/schema/mule/ee/core/current/mule-ee.xsd">
<http:listener-config name="HTTP_Listener_config" doc:name="HTTP Listener config" doc:id="84a3c2a5-c4d6-41bb-86c0-53a10f8bcf89" >
<http:listener-connection host="0.0.0.0" port="8082" />
</http:listener-config>
<flow name="hospital-flatfileFlow" doc:id="b232ad22-9adf-484a-82af-aa94dee96f72" >
<http:listener doc:name="Listener" doc:id="3689e2de-d1f3-4f80-8a8e-dc5a8a631870" config-ref="HTTP_Listener_config" path="/ff" allowedMethods="POST"/>
<set-payload value="#[payload]" doc:name="Set Payload" doc:id="3aafc767-ed26-4211-a6ca-f427ade9eb78" mimeType='application/flatfile; schemapath="schemas/Hospital.ffd"'/>
<ee:transform doc:name="Transform Message" doc:id="5dcfb492-24ec-4868-8b0b-d1e7393ff93d" >
<ee:message >
<ee:set-payload ><![CDATA[%dw 2.0
output application/json
---
payload map ( payload01 , indexOfPayload01 ) -> {
HospitalsCopyBook: {
Hospitals: {
"Basic-Info": {
Name: payload01.HOSPITALS."BASIC-INFO".NAME default "",
Address: payload01.HOSPITALS."BASIC-INFO".ADDRESS default "",
"Phone-Number": payload01.HOSPITALS."BASIC-INFO"."PHONE-NUMBER" default 0,
Admin: payload01.HOSPITALS."BASIC-INFO".ADMIN default ""
}
},
Wards: {
"Basic-Info": {
Name: payload01.WARDS."BASIC-INFO".NAME default "",
Address: payload01.WARDS."BASIC-INFO".ADDRESS default "",
Number: payload01.WARDS."BASIC-INFO".NUMBER default 0,
Admin: payload01.WARDS."BASIC-INFO".ADMIN default ""
}
}
}
}]]></ee:set-payload>
</ee:message>
</ee:transform>
<logger level="INFO" doc:name="Logger" doc:id="df684849-aa1e-448d-8fbc-36b593ad2374" message="#[message.payload]"/>
</flow>
</mule>
Sample Input (POST):
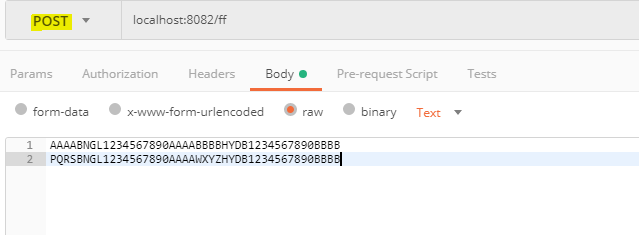
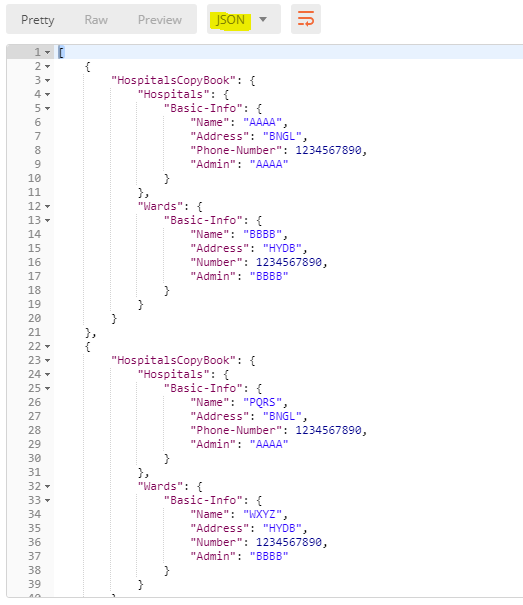
Output:
Happy learning!
Opinions expressed by DZone contributors are their own.