

AI-Era Cybersecurity, Part 1: Mapping Glasswing, Daybreak, Lightwell and the Tools Racing to Find and Fix Bugs
AI is now used on both sides of the vulnerability fight: it finds bugs faster for defenders and shortens the time attackers need to weaponize them.
 CORE
·
Join the DZone community and get the full member experience.
Join For FreeEvery few weeks, a new name shows up in security news. Project Glasswing. Daybreak. Lightwell. CodeMender. Big Sleep. Each one is presented as the next answer to AI-driven cyberattacks.
It is easy to read this as a race between AI labs, cloud providers, and security vendors, and to ask which one will win.
That is the wrong question. Each of these programs strengthens a different part of the same system. Some improve discovery. Some help engineers understand which bugs actually matter. Some generate patches. Some govern who is allowed to use powerful cyber tools at all. None of them, on its own, is a complete answer.
The useful question for a security team is not which vendor we should bet on. It is which part of our own system is weakest, and which of these pieces fills that gap.
This article lays out the evidence for why the pace of the problem has changed, walks through the lifecycle every vulnerability goes through, maps the current tools, programs, and rulebooks onto that lifecycle, and then treats AI agents themselves as a new class of identity that needs the same governance as any other. Along the way, I point to my own earlier articles where they cover the underlying engineering discipline in more depth.
Why the Old Patch Cycle No Longer Works
The pressure is not hypothetical. A few figures, each traceable to its source, show the shape of the problem.
| Signal | What it shows | Source |
|---|---|---|
| A record 48,185 CVEs were published in 2025, a 263 percent rise from 2020 | The volume of vulnerabilities to sort through has grown far faster than security teams have | Cloud Security Alliance, "The Collapsing Exploit Window" |
| Mandiant's M-Trends 2026 puts mean time to exploit at roughly negative seven days for high-value targets | Attacks now often begin before a fix is even public | Mandiant M-Trends 2026, Google Cloud |
| CISA's Binding Operational Directive 26-04 requires a three-day fix for vulnerabilities that meet four risk criteria | The US federal government has formally shortened its own patch deadlines because of AI-accelerated exploitation | CISA, Binding Operational Directive 26-04 |
| The average KEV catalog patch deadline in 2026 is 14.4 days, down from 19.7 the year before | Deadlines across the board are compressing, not just for the most severe bugs | Federal News Network, May 2026 |
| AI agents found and helped fix 1,072 Chrome security bugs across two releases in June 2026, more than the previous 23 releases combined | Discovery tooling has genuinely gotten faster, not just louder in marketing | Google, "Stronger with every update" |
None of this changes how many hours are in your team's week. The number that actually matters is the one CISA is trying to compress by regulation: the time between a fix exists and the fix is live in production. Every program in this article is, in one way or another, trying to shrink that number.
The Lifecycle Every Vulnerability Goes Through
Before comparing tools, it helps to agree on the steps a single weakness goes through, from discovery to a proven fix.
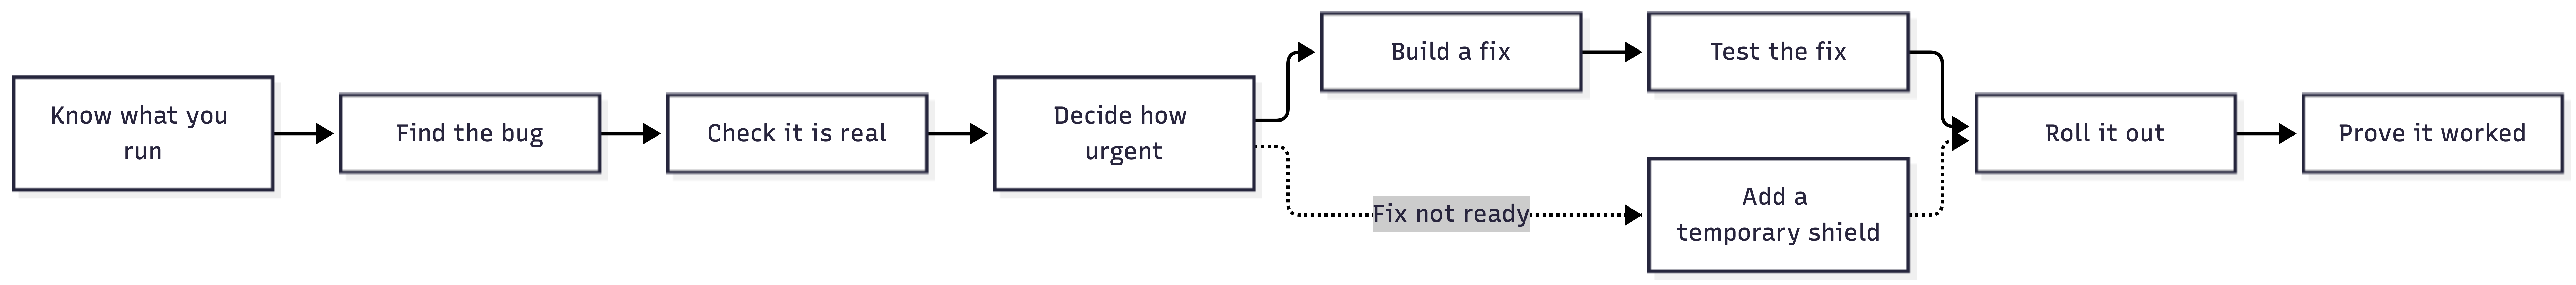
Discovery has become cheap. Deciding, fixing safely, and rolling out remain slow, mostly because they need judgment, testing, and coordination across teams. That is where most vulnerability management programs still struggle, and it is where the new wave of AI security tools is trying to help.
This lifecycle is also a loop, not a straight line. A better way to see the whole program is as a continuous cycle that feeds back into itself.

Discovery finds what might be wrong. Context asks whether the vulnerable component is actually reachable, deployed, and exposed. Prioritization ranks it against everything else competing for the same engineering hours. Remediation turns a finding into an engineering change: a dependency bump, a code fix, a rotated credential, a corrected IAM policy. Governance makes sure the whole process is reviewable, approved where it needs to be, and evidenced. Learning feeds what was found back into better defaults so the same class of issue shows up less often.
I covered the review and testing discipline that sits behind the remediation and governance stages in Code Review Core Practices, which stays relevant even when the patch is drafted by an AI agent rather than a person.
Three Programs, Three Different Jobs
Three named programs currently dominate the conversation. Each one is strongest at a different point in the lifecycle above.
Project Glasswing: Discovery at the Infrastructure Layer
Anthropic launched Project Glasswing in April 2026. Launch partners include Amazon Web Services, Apple, Cisco, CrowdStrike, Google, JPMorganChase, the Linux Foundation, Microsoft, NVIDIA, and Palo Alto Networks, working with Claude Mythos Preview on defensive tasks. Anthropic committed up to 100 million dollars in usage credits and 4 million dollars in donations to open source security groups, and later extended access to roughly 150 more organizations across more than fifteen countries (Anthropic, Project Glasswing).
The program targets critical infrastructure and widely used open source software, giving trusted defenders early access to a strong model before similar capability becomes broadly available. Mozilla has reported that the underlying model helped it find and patch 271 vulnerabilities in a recent Firefox release.
OpenAI Daybreak: Tiered Access for Defenders
OpenAI announced Daybreak on May 11, 2026, describing it as bringing together its frontier models, Codex Security, and a network of security partners to accelerate cyber defense and build security into software from the design stage rather than only patching after the fact (OpenAI, Daybreak).
Access is split into two tiers that require separate approval.
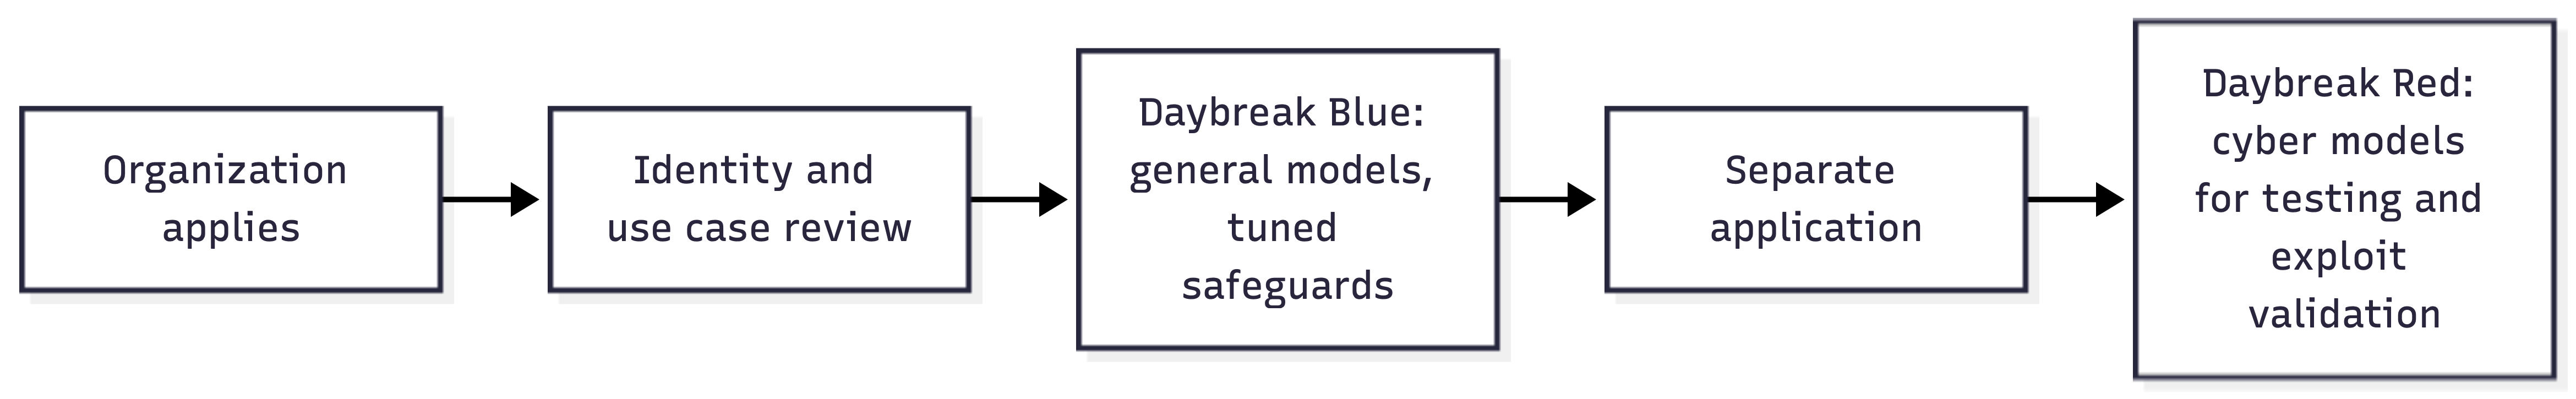
In September 2026, OpenAI added a subsidized access tier for organizations that keep essential services running, describing it as billions of dollars in access over roughly six months.
Project Lightwell: Fixing Open Source Without Breaking Production
IBM and Red Hat announced Project Lightwell on May 28, 2026, as a five-billion-dollar commitment backed by a global force of more than 20,000 engineers, and moved it to commercial launch on July 8 (IBM Newsroom, May 28, 2026; IBM Newsroom, July 8, 2026).
It targets a specific and common problem. A library has a known bug. The official fix is a newer version, but the newer version breaks a certified production setup. Lightwell Network launched with a catalog of more than 6,500 remediated, signed, and certified dependencies across ecosystems such as Java and Python, giving teams a patched version of the release they already run instead of forcing a risky upgrade. Lightwell Clearinghouse Premier, in limited availability, adds coordinated patch embargo handling. In August 2026, IBM and Red Hat extended free access to more than 185 universities and 100 NGOs and think tanks that lack the engineering capacity to keep pace on their own (IBM Newsroom, August 4, 2026).
Comparing the Three
| Glasswing | Daybreak | Lightwell | |
|---|---|---|---|
| Led by | Anthropic and partners | OpenAI and partners | IBM and Red Hat |
| Core question | Where are the bugs in critical software? | How can defenders use strong AI safely? | How do we fix open source bugs without breaking production? |
| Strongest lifecycle steps | Find, patch | Find, check, prove | Fix, test, roll out |
| Access model | Invited partners, expanding | Approved defenders, two tiers | Paid subscription, with free access for universities and NGOs |
| Primary scope | Critical and open source infrastructure | An organization's own code and systems | Open source dependencies in production |
| Main limitation | Mostly invite-based | Separate approval for each tier | Covers dependencies, not custom code |
Tools That Find and Patch Code Directly
Alongside the three named programs, a set of tools now work directly inside the discovery and fix stages.
| Tool | Owner | Function | Lifecycle step | Source |
|---|---|---|---|---|
| Big Sleep | Google DeepMind and Project Zero | Searches for memory safety bugs in widely used code | Find | Google, Chrome security blog |
| CodeMender | Google DeepMind | Patches new bugs and rewrites existing code to remove whole classes of bugs | Find, fix | DeepMind, "Introducing CodeMender" |
| Codex Security | OpenAI | Builds an editable threat model from a repository and generates and tests patches | Find, check | OpenAI, Daybreak |
| Claude Security | Anthropic | Public beta for organizations outside Glasswing | Find, check | Anthropic, Project Glasswing |
DeepMind is explicit that every CodeMender patch is reviewed by a person before it ships. That single fact matters more than the raw bug counts. It matches a habit I described in Ansible Code Scanning and Quality Checks With SonarQube: automated scanning finds candidates, but a human still signs off before anything reaches production.
There is also support work happening around the big three programs, aimed at a second-order problem: faster discovery means more reports than open source maintainers can review. Anthropic has partnered with the Open Source Security Foundation's Alpha-Omega project to help maintainers triage incoming reports, and OpenAI's Daybreak commitment includes direct funding for groups such as Trail of Bits. Palo Alto Networks has also worked with IBM and Red Hat so its network-level protections can block attacks while a Lightwell fix is tested and rolled out, a practice known as virtual patching. It buys time. It does not replace the fix.
What This Sets Up
Discovery is now genuinely fast. Three well-funded programs and a handful of dedicated tools are throwing real capability at the find-the-bug and build-the-fix steps of the lifecycle.
But finding more bugs faster does not, by itself, get you a faster or safer program. It just moves the bottleneck. The next problem is knowing which of those findings actually matter, making sure the AI agents doing this work are governed like the privileged systems they are, and having a plan that does not depend on an invitation to any of these programs.
That is where Part 2 picks up.
Further Reading
Opinions expressed by DZone contributors are their own.
Comments