

Share Delta Lake Tables Between Databricks and Snowflake
Learn how to share Delta Lake tables and ensure interoperability by using shared object storage (ADLS) and open table formats.
This article outlines how Delta Lake tables managed in Databricks and those managed in Snowflake can be shared in both directions without duplicating data. This is achieved through the use of shared object storage (ADLS) and open table formats. The article discusses the benefits, tradeoffs, business and cost advantages, the approach to implementation, and main technical aspects to consider.
Overview
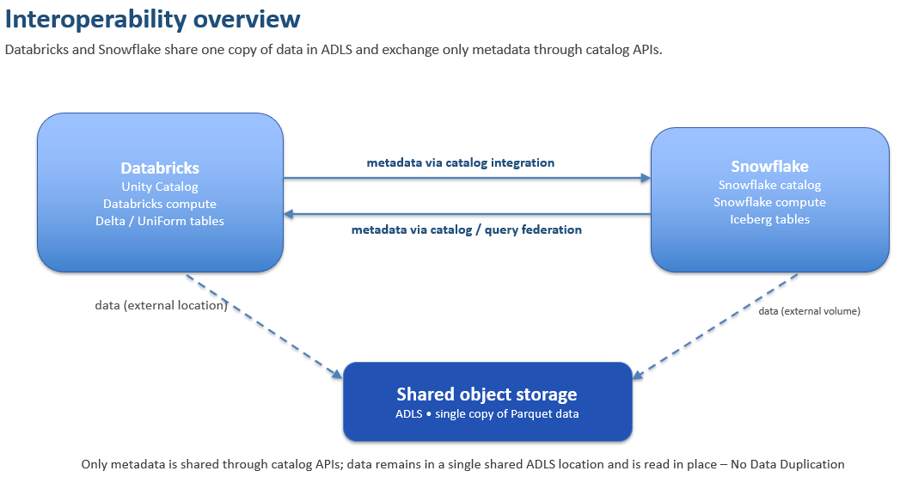
Interoperability enables one platform to access data that is owned by another platform, without moving the data.Both Databricks and Snowflake store a single copy of the underlying Parquet files in ADLS, and they share only table metadata through catalog APIs. Databricks stores data in Delta (or Delta Uniform), which Snowflake can read via catalog integration.On the other hand, Snowflake-managed Iceberg tables can be accessed by Databricks through catalog federation.
Key Advantages
- No data duplication: One physical copy of data in ADLS serves both engines, eliminating duplicate storage and copy pipelines.
- Meet users where they are: Producers publish once; consumers query from Databricks or Snowflake with their own compute.
- Best-of-breed & open formats: Open Parquet + Delta/Iceberg formats avoid lock-in and support future OLTP/OLAP convergence.
- Fresher data: Consumers read the latest committed metadata rather than a stale nightly extract.
Pros and Cons
| Points to consider | |
|---|---|
|
Pros |
Cons / Limitations |
|
No storage duplication — single copy in ADLS. |
Cross-engine writes are limited; the consuming engine is typically read-only. |
|
Lower latency than nightly copy / ETL jobs. |
Metadata refresh must be configured; a lag exists between write and visibility. |
|
Uses each engine's native compute and cost model. |
Converting Snowflake tables to Iceberg can surface datatype mismatches. |
|
Open formats reduce vendor lock-in. |
Governance must be re-applied per engine—policies do not travel with the table. |
Business and Cost Benefits
- Lower cost: Removes redundant storage and the compute cost of copy/sync pipelines between the two platforms.
- Speed: Lower data and process latency means data products reach consumers sooner (faster GTM).
- Compliance: A single governed copy supports data minimization and retention obligations.
- Agility: Teams pick the right tool for each workload without re-platforming the underlying data.
Databricks to Snowflake: Implementation Approach
Databricks owns the Delta/Uniform table, while Snowflake retrieves metadata through the Catalog Integration API and reads the data directly from ADLS.
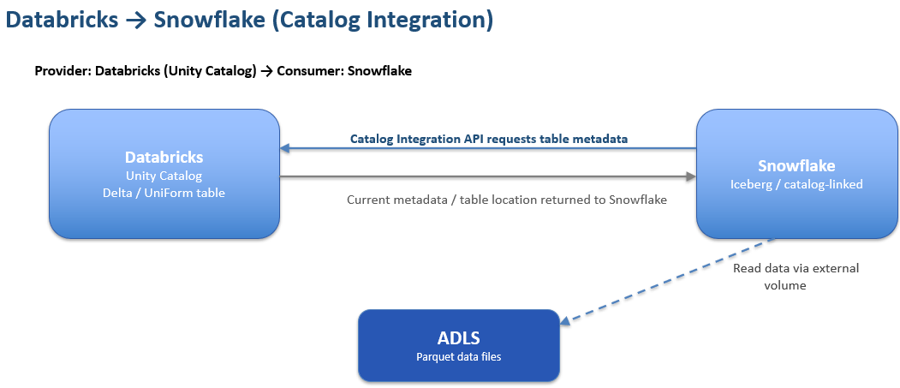
Snowflake requests metadata from Unity Catalog, receives the table location, and reads Parquet data directly from ADLS using an external volume.
Databricks-Managed Delta Read by Snowflake (Catalog Integration)
Databricks remains the owner; Snowflake reads in place.
1. Create external Delta tables with UniForm (Iceberg) enabled in ADLS, registered in Unity Catalog.
CREATE TABLE Catalog.SchemaName.TableName (
ID INT,
Name STRING,
CreatedAt TIMESTAMP
)
TBLPROPERTIES (
'delta.columnMapping.mode'='name',
'delta.enableIcebergCompatV2'='true',
'delta.universalFormat.enabledFormats'='iceberg'
 );
2. Create an external volume in Snowflake pointing to the ADLS path (Managed Identity authentication).
CREATE OR REPLACE EXTERNAL VOLUME DEVTEAMADLS_EXE_VOL
STORAGE_LOCATIONS = (
(
NAME='DEVTEAMADLS_EXE_VOL',
STORAGE_PROVIDER='AZURE',
STORAGE_BASE_URL='azure://devteamadls.blob.core.windows.net/Data/',
AZURE_TENANT_ID='<tenant id>'
)
 );
3. Create a catalog integration so Snowflake reads current metadata from Unity Catalog's Iceberg REST endpoint.
CREATE OR REPLACE CATALOG INTEGRATION DEVADLS_CATALOG_REST
CATALOG_SOURCE = ICEBERG_REST
TABLE_FORMAT = ICEBERG
CATALOG_NAMESPACE = 'SchemaName'
REST_CONFIG = (
CATALOG_URI = 'https://<workspace>.azuredatabricks.net/api/2.1/unity-catalog/iceberg',
WAREHOUSE = 'DevDeltaLake_Warehouse'
)
REST_AUTHENTICATION = (
TYPE = OAUTH,
OAUTH_TOKEN_URI = 'https://<workspace>.azuredatabricks.net/oidc/v1/token',
OAUTH_CLIENT_ID = '<shared via secure exchange>',
OAUTH_CLIENT_SECRET = '<shared via secure exchange>',
OAUTH_ALLOWED_SCOPES = ('all-apis','sql')
)
   ENABLED = TRUE;
4. Create the Iceberg table in Snowflake and apply RBAC + masking on the Snowflake side.
CREATE ICEBERG TABLE SFDBName.SFSchema.SFTableName
EXTERNAL_VOLUME = 'DEVTEAMADLS_EXE_VOL'
CATALOG = 'DEVADLS_CATALOG_REST'
CATALOG_TABLE_NAME = 'DeltaTableName'
CATALOG_NAMESPACE = 'DeltaSchemaName'
AUTO_REFRESH = TRUE;

ALTER ICEBERG TABLE ...
 MODIFY COLUMN <col> SET MASKING POLICY <policy>;
Snowflake to Databricks: Implementation Approach
Snowflake remains the owner; Databricks reads in place. Query federation is the lighter alternative when Iceberg conversion is not desired. Snowflake owns the Iceberg table; Databricks federates the catalog and reads data in place from ADLS.
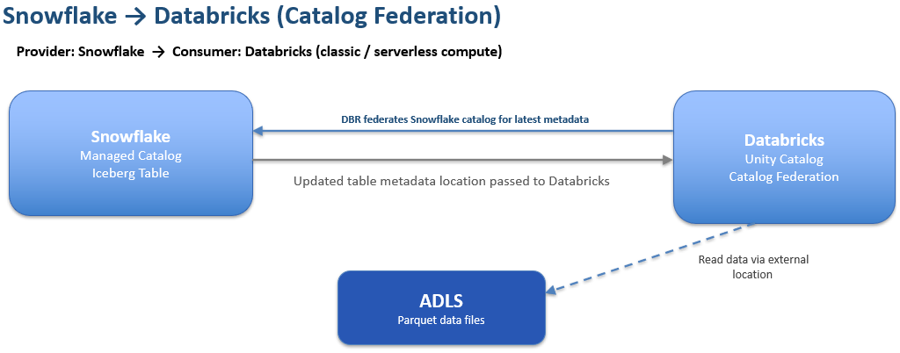
Databricks federates the Snowflake catalog to retrieve the latest metadata, receives the updated table location, and reads Parquet data directly from ADLS through an external location using Managed Identity.
Snowflake-Managed Data Read by Databricks (Catalog Federation)
1. Create Iceberg tables in the Snowflake-managed catalog on an external volume path.
CREATE OR REPLACE ICEBERG TABLE WareHouse.Schema.TableName (
c_custkey INTEGER,
c_name STRING,
c_acctbal INTEGER
)
CATALOG = 'SNOWFLAKE'
EXTERNAL_VOLUME = 'my_ext_vol'
 BASE_LOCATION = 'schema/tablename';
2. Provision a resource account (key pair) and grant Databricks' role read access to the Iceberg tables.
ALTER USER UserName SET RSA_PUBLIC_KEY='<public key>';

GRANT USAGE ON DATABASE DatabseName TO ROLE MY_DATABRICKS_ROLE;
GRANT USAGE ON SCHEMA DatabseName.SchemaName TO ROLE MY_DATABRICKS_ROLE;
GRANT SELECT ON ALL TABLES IN SCHEMA DatabseName.SchemaName TO ROLE MY_DATABRICKS_ROLE;
GRANT SELECT ON FUTURE TABLES IN SCHEMA DatabseName.SchemaName TO ROLE MY_DATABRICKS_ROLE;
3. In Unity Catalog, create the Snowflake connection, an external location for the ADLS path, and a foreign catalog with the authorized path.
CREATE CONNECTION SnowFlakeConn TYPE snowflake
OPTIONS (
host '<acct>.snowflakecomputing.com',
port '443',
sfWarehouse '<wh>',
user 'UserName',
<key-pair auth options>
);

CREATE EXTERNAL LOCATION snf_iceberg_loc
URL 'abfss://<container>@<storage>.dfs.core.windows.net/'
WITH (STORAGE CREDENTIAL <cred>);

CREATE FOREIGN CATALOG SnowFlakeCatalog
USING CONNECTION SnowFlakeConn
OPTIONS (
database '<snf_db>',
authorized_paths
'abfss://<container>@<storage>.dfs.core.windows.net/'
 );
4. Refresh and query. Databricks reads Iceberg data directly from ADLS using its own compute. Apply RBAC and masking policies in Databricks.
REFRESH FOREIGN CATALOG SnowFlakeCatalog;
SELECT * FROM SnowFlakeCatalog.SchemaName.TableName;
Conclusion
Through the use of interoperability, both Databricks and Snowflake will be able to share data bidirectionally through a single version of the data that is present in ADLS, but with metadata exchange. This will lead to no duplication of data and will always provide access to fresh data. There are several advantages for businesses in terms of cost savings through storage and ETL cost reduction, faster access to data, increased flexibility, and vendor lock-in reduction.
Opinions expressed by DZone contributors are their own.