

Jakarta Batch in Practice: Reliable Chunk-Oriented Processing for Enterprise Workloads
Jakarta Batch gives enterprise apps a standard model for long-running data processing with jobs, steps, readers, processors, writers, checkpoints, and tunable execution.
 CORE
·
Join the DZone community and get the full member experience.
Join For FreeBatch processing remains vital because many business operations aren't suited to interactive requests. Tasks such as recalculating prices, reconciling transactions, migrating records, generating reports, processing invoices, reclassifying customers, or applying rules across millions of records may require considerable time. Handling these as standard requests leads to fragile systems, increased user wait times, frequent timeouts, challenging retries, and possible data inconsistencies.
A batch model handles large workloads predictably, incrementally, and with control over progress and recovery. Rather than processing a massive operation as a single loop, batch processing uses jobs, steps, chunks, checkpoints, filtering, and restartability. This approach separates long-running data tasks from the user experience while delivering a structured execution model. In this article, we will focus on Jakarta Batch and examine its sustained relevance for modern enterprise applications.
Why Batch Processing Still Matters in Enterprise Systems
Modern applications offer various methods for background processing, such as message queues, event-driven architectures, schedulers, reactive pipelines, and distributed stream-processing platforms. While each addresses specific needs, batch processing is most effective when operations have a defined start and end, involve a known or discoverable dataset, and require controlled execution, progress tracking, restartability, or periodic processing.
Batch processing remains essential in enterprise systems. Workloads such as financial reconciliation, billing, payroll, reporting, data migration, regulatory processing, catalog updates, and large-scale reclassification are still prevalent. In these scenarios, the priority is to process large volumes of work safely and predictably, rather than responding to individual events quickly. Batch provides a model specifically designed for these requirements.
How Jakarta Batch Works
Jakarta Batch organizes background processing into jobs and steps. A job defines the overall batch operation, while each step represents a specific stage. In chunk-oriented processing, a step follows a simple pipeline: read, process, write, and repeat until it processes all input. The Jakarta Batch runtime manages this lifecycle so application code can focus on reading, transforming, and persisting data.
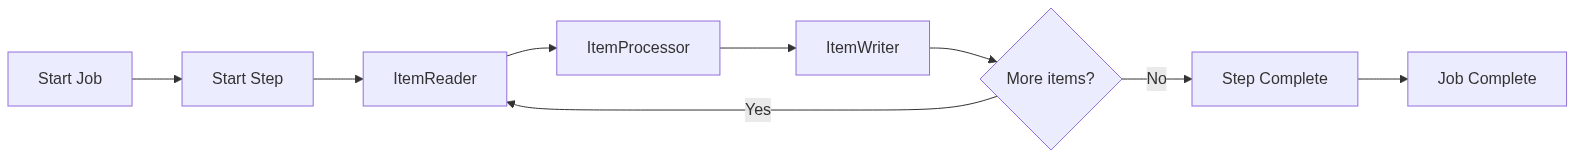
A job is the top-level unit of execution and represents a complete business operation, such as importing records, recalculating customer classifications, processing invoices, or reconciling transactions. Jobs can accept parameters at startup, allowing the same batch definition to run with different inputs or business rules.
A job consists of one or more steps, each representing a distinct phase of the workload. Simple jobs may have a single step, while complex processes can use multiple steps in sequence, such as importing data, validating it, and generating a final report.
- Within a chunk-oriented step, the
ItemReadersupplies data to the runtime one item at a time, from sources such as a database or file. The reader only retrieves the next item and does not need to know how it will be processed or persisted. - The
ItemProcessorreceives each item and applies business rules, such as validation, transformation, classification, enrichment, or filtering. It may return a modified item or null if the item should be excluded from writing. - The
ItemWriterreceives processed items and persists or exports them. Unlike the reader and processor, which handle items individually, the writer typically receives a group of items from the current chunk. This enables more efficient database or bulk operations.
Jakarta Batch adds features around this pipeline to support enterprise workloads. The runtime manages chunk boundaries, transactions, checkpoints, execution status, failures, and restart behavior. Chunk size determines how much work is grouped before a write and checkpoint, making it a key parameter for balancing throughput, memory usage, database cost, and recovery.
The core model is straightforward:
Job → Step → Read → Process → Write → Repeat
Jakarta Batch keeps the business pipeline simple while the runtime manages the execution mechanics needed for reliable, long-running data processing.
The Sample: Customer Segmentation with Jakarta Batch
This example demonstrates the Jakarta Batch model using an e-commerce customer segmentation scenario. Customers are assigned to tiers such as Bronze, Silver, Gold, and Platinum based on configurable spending thresholds. When thresholds change, the application reevaluates the customer base and updates only customers whose classification has changed.
The full application includes MongoDB integration, a Jakarta Faces UI, a preview workflow, validation, and supporting services. The complete source code is available at https://github.com/soujava/mongodb-jakarta-batch. This section focuses on the classes directly involved in Jakarta Batch execution.
Starting the Batch Job
The application initiates the batch process through CustomerSegmentationService. Unlike the reader, processor, and writer, this class is not a batch artifact. Instead, it is an application service that retrieves Jakarta Batch’s JobOperator from BatchRuntime to start and monitor job executions.
@ApplicationScoped
public class CustomerSegmentationService {

    public static final String JOB_NAME = "customer-segmentation";

    private volatile CustomerSegmentationPolicy currentPolicy;

    // initialization and status methods omitted

    public long start(CustomerSegmentationPolicy policy) {
        if (isRunning()) {
            throw new IllegalStateException(
                    "A customer segmentation batch is already running");
        }

        Properties parameters = new Properties();
        parameters.setProperty(
                CustomerSegmentationPolicy.JOB_PARAMETER,
                policy.toJson());

        long executionId =
                BatchRuntime.getJobOperator()
                        .start(JOB_NAME, parameters);

        currentPolicy = policy;
        return executionId;
    }

    public boolean isRunning() {
        // implementation omitted
    }
}
The key API here is JobOperator, which Jakarta Batch provides as the interface for starting, stopping, restarting, and inspecting jobs. In this example, the segmentation policy is serialized into the job parameters to ensure each execution gets the correct business rules.
Reading the Input
The first batch artifact, CustomerItemReader, extends Jakarta Batch’s AbstractItemReader to implement a chunk-oriented reader.
@Named("customerItemReader")
@Dependent
public class CustomerItemReader extends AbstractItemReader {

    @Inject
    private CustomerRepository customerRepository;

    private List<Customer> customers = List.of();
    private int nextIndex;

    @Override
    public void open(Serializable checkpoint) {
        try (Stream<Customer> customerStream =
                     customerRepository.findAll()) {

            customers = customerStream
                    .sorted(Comparator.comparing(Customer::getId))
                    .toList();
        }

        nextIndex =
                checkpoint instanceof Integer index
                        ? index
                        : 0;
    }

    @Override
    public Customer readItem() {
        if (nextIndex >= customers.size()) {
            return null;
        }

        return customers.get(nextIndex++);
    }

    @Override
    public Serializable checkpointInfo() {
        return nextIndex;
    }
}
These methods are part of the Jakarta Batch reader lifecycle defined by AbstractItemReader. open() prepares the reader and accepts a previous checkpoint if available. readItem() provides the next item to the runtime; returning null indicates there is no more input. checkpointInfo() reports the reader’s current position for checkpointing.
For simplicity, this sample loads customers into memory. For larger workloads, the implementation might use pagination or a MongoDB cursor without changing the Jakarta Batch model.
Processing Each Customer
The next artifact implements Jakarta Batch’s ItemProcessor interface.
@Named("customerTierProcessor")
@Dependent
public class CustomerTierProcessor implements ItemProcessor {

    @Inject
    @BatchProperty(
            name = CustomerSegmentationPolicy.JOB_PARAMETER)
    private String thresholdsJson;

    private CustomerSegmentationPolicy policy;

    @PostConstruct
    void initialize() {
        policy =
                CustomerSegmentationPolicy.fromJson(
                        thresholdsJson);
    }

    @Override
    public Customer processItem(Object item) {
        if (!(item instanceof Customer customer)) {
            throw new IllegalArgumentException(
                    "Expected a Customer item");
        }

        CustomerTier calculatedTier =
                policy.tierFor(customer.getTotalSpent());

        if (calculatedTier == customer.getTier()) {
            return null;
        }

        return Customer.builder()
                .id(customer.getId())
                .name(customer.getName())
                .totalSpent(customer.getTotalSpent())
                .tier(calculatedTier)
                .build();
    }
}
Here the Jakarta Batch contract is explicit: ItemProcessor defines processItem(). The runtime calls that method for every item produced by the reader. The processor applies the segmentation rule and either returns the transformed customer or null. Returning null has a specific meaning in Jakarta Batch: the item is filtered and does not continue to the writer.
The @BatchProperty is also part of the Batch integration. It receives the thresholds property defined for this job execution, allowing the processor to reconstruct the CustomerSegmentationPolicy before processing begins.
Writing the Results
The final artifact extends AbstractItemWriter, Jakarta Batch’s base implementation for writing a chunk.
@Named("customerItemWriter")
@Dependent
public class CustomerItemWriter extends AbstractItemWriter {

    @Inject
    private CustomerRepository customerRepository;

    @Override
    public void writeItems(List<Object> items) {
        List<Customer> customers = items.stream()
                .map(this::toCustomer)
                .toList();

        customerRepository.saveAll(customers);
    }

    private Customer toCustomer(Object item) {
        if (item instanceof Customer customer) {
            return customer;
        }

        throw new IllegalArgumentException(
                "Expected a Customer item");
    }
}
writeItems() is defined by the Jakarta Batch writer contract inherited from AbstractItemWriter. Unlike the processor, which receives one item at a time, the writer receives a collection of processed items. In this case, the collection contains only customers whose classification changed, as the processor has already filtered the others.
At this point, the Java components of the pipeline are as follows:
CustomerItemReader extends AbstractItemReader
        ↓
CustomerTierProcessor implements ItemProcessor
        ↓
CustomerItemWriter extends AbstractItemWriter
These types are what connect the application code to the Jakarta Batch runtime.
Connecting the Artifacts With JSL
The Java classes define the behavior, but Jakarta Batch requires explicit mapping of the reader, processor, and writer to each job. This orchestration is described in JSL:
<?xml version="1.0" encoding="UTF-8"?>

<job id="customer-segmentation"
     xmlns="https://jakarta.ee/xml/ns/jakartaee"
     version="2.0">

    <step id="recalculate-customer-tiers">

        <chunk item-count="20">

            <reader ref="customerItemReader"/>

            <processor ref="customerTierProcessor">
                <properties>
                    <property
                        name="thresholds"
                        value="#{jobParameters['thresholds']}"/>
                </properties>
            </processor>

            <writer ref="customerItemWriter"/>

        </chunk>

    </step>
</job>
The ref values correspond directly to the names declared with @Named in the Java classes:
@Named("customerItemReader")
@Named("customerTierProcessor")
@Named("customerItemWriter")
The XML therefore tells the Jakarta Batch runtime: for this step, use this reader, then this processor, and finally this writer. It also maps the thresholds job parameter into the processor property.
The item-count="20" sets the chunk size for this sample. Jakarta Batch coordinates reading and processing, periodically invoking the writer according to the chunk lifecycle and establishing transaction and checkpoint boundaries. The value 20 is for demonstration; real applications should tune chunk size based on processing cost, database behavior, transaction size, throughput, and recovery requirements.
This structure is recommended for the article: present the class declaration first, then describe the lifecycle methods inherited from or required by Jakarta Batch. This approach helps the sample teach the API rather than simply presenting isolated methods.
Conclusion
Jakarta Batch is valuable because it transforms large-scale data processing into a structured execution model, eliminating the need for custom loops and ad hoc background logic. By separating reading, processing, and writing, and introducing runtime concepts such as jobs, steps, checkpoints, restartability, and chunk-oriented execution, it provides enterprise applications with a predictable approach to handling workloads involving thousands or millions of records. This allows implementations to focus on business logic, while the Batch runtime manages repetitive execution concerns, making the model easier to understand, optimize, and scale as workloads increase.
Opinions expressed by DZone contributors are their own.
Comments