

Prompt Caching Doesn't Save Money on Turn One
Cache writes cost 1.25x the input price, and reads cost 0.1x. So a fresh conversation's first turn is more expensive with caching on.
 CORE
·
Join the DZone community and get the full member experience.
Join For FreeI went looking for a clean way to show what prompt caching actually saves an agent, and the first thing I found was a fact that's easy to miss if you only read the "up to 90% savings" headline. Caching a fresh conversation's first turn costs more than not caching it. There's no cache to read from yet, so you pay the input price on the content plus a 25% premium to write to the cache, and get nothing back. The savings arrive starting on turn two, once there's something to read.
Where This Lives in deepagents
Deep Agents ships AnthropicPromptCachingMiddleware from langchain-anthropic in its default middleware stack. It doesn't decide what to cache by guessing. It tags exactly two things on every model call:
# langchain_anthropic/middleware/prompt_caching.py (trimmed)
def _apply_caching(self, request: ModelRequest) -> ModelRequest:
    overrides: dict[str, Any] = {}
    cache_control = self._cache_control  # {"type": "ephemeral", "ttl": self.ttl}

    overrides["model_settings"] = {**request.model_settings, "cache_control": cache_control}

    system_message = _tag_system_message(request.system_message, cache_control)
    if system_message is not request.system_message:
        overrides["system_message"] = system_message

    tools = _tag_tools(request.tools, cache_control)
    if tools is not request.tools:
        overrides["tools"] = tools

    return request.override(**overrides)
The system prompt gets one breakpoint on its last content block, and the tool list gets one breakpoint on its last tool. Tool definitions are sent as one contiguous block; a single trailing breakpoint caches the entire tool set. On top of that, the top-level cache_control on model_settings gets translated by Anthropic's own auto-caching behavior into a breakpoint at the end of whatever's cacheable in the request. This is what lets the cached prefix grow to cover prior conversation turns as an agent session gets longer, not just the fixed system+tools prefix.
That's the whole mechanism. No decision logic, no cost estimation, no adaptive behavior. It tags the stable parts and lets the API's own prefix-match caching do the rest.
The Actual Cost Shape, Measured Live
Here's the part that isn't obvious from "caching saves money": it saves money on a schedule, not uniformly. Prompt caching is a prefix match. Turn 2 can only read from cache what turn 1 wrote, turn 3 reads what's accumulated through turn 2, and so on. That gives every agent conversation the same two-phase cost curve: write-only first turn, then reads that get proportionally cheaper as the stable prefix grows relative to what's new each turn.
To measure this for real rather than project it, I ran the same 8-turn engineering conversation (a realistic back-and-forth about refactoring a blocking-I/O call inside an async FastAPI handler) through claude-opus-5 twice - once with no caching, once with top-level auto-caching (cache_control={"type": "ephemeral"} on every request, the exact mechanism AnthropicPromptCachingMiddleware uses via model_settings["cache_control"]). The system prompt was a real ~1,345-token engineering-assistant prompt, counted with count_tokens before running anything billed:
"""python run_experiment.py (needs ANTHROPIC_API_KEY)"""

import anthropic

MODEL = "claude-opus-5"
INPUT_PRICE = 5.00 / 1_000_000
OUTPUT_PRICE = 25.00 / 1_000_000
CACHE_WRITE_MULT = 1.25  # 5-minute TTL
CACHE_READ_MULT = 0.10

SYSTEM_PROMPT = open("system_prompt.txt").read()  # a real ~1,345-token prompt
TURNS = [...]  # 8 real follow-up questions in one coherent conversation

client = anthropic.Anthropic()

def run(*, use_caching: bool) -> list[dict]:
    messages: list[dict] = []
    turn_records = []
    for user_text in TURNS:
        messages.append({"role": "user", "content": user_text})
        kwargs = {
            "model": MODEL, "max_tokens": 400,
            "system": SYSTEM_PROMPT, "messages": messages,
        }
        if use_caching:
            kwargs["cache_control"] = {"type": "ephemeral"}
        resp = client.messages.create(**kwargs)
        usage = resp.usage
        messages.append({
            "role": "assistant",
            "content": "".join(b.text for b in resp.content if b.type == "text"),
        })
        turn_records.append({
            "input_tokens": usage.input_tokens,
            "output_tokens": usage.output_tokens,
            "cache_creation_input_tokens": getattr(usage, "cache_creation_input_tokens", 0) or 0,
            "cache_read_input_tokens": getattr(usage, "cache_read_input_tokens", 0) or 0,
        })
    return turn_records

def cost_for_turn(r: dict) -> float:
    return (
        r["input_tokens"] * INPUT_PRICE
        + r["cache_creation_input_tokens"] * INPUT_PRICE * CACHE_WRITE_MULT
        + r["cache_read_input_tokens"] * INPUT_PRICE * CACHE_READ_MULT
        + r["output_tokens"] * OUTPUT_PRICE
    )
The real output, 16 live API calls, $0.24 total:
| Turn | No-cache $ | Cached $ | Savings | cache_read/creation (cached run) |
|---|---|---|---|---|
| 1 | 0.0170$ | 0.0187$ | -10.2% | read=0 write=1389 |
| 2 | 0.0173$ | 0.0111$ | 35.7% | read=1389 write=64 |
| 3 | 0.0175$ | 0.0110$ | 37.1% | read=1453 write=40 |
| 4 | 0.0177$ | 0.0110$ | 37.7% | read=1493 write=40 |
| 5 | 0.0179$ | 0.0110$ | 38.4% | read=1533 write=37 |
| 6 | 0.0182$ | 0.0112$ | 38.5% | read=1570 write=61 |
| 7 | 0.0184$ | 0.0111$ | 39.6% | read=1631 write=46 |
| 8 | 0.0185$ | 0.0110$ | 40.5% | read=1677 write=27 |
| Total | 0.1423$ | 0.0961$ | 32.5% |
Turn 1 really is negative: 10.2% more expensive than no caching at all, exactly as the documented economics predict. A 5-minute-TTL cache write needs at least two requests to break even (1.25x write + 0.1x read ≈ 1.35x, against 2x for two uncached requests). After that, savings climb every single turn, because the thing growing is the cached portion of the prompt (the cache_read_input_tokens column climbing from 1,389 to 1,677 across the run), while the thing staying flat is the new portion (the write column). By turn 8, caching is saving 40.5% on that turn alone.
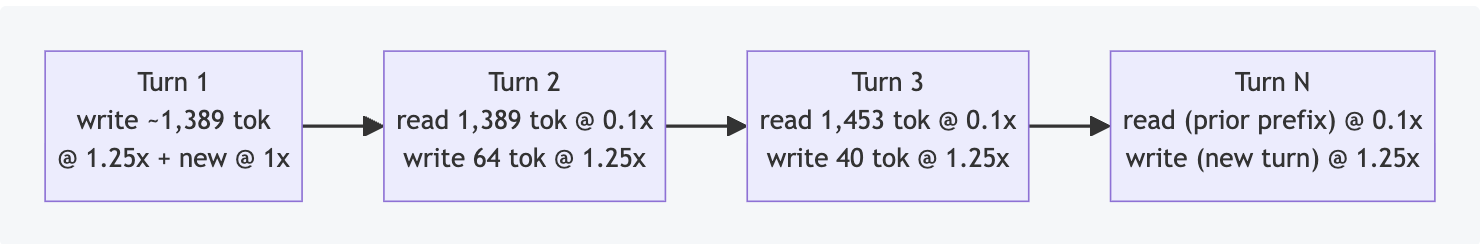
This is also why a one-shot script or a short-lived Lambda almost never benefits from caching. If the conversation ends after one or two turns, you're stuck in the loss zone the math shows on turn 1. Caching pays for itself on sustained, multi-turn agent sessions, which is exactly the shape of a deepagents CLI session or a long-running subagent loop, not a single classification call.
How Much the Stable Prefix Matters
The 32.5% overall figure here is real, but it's specific to this run's cacheable prefix being a fairly modest ~1,345-token system prompt. That number moves with the size of the stable part of the prompt relative to what's genuinely new each turn. Swapping SYSTEM_PROMPT in the script above for a larger, more tool-heavy prefix (closer to what a deepagents agent with 15+ MCP tool schemas actually carries) and rerunning would show the savings percentage climb further. The shape of the curve doesn't change, only how much of the bill it's discounting. If you want to know your own number, this script is a five-minute run against your own agent's actual system prompt.
Two Levers, and They Stack
Caching cuts the price per token of everything that repeats turn over turn. It says nothing about how many tokens you're sending in the first place. That's a second, independent lever: tool-selection filtering, which cuts the token count itself by not sending schemas irrelevant to the current turn. Measured earlier on a 61-tool registry, a lexical-overlap scorer at top_k=10 gets 67% recall at an 84% reduction in tool-schema payload per turn.
These aren't competing techniques — they compose. Caching makes the tokens you do send cheaper turn over turn; tool selection reduces how many tokens are in the first place, in the one part of the prompt (the tool list) caching's own breakpoint sits right in front of. A 6,000-token stable prefix that's 40% tool schemas doesn't stay 6,000 tokens once you're only sending the top-10 relevant tools instead of all 61: it shrinks, and then gets cached at the smaller size. Neither technique substitutes for the other: one is about the price of a token, the other is about whether you send it at all.
Takeaways
The counterintuitive part is the one worth remembering: caching a conversation that only runs one or two turns can cost more than not caching it, because the write premium has nothing to amortize against. It only pays off on sessions that actually run long enough to read back what turn one wrote. Second, if you're trying to actually cut what an agent costs, price-per-token and token-count are separate dials: caching turns one, tool selection turns the other, and a real cost reduction effort turns both.
Opinions expressed by DZone contributors are their own.
Comments