

Rebuilding Elasticsearch Under Load: Unsafe Watermarks and a Sampling Blind Spot
Two common rebuild watermarks can miss committed changes, while a 5,000-document sample may still report a clean Elasticsearch index.
Join the DZone community and get the full member experience.
Join For FreeRebuilding an Elasticsearch index from PostgreSQL sounds simple:
- Create a new index.
- Copy the rows that belong in search.
- Replay anything that changed during the copy.
- Verify the result.
- Move the search alias.
The difficult part is deciding where the bulk copy ends and the replay begins.
A transaction can update a row before the rebuild starts and commit after the copy has taken its database snapshot. With the wrong watermark, that change may appear in neither the copy nor the replay. The rebuild finishes successfully, but the new index is wrong.
I built a controlled recovery drill to measure this problem. The test used synthetic data rather than information from a client or production system.
The setup included:
- 500,000 PostgreSQL rows
- 449,917 rows initially matching the search predicate
- 2,000 updates, 250 deletes, and 120 inserts during each rebuild
- Eight concurrent writer connections
- A two-node Elasticsearch 8.19.3 cluster
I ran the timestamp-based strategy five times. It produced the same 366 measurable inconsistencies in every run.
The corrected transaction-aware strategy was tested in 30 runs across several configurations. All 30 passed the implemented pre-cutover checks.
The most surprising result was not the total number of errors. It was that a field-level comparison of 5,000 documents reported no stale content in any of the five defective runs.
First, Confirm That a Rebuild Is Necessary
Before rebuilding from PostgreSQL, confirm that the existing index cannot be recovered.
Resolve the application alias, identify the physical index behind it, and inspect the affected shards. Elasticsearch’s cluster allocation explain API can show whether an unassigned shard is caused by disk pressure, a missing node, an allocation rule, or the absence of a valid shard copy.
If a usable snapshot exists, restoring it into a separate versioned index may also be faster than rebuilding the full projection.
The rest of this article assumes that allocation repair and snapshot restoration are not available.
Unsafe Watermark 1: updated_at
The first rebuild strategy used a timestamp as the replay boundary:
-- Record the replay boundary.
SELECT clock_timestamp();

-- Copy the current search projection.
SELECT id, title, body, status, version, updated_at
FROM searchable_content
WHERE status = 'PUBLISHED'
ORDER BY id;

-- Replay rows changed after the boundary.
SELECT id, title, body, status, version, updated_at
FROM searchable_content
WHERE status = 'PUBLISHED'
  AND updated_at > :rebuild_started_at
ORDER BY id;
This approach assumes that updated_at represents commit order. In the drill, the value was assigned when the update statement ran, not when the transaction committed.
Consider this sequence:
Session A: UPDATE row 1
           updated_at = 17:23:46.252262
           transaction remains open

Session B: reads the rebuild watermark
           watermark = 17:23:46.465777

Session A: COMMIT
The transaction committed after the watermark, but the row carried a timestamp from before the watermark.
The bulk scan did not include the update because its PostgreSQL snapshot was created while the transaction was still open. The replay did not include it because the row failed this condition:
updated_at > :rebuild_started_atThe change fell between the two phases.
This issue is not limited to clock_timestamp(). A timestamp assigned by an application, database statement, or trigger may still be created before the surrounding transaction commits. If application servers assign the value, differences between their clocks introduce another source of error.
Timestamp replay also has two simpler problems.
First, a deleted row no longer exists in the source table. A query against the current rows cannot tell Elasticsearch that the old document must be removed.
Second, a row may remain in PostgreSQL but stop matching the search predicate. In this experiment, a row could change from PUBLISHED to DRAFT. The replay query selected only published rows, so it did not remove the old Elasticsearch document.
At the end of each timestamp-based run, the defects were:
| Defect class | Count |
|---|---|
| Missing from Elasticsearch | 3 |
| Deleted from PostgreSQL but still indexed | 228 |
| Outside the search predicate but still indexed | 131 |
| Present in both systems but stale | 4 |
| Total | 366 |
PostgreSQL contained 449,863 rows matching the final predicate, while Elasticsearch contained 450,219 documents. The net count difference was 356, which understated the real problem.
Three missing documents offset part of the 359 unexpected documents, and the four stale documents did not change the count at all.
Unsafe Watermark 2: MAX(seq)
A transactional outbox solves part of the problem.
A trigger can write an outbox event in the same transaction as every insert, update, or delete. Deletes now leave tombstones, so the replay process knows which Elasticsearch documents to remove.
A first outbox design might use a BIGSERIAL sequence. Before starting the copy, the rebuild records the largest visible sequence value:
SELECT MAX(seq)
FROM reindex_outbox;
After the copy, it replays everything above that value:
SELECT seq, content_id, op
FROM reindex_outbox
WHERE seq > :starting_seq
ORDER BY seq;
This avoids clock problems, but it still does not provide a commit boundary.
Consider two transactions:
T1: UPDATE row 1
    outbox seq 51 allocated
    transaction remains open

T2: UPDATE row 2
    outbox seq 52 allocated
    COMMIT

Rebuild process:
    SELECT MAX(seq) returns 52

T1:
    COMMIT
When the rebuild reads MAX(seq), T1 is still invisible. T2 has committed, so the largest visible sequence is 52. T1 later commits with sequence 51.
A replay using seq > 52 will never return the T1 event.
PostgreSQL sequences generate distinct values, but they do not represent commit order. The PostgreSQL sequence documentation also explains that a value returned by nextval() is not reclaimed if its transaction later aborts.
Sequence allocation and transaction visibility are separate mechanisms. Replacing the timestamp with a counter did not fix the underlying problem because both values were assigned before transaction visibility was settled.
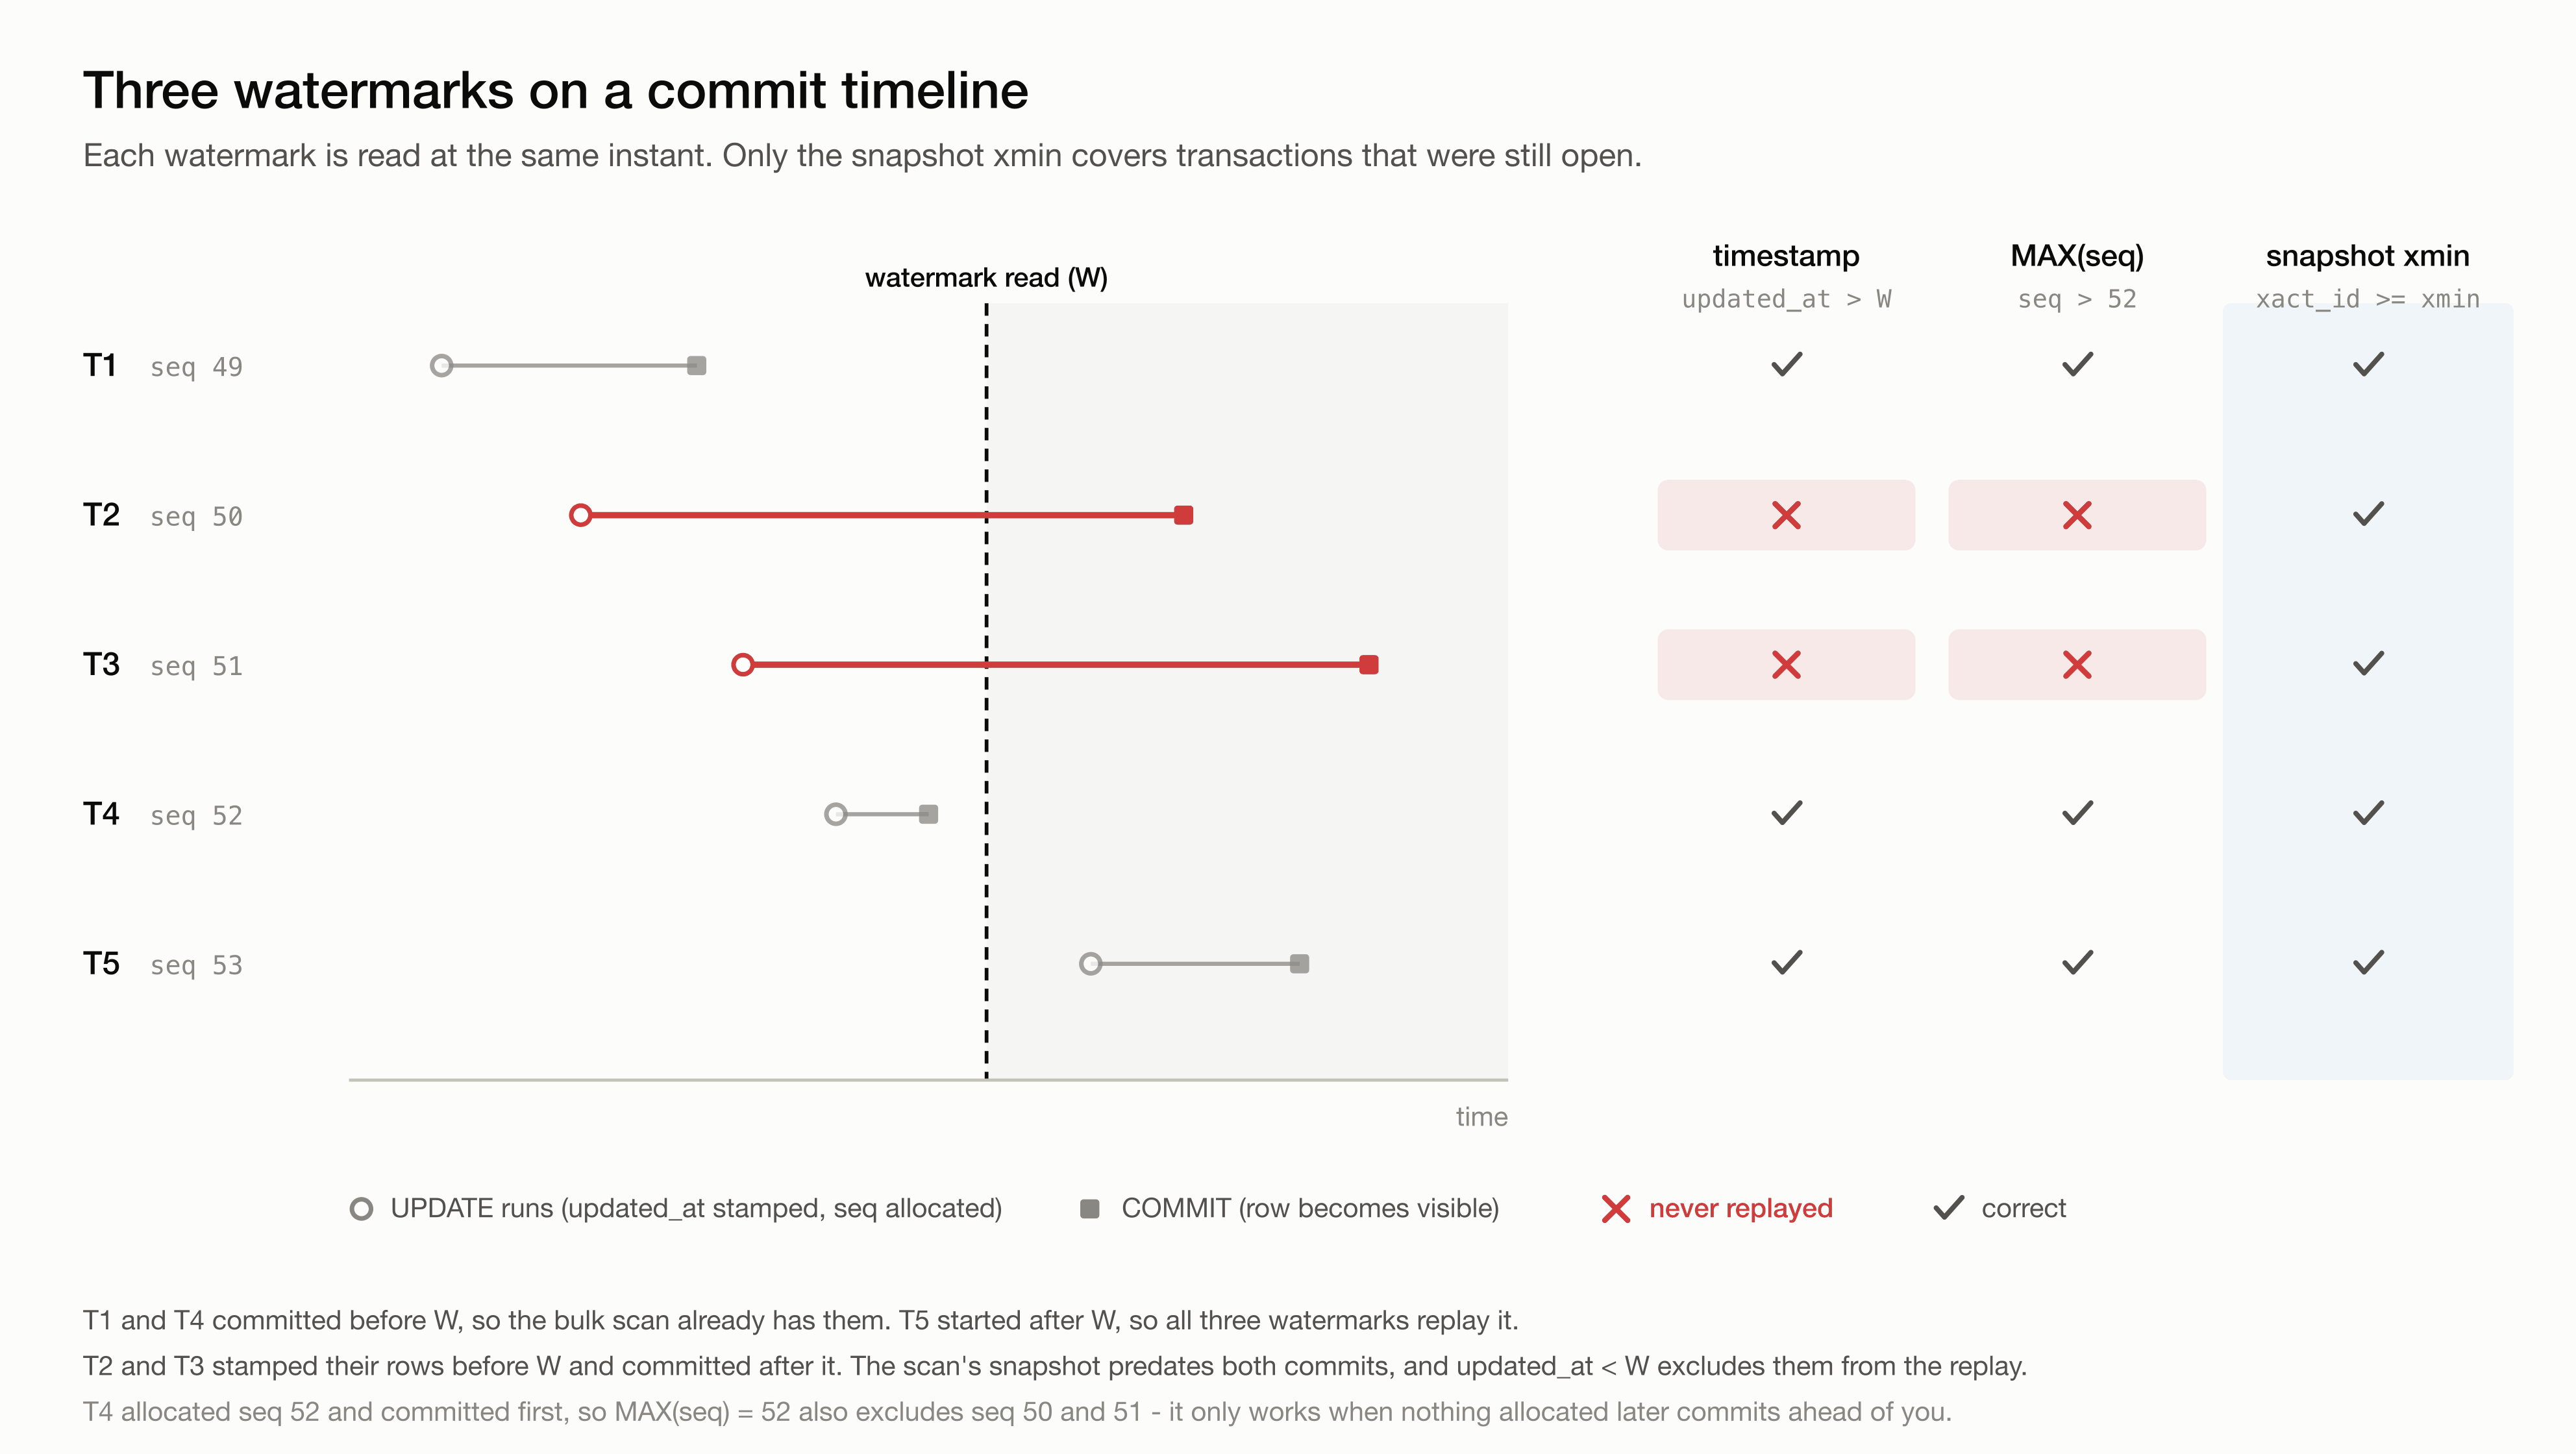
Figure 1. Timestamp and sequence-maximum watermarks can both miss a transaction that starts before the watermark and commits afterward.
A Transaction-Aware Replay Window
The corrected implementation records the PostgreSQL transaction ID in every outbox event:
CREATE TABLE reindex_outbox (
    seq         bigserial PRIMARY KEY,
    content_id  bigint NOT NULL,
    op          text NOT NULL
                CHECK (op IN ('upsert', 'delete')),
    xact_id     bigint NOT NULL
                DEFAULT pg_current_xact_id()::text::bigint,
    captured_at timestamptz NOT NULL
                DEFAULT clock_timestamp()
);
The outbox event is inserted in the same transaction as the source change.
Before beginning the bulk scan, the rebuild records the current PostgreSQL snapshot’s xmin:
SELECT pg_snapshot_xmin(
    pg_current_snapshot()
)::text::bigint;
PostgreSQL defines snapshot xmin as the lowest transaction ID that was still active when the snapshot was taken. This gives the rebuild a conservative lower bound for transactions that may not be represented in the bulk-copy snapshot.
The replay population begins with:
SELECT DISTINCT content_id
FROM reindex_outbox
WHERE xact_id >= :snapshot_xmin;
This may include changes that the bulk scan already copied. That is acceptable because the Elasticsearch operations use stable document IDs and are designed to be idempotent.
The snapshot tells the rebuild where replay should begin. It does not tell the rebuild when replay is complete.
A Final Boundary Is Still Needed
An outbox consumer may catch up while writes continue. It may even report zero lag for a moment. That does not close the recovery window because another transaction can commit immediately afterward.
The drill therefore uses a final quiescent boundary:
- Capture the transaction-aware replay lower bound.
- Bulk-copy the source projection while writes continue.
- Drain visible outbox events.
- Stop accepting new source mutations.
- Allow transactions already in progress to finish.
- Drain the remaining events.
- Verify the new index.
- Move the alias and resume writes.
The synthetic writer had a finite plan and had already completed by the time the final barrier was applied. The experiment therefore measured finalization after the writer became idle. It did not measure the delay that production requests would experience while blocked by an active write barrier.
A system that cannot pause writes needs a durable stream handoff. PostgreSQL logical decoding, for example, can combine an exported snapshot with a persistent replication position.
Do Not Use One Sequence Cursor for the Drain
My first outbox drain repeated the sequence problem in another place. It used:
WHERE seq > :last_applied_seqSuppose sequence 52 becomes visible while the transaction holding sequence 51 remains open. If the consumer advances its cursor to 52, sequence 51 is skipped when it later commits.
The corrected implementation records applied events individually:
SELECT o.seq, o.content_id
FROM reindex_outbox o
LEFT JOIN reindex_progress p
  ON p.rebuild_id = :rebuild_id
 AND p.seq = o.seq
WHERE o.xact_id >= :snapshot_xmin
  AND p.seq IS NULL
ORDER BY o.seq;
This is an applied-event ledger rather than one high-water mark. A late commit cannot appear below a cursor that has already moved past it.
The replay also reads the current PostgreSQL state instead of trusting an old document payload stored in the outbox:
- If the row currently matches the search predicate, it is upserted.
- If the row was deleted, the Elasticsearch document is deleted.
- If the row still exists but no longer matches the predicate, the document is also deleted.
Several events for the same source ID therefore converge on its current state.
An outbox event is marked as applied only after its Elasticsearch operation succeeds. Unresolved operations remain unapplied and cause the cutover to fail.
The Elasticsearch Bulk API also requires item-level checking. A request can return HTTP 200 while individual operations fail and the response contains errors: true. In a separate overload test, 525 rejected document operations appeared inside 22 HTTP-200 responses. Checking only the HTTP status would have reported those requests as successful.
Why a 5,000-Document Sample Reported a Clean Result
I tested three lightweight reconciliation methods against the timestamp-based rebuild:
- Counts divided into six ID ranges
- Checks against the 250 IDs selected for deletion
- A field-level comparison over 5,000 randomly selected source records
The first two checks found problems immediately. All six count ranges differed, and 228 of the 250 deleted IDs were still present in Elasticsearch.
The sampled content comparison found none of the four stale documents in any of the five runs. The full-corpus comparison found all four.
For a population of N comparable documents containing s stale records, and a sample of n documents selected without replacement, the probability of finding at least one stale record is:
P(detect at least one)
    = 1 - C(N - s, n) / C(N, n)
For this experiment:
N = 449,860 documents present in both systems
s = 4 stale documents
n = 5,000 sampled documents
The probability of finding at least one stale document was approximately 4.37%.
To reach a 95% detection probability, the sample would need 237,134 documents, or 52.7% of the comparable corpus. Reaching 99% would require 307,601 documents, or 68.4%.
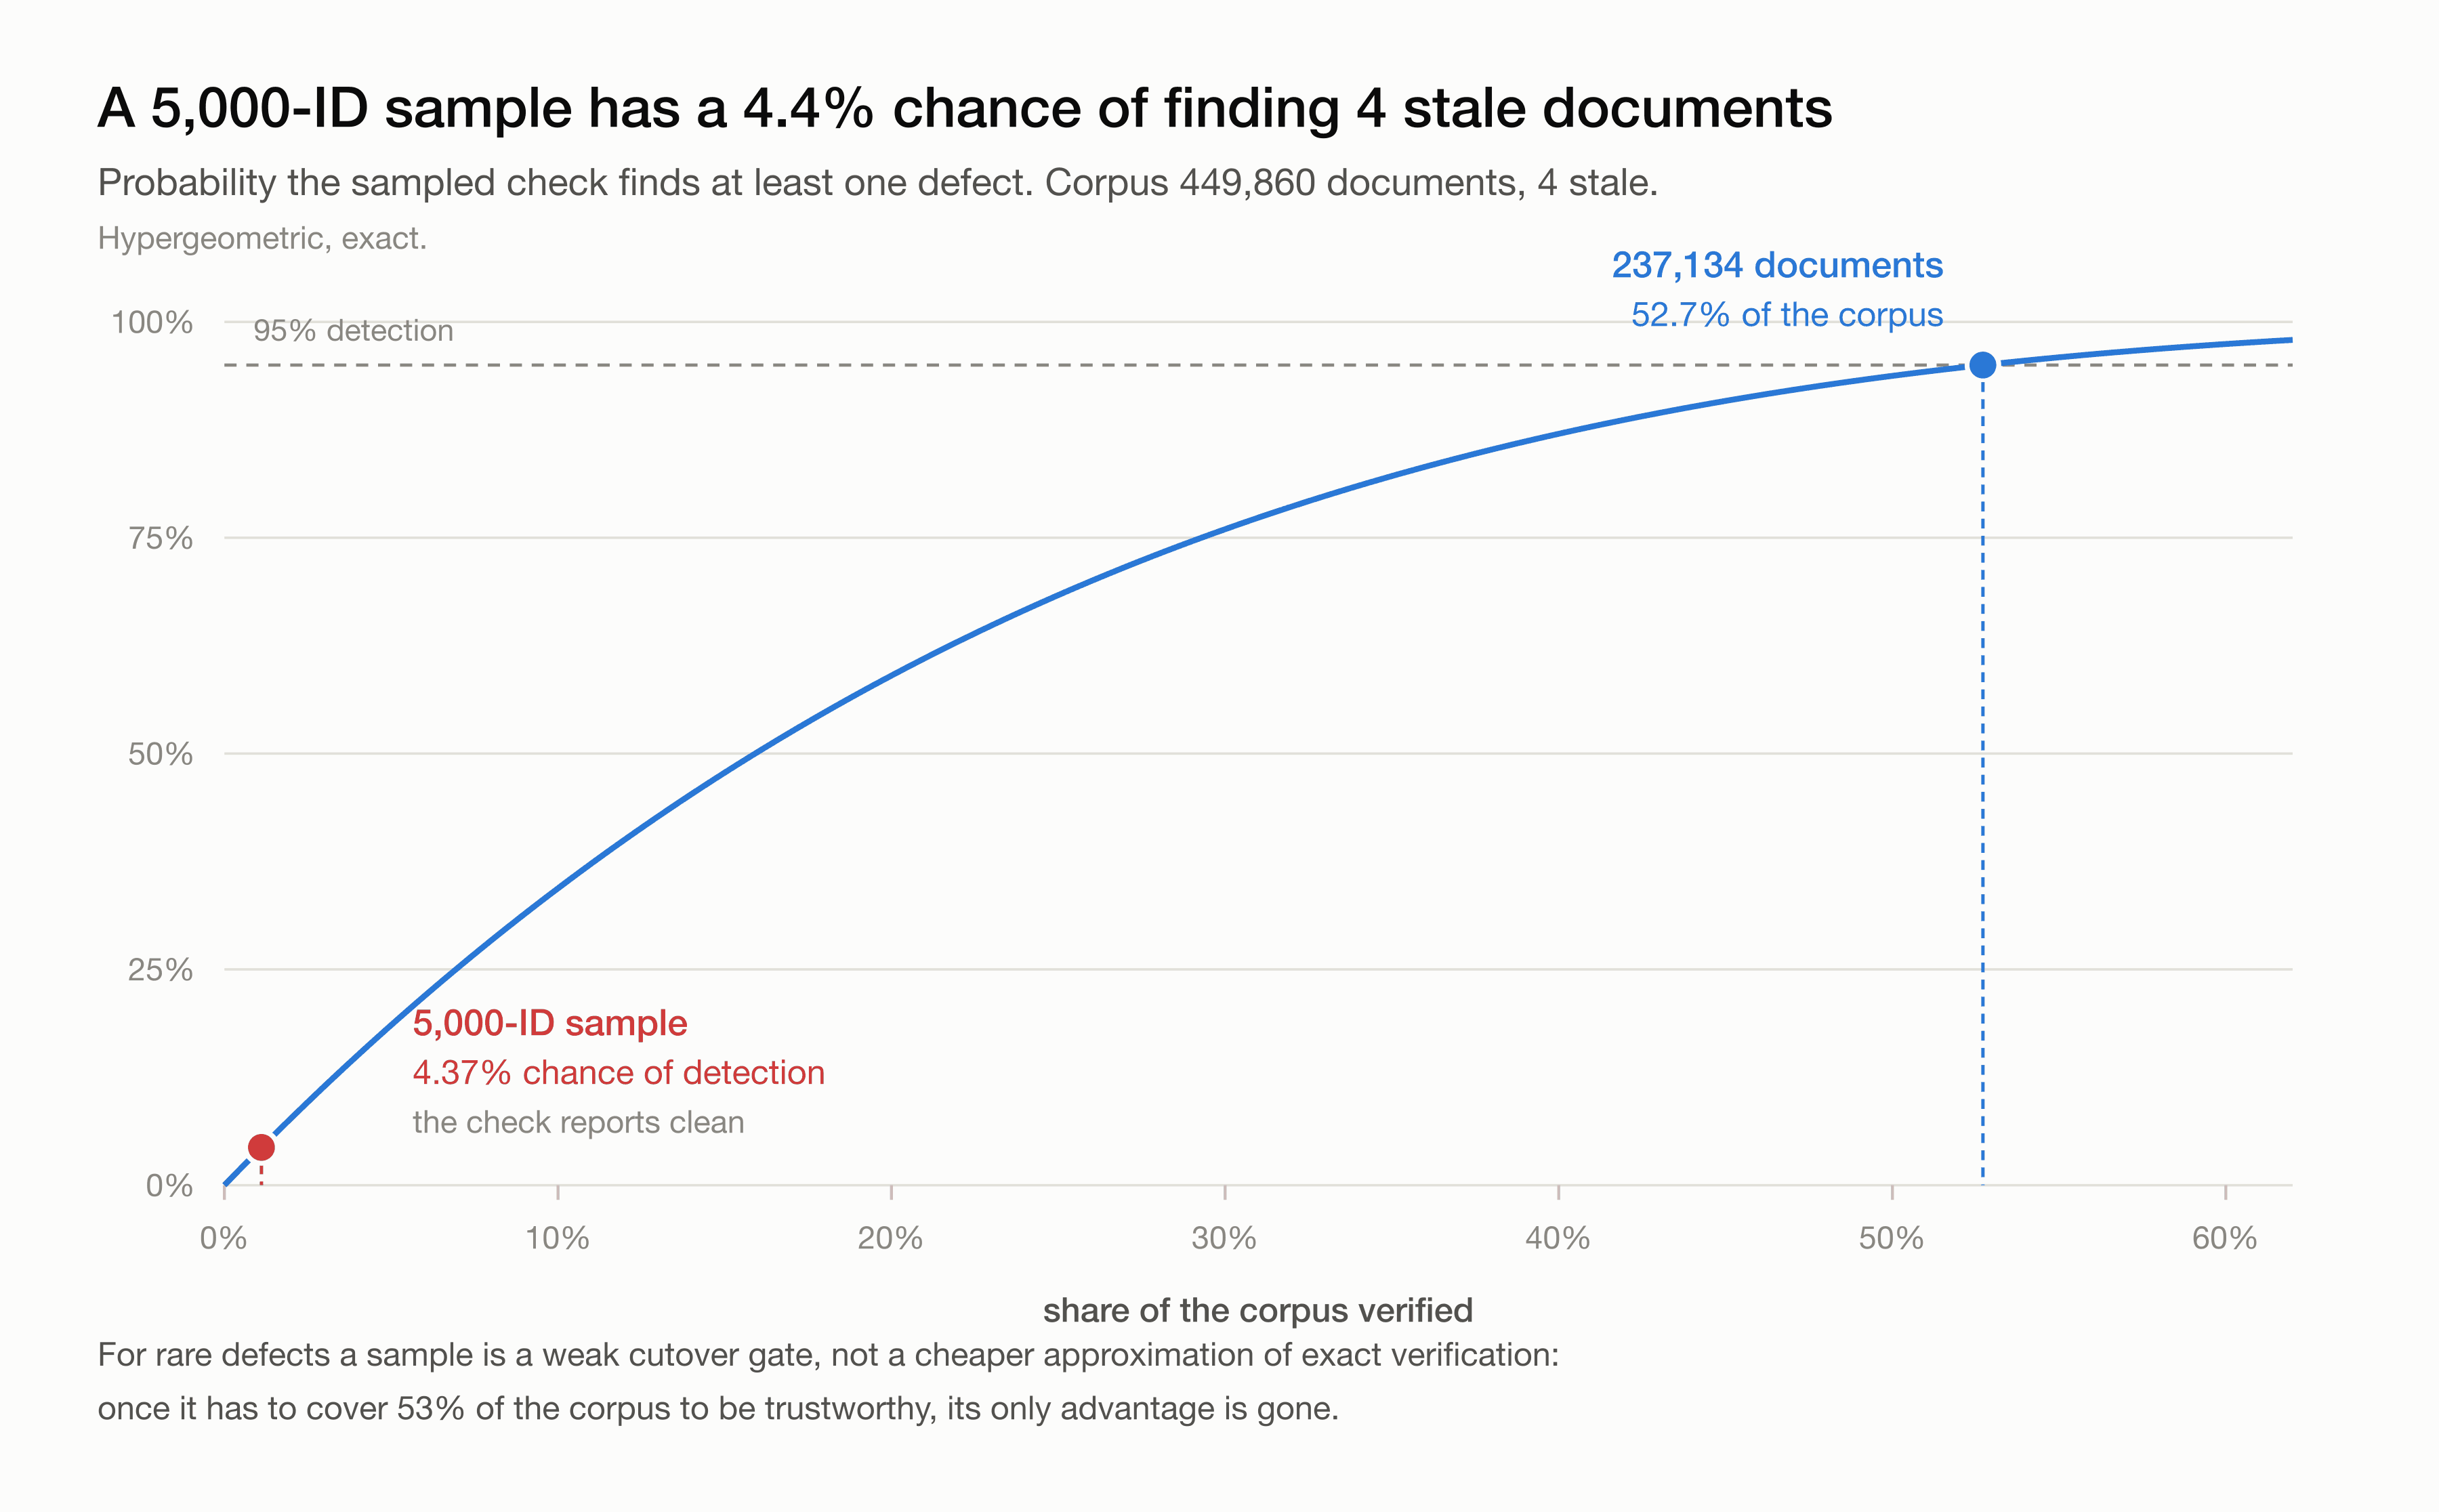
Figure 2. Detection probability as the sample size increases when four of 449,860 comparable documents are stale.
This does not mean sampling is useless.
A 5,000-document sample can quickly reveal a widespread transformation error. Sampling can also be useful as a regular monitoring check between rebuilds.
It is weak as a cutover gate for rare defects. Transaction-boundary races may affect only a few records inside an otherwise reasonable-looking index. That is exactly the situation in which a modest random sample has little statistical power.
What the Full-Corpus Check Compared
The full comparison checked:
- The complete expected set of document IDs
- A digest over
id,title,body,status, andversion
Each field was length-prefixed before hashing so that field boundaries could not be confused. PostgreSQL calculated the source-side digest. On the Elasticsearch side, the verifier read the actual fields from _source and calculated the digest again.
The drill uses MD5 as a compact equality checksum, not as a security mechanism. The digest excludes updated_at, whose representation was not canonicalized in the same way on both sides.
The result was:
| Reconciliation result | Timestamp rebuild | Transaction-aware rebuild |
|---|---|---|
| Missing from Elasticsearch | 3 | 0 |
| Deleted source rows still indexed | 228 | 0 |
| Predicate-excluded rows still indexed | 131 | 0 |
| Stale in 5,000-document sample | 0 | 0 |
| Stale in full-corpus comparison | 4 | 0 |
| Total measured inconsistencies | 366 | 0 |
The digest check verifies the document fields included in this projection. It does not verify mappings, analyzers, synonyms, autocomplete, facets, relevance, or authorization rules. Those require functional search tests before the alias moves.
For a much larger index, the comparison should stream sorted ID-and-digest pairs or compare deterministic partitions instead of loading everything into memory.
A Practical Pre-Cutover Gate
A rebuild should not move the alias until all of these conditions are true:
- The expected and actual document IDs match.
- The full-corpus content digests match.
- No committed outbox event in the recovery window remains unapplied.
- No Elasticsearch operation remains unresolved.
- The target index has the required active shards.
- Representative search canaries pass.
The canaries should test the behavior users depend on, not only whether one document exists. Depending on the application, they may include:
- A known search query
- An autocomplete request
- A filter or facet
- Special-character or multilingual content
- A tenant or authorization boundary
Elasticsearch supports removing the old alias target and adding the new target in one alias update operation. The response should still be checked, and the previous index should be retained until the rollback window has passed.
It is also important to measure through verification. In this experiment, final drain, shard preparation, and full-corpus verification added roughly 6.5 to 13.8 seconds after the main rebuild work. A benchmark that stops at the last bulk request does not measure when the index is actually ready.
Limitations
This was a controlled experiment using synthetic data. The source contained one table, one search predicate, and no joins or enrichment.
The main benchmark used one primary shard. Both Elasticsearch nodes ran inside one Podman virtual machine on an Apple M4 Max laptop. This allowed a replica to be allocated, but it did not represent separate machines, storage devices, network paths, or failure domains.
The workload plan was seeded, so the operations and target IDs repeated across runs. Thread scheduling, timing, and throughput did not.
The writer completed before the final barrier was activated, so the experiment measured quiescent finalization rather than the delay experienced by blocked production writes.
The content digest covered five fields and excluded updated_at. It verified document content, not mappings or search behavior.
Finally, snapshot xmin is a conservative recovery boundary, not a replacement for a mature change data capture system. Long-running transactions can widen the replay range. Outbox events must be retained for the full rebuild window, and every relevant source mutation path must participate in the same transactional capture process.
Conclusion
The timestamp watermark failed because the row timestamp was assigned before its transaction committed. MAX(seq) failed for the same reason: sequence allocation did not represent commit order.
The reconciliation test exposed a separate weakness. Checking 5,000 documents sounded substantial, but it provided only a 4.37% chance of finding the four stale records created by this workload.
A reliable rebuild needs two guarantees:
- A replay window based on transaction visibility rather than statement timing
- A complete pre-cutover comparison capable of finding rare inconsistencies
Without both, the rebuild can complete, the document count can look reasonable, and the new index can still disagree with PostgreSQL.
Companion Materials
The synthetic workload, implementation, figures, and per-run results are available in the dzone-recovery-drill-v1.1 companion repository.
Opinions expressed by DZone contributors are their own.
Comments