

Building Scalable and Resilient Data Pipelines With Apache Airflow
Learn to build scalable, fault-tolerant, and observable data pipelines with Apache Airflow, focusing on real-time insights and custom reporting for enterprise SaaS.
I have seen articles discussing Apache Airflow and its many capabilities. It's crucial to understand production-quality data pipelines meant to "handle" terabytes of daily data generated by the enterprise's software-as-a-service (SaaS) applications. The article takes you beyond the basic introductory stuff and on to more advanced techniques and best practices for developing scalable, fault-tolerant, and observable Airflow workflows.
Administration for an enterprise in a modern SaaS context is very challenging. It comes with a myriad of challenges in terms of monitoring, administration, and understanding the usage of applications across the organization. It involves the management of increasing amounts of unstructured data with a high tendency for real-time visibility under user activity, resource utilization, and compliance requirements. From this data, organizations need clear insights into usage within their applications to enable them to manage their human resources efficiently and optimally while being effective and compliant. Therefore, they need a powerful Admin Insights pipeline capable of:
- Scaling out over many organizations and user bases;
- Processing a vast amount of data in either real-time or near real-time; and
- Producing precise and personalized reports based on administrative needs.
To address these considerations, let's tackle a real-world scenario: building an Admin Insights pipeline for a typical SaaS application. Relatively in more abstract terms, at this point, we are going to be introducing Apache Airflow as the backbone of this reporting system, orchestrating large-scale ingestion, transformation, and automation of the data structures required.
Designing a Scalable Admin Insights Pipeline
Data flows from the SaaS Application to the Data Collection and Integration Engine (Segment) and then to the Data Warehouse (AWS Redshift). Report queries are run via Data Orchestration (Apache Airflow) on a periodic basis to dump pre-computed data into Data Lake (S3 buckets), which are subsequently accessed by API using AWS Athena.
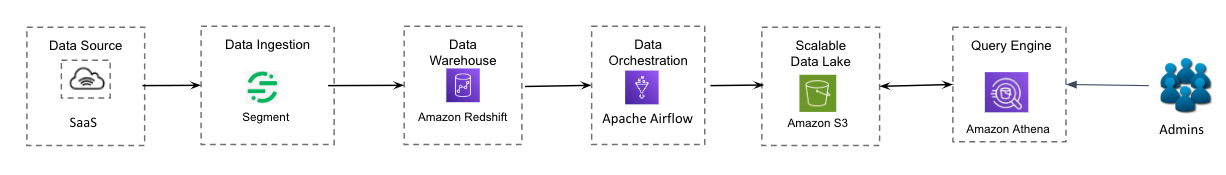
Robust building blocks comprise the modern data pipeline:
- SaaS application: It is the primary data-generating entity producing logs and events into application sessions and user activities.
- Data collection and integration: It is the very first stage in the data processing pipeline, usually requiring some analysis, and most often, relies on very popular tools like Segment.
- Data warehouse: After processing, the data gets stored in a data warehouse(Amazon Redshift), ready to perform structured querying and reporting.
- Data orchestration: This orchestration takes place through Apache Airflow, which schedules the respective tasks and manages them.
- Data lake: A data lake (such as Amazon S3) will be a scalable and cost-effective solution for storing massive amounts of data.
- Query engine: Querying and obtaining insights is made possible using tools such as AWS Athena.
- API: This finalizes the entire process by providing insights to the administrators through internal APIs.
Advanced Airflow Techniques for Admin Insights Pipelines
To boost scalability, automation, and security, the Admin Insights workflow uses these advanced Airflow methods:
1. Dynamic DAG Generation: Custom Reports Per Enterprise Admin
Enterprise Admins at different companies need different reports — some admins care most about keeping things secure, while others want to know how much people are using their product. A configuration database keeps track of what kind of reports each company wants. An Airflow job checks this database and uses Jinja templates to make DAGs that fit what each customer needs. This means every company gets reports made just for them without having to make separate DAGs by hand.
For example, when an enterprise admin asks for a report once a week, instead of every day, Airflow changes the schedule automatically without anyone having to do it.
2. Custom Operators: Real-Time API Interactions
Admin Insights depends on the platform API data to monitor:
- Active users in each organization
- Features used most often
- Trends in license use
Rather than using generic operators, a custom Airflow operator works with the platform's API to get and handle admin-specific data. In this case, a FetchActivityDataOperator grabs user activity logs, changing them into an organized dataset for reports.
class FetchActivityDataOperator(BaseOperator):

    def execute(self, context):

        response = requests.get("https://api.platform.com/admin_activity", headers={"Authorization": "Bearer token"})

        data = response.json()

        process_data(data)  # Custom function to clean and store data
3. Task Groups and SubDAGs: Modular Processing
Enterprise reporting involves multiple layers — organization-wide, team-specific, and user-level insights. For keeping workflows modular, the pipeline uses Task Groups and SubDAGs rather than a monolithic DAG. By utilizing SubDAGs, we can have one SubDAG handle license utilization trends, while another focuses on user engagement metrics, making it easier to troubleshoot and scale.
with TaskGroup("license_utilization") as license_tasks:

    fetch_data = FetchActivityDataOperator(task_id="fetch_license_data")

    transform_data = BashOperator(task_id="transform_license_data", bash_command="dbt run --model license_trends")
4. Data Quality Checks: Ensuring Accuracy for Admin Reports
SQL-based validations incur before publishing any reports.
- Infrastructure- activity not duplicated
- Aligns between reports and admins' time zones.
- All active users are fully accounted for.
All of the foregoing are processed and verified by an SqlSensor while a BranchPythonOperator will flag inconsistencies before such reports reach enterprise admins. We can easily build a pipeline that raises an alarm instead of inaccurate insights if empty fields exist in the report for an admin (e.g., missing active users).
validate_data = SqlSensor(

    task_id="validate_admin_report",

    conn_id="database_conn",

    sql="SELECT COUNT(*) FROM reports WHERE report_status = 'Incomplete'"
Conclusion
Understanding both the technical and operational requirements of enterprise applications is crucial to building scalable and resilient data pipelines with Apache Airflow. The example of the Admin Insights pipeline serves to demonstrate how Airflow's ability for dynamic orchestration, modular task design, and custom operators can accommodate the specific needs for such applications in large organizations. By automating data ingestion, transformation, and reporting, it empowers administrators to get a truly real-time view into the user activity.
Opinions expressed by DZone contributors are their own.