

Remember Me, Safely: Durable and Governed Memory for Enterprise AI Agents
Agent memory is durable state, not a model feature: isolate threads by principal, checkpoint at boundaries, redact before writes, and resume idempotently.
 ·
Join the DZone community and get the full member experience.
Join For Free"Give the agent memory" sounds like a feature request. In production systems, it is an architecture decision about durable state.
The phrase agent memory is often used to describe several different things:
- Conversation history
- Workflow state
- Checkpoints
- User preferences
- Long-running investigation context
- Retrieved documents
- Tool results
Combining all of them into one persistent conversation object is convenient during prototyping. It is risky in enterprise environments.
Different forms of state have different durability requirements, access rules, and retention periods. A checkpoint required to resume an interrupted workflow is not the same thing as a user preference that may be useful six months later.
The first step toward safe agent memory is therefore separating these concepts.
Layer One: Transient Conversation Context
The shortest-lived form of memory is the context needed for the current inference request. For example:
messages = [
    system_message,
    recent_user_message,
    relevant_tool_result
]
This context helps the model reason about the immediate task. It does not necessarily need permanent storage.
If the content contains large tool outputs, sensitive information, or temporary debugging data, persisting everything by default creates unnecessary exposure. Transient context should be aggressively scoped.
Layer Two: Durable Run State
A multi-step agent has execution state separate from conversation history. Consider:
state = {
    "task": "analyze deployment failure",
    "current_step": "awaiting_approval",
    "candidate_fix": {...},
    "attempts": 2
}
If the process crashes, that state determines whether the workflow can resume. Without persistence, the entire run may restart from the beginning. That can be inconvenient for analysis and dangerous for workflows with side effects.
Suppose the agent has already performed steps one through five and is waiting for approval before step six. A restart should not execute steps one through five again. The correct design is checkpointed execution.
Failure mode: restart replays completed work
If a workflow restarts from the beginning instead of from a durable boundary, already-completed tool calls can be repeated. The result may be duplicate tickets, duplicate notifications, repeated writes, or approvals applied twice.
Checkpoint Before Important Boundaries
A checkpointer stores graph state after meaningful transitions. Conceptually:
checkpoint.save(
    principal_id=current_user.id,
    thread_id=thread_id,
    state=workflow_state,
    node="human_approval"
)
If the process restarts:
state = checkpoint.load(thread_id)
graph.resume(state)
The agent returns to the same logical boundary. This is especially useful for human approval. A workflow may pause overnight while an engineer reviews a proposed operation. The process that originally created the request does not need to remain alive. The durable checkpoint becomes the source of truth.
Architecture at a Glance
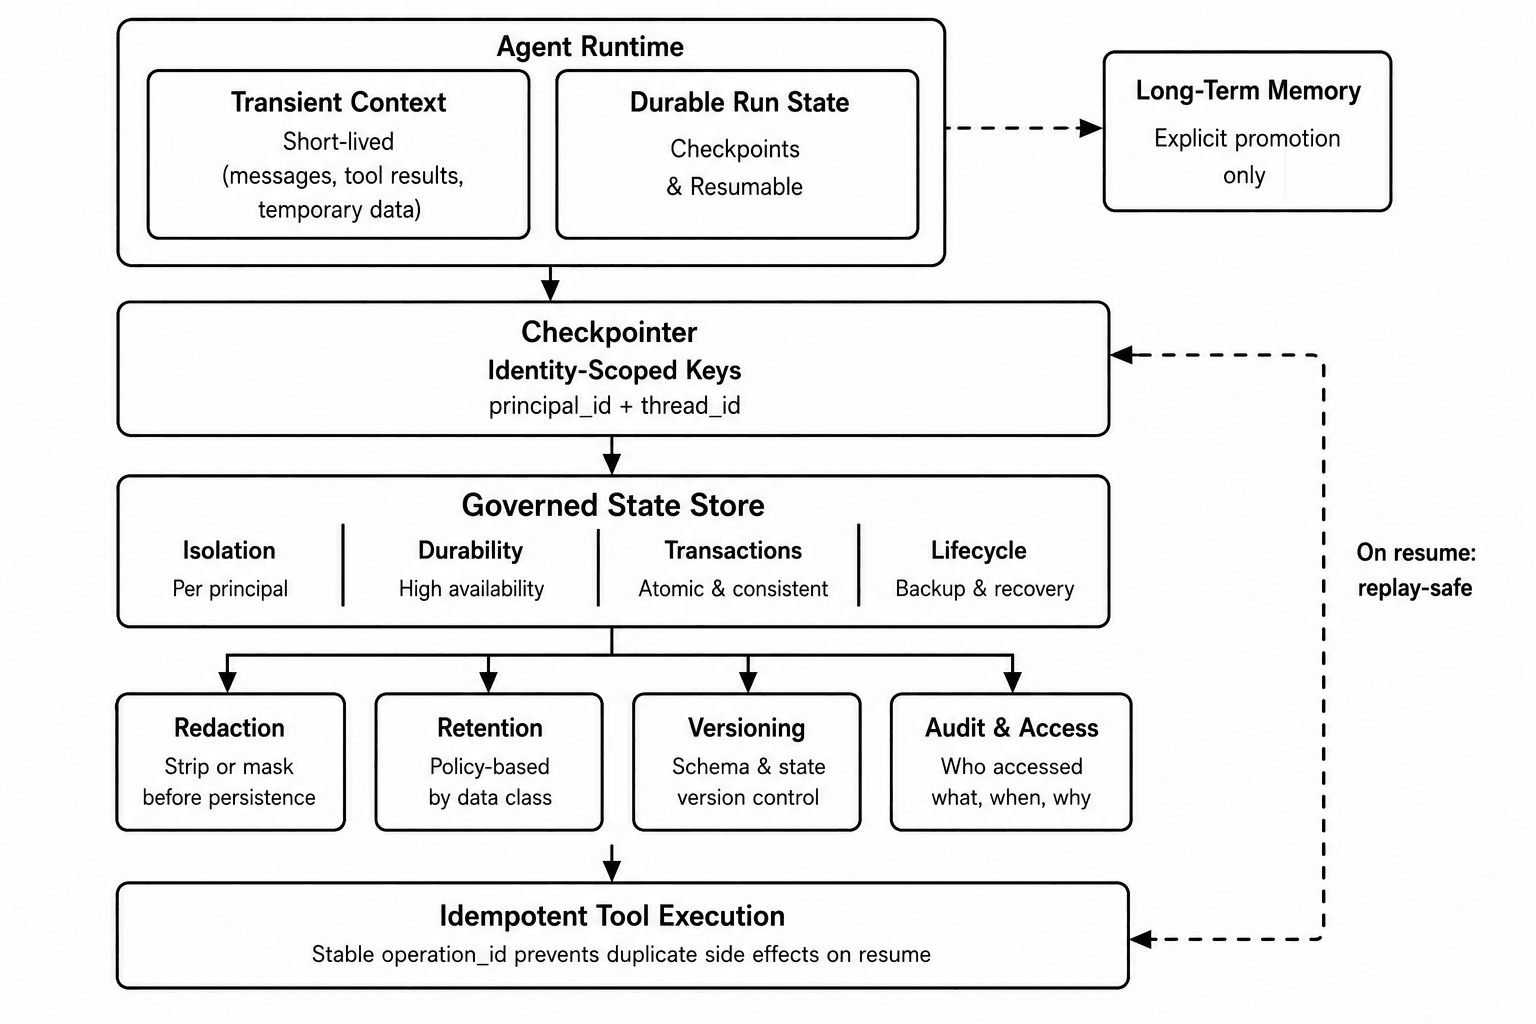
A useful way to model the system is to keep inference context, resumable execution state, and long-term memory as separate concerns around a governed state layer.
Development and Production Need Different Backends
During local development, a lightweight store is often enough. For example:
checkpointer = LocalCheckpointStore(
    path="./agent_state.db"
)
This makes agent development easy because engineers can restart processes and inspect state without deploying distributed infrastructure.
Production requirements are different. Agent runs may execute on multiple instances. Containers may restart. Users may reconnect through another server. Workflows may remain paused for hours or days. A production checkpointer therefore needs distributed durability.
checkpointer = DistributedCheckpointStore(
    namespace="agent-runs"
)
The application should depend on a storage interface rather than backend-specific behavior:
class CheckpointStore:
    def save(self, principal_id, thread_id, state):
        ...

    def load(self, principal_id, thread_id):
        ...

    def delete(self, principal_id, thread_id):
        ...
The same agent runtime can then use a local implementation during development and a distributed transactional datastore in production. For example, a LangGraph checkpointer can use SQLite locally and PostgreSQL in production while preserving the same identity-scoped persistence contract.
A Thread Is a Security Boundary: Not a Bearer Capability
Long-running agent workflows often use a thread identifier. That identifier must not become the only access control. A request such as:
GET /threads/48291cannot mean “return this thread to whoever knows the ID.” The lookup should be scoped to identity:
checkpoint.load(
    user_id=current_user.id,
    thread_id=request.thread_id
)
Storage keys can make the boundary explicit:
/principal/{principal_id}/thread/{thread_id}Authorization must still be enforced independently, but physical key separation reduces accidental cross-user access. For enterprise agents, per-user or per-principal isolation is fundamental. “Resume yesterday’s investigation” should mean resume that principal’s authorized investigation, not retrieve a globally accessible conversation object.
Failure mode: thread ID becomes a capability
If knowing a thread identifier is enough to load its state, the identifier behaves like a bearer token. Treat thread IDs as locators, not authorization. Enforce identity and policy checks on every read and write.
Redact Before Persistence
If sensitive information should not be stored, removing it later is weaker than never storing it. Redaction should happen before writing state.
safe_state = redact_sensitive_fields(
    workflow_state
)

checkpoint.save(
    thread_id=thread_id,
    state=safe_state
)
The redaction layer may target:
- Credentials
- Authentication tokens
- Personally identifiable information
- Private keys
- Sensitive tool responses
- Restricted document content
A useful design keeps references instead of raw values when possible. Instead of:
{
  "api_token": "secret-value"
}
persist:
{
  "credential_reference": "credential://service-x"
}
On resume, the runtime can reacquire the authorized credential. This avoids turning the memory store into a shadow secret-management system.
Do Not Persist the Entire Prompt by Habit
Debugging frameworks frequently store every prompt, completion, and tool result. That is convenient until prompts contain sensitive information. Production memory should distinguish observability from durable agent state.
For example, the checkpoint might contain:
{
  "task_type": "incident_analysis",
  "current_node": "collect_logs",
  "artifact_ids": [
    "log-ref-782"
  ],
  "decision_status": "pending"
}
It may not need to contain the complete raw logs. The actual artifact can remain in its governed source system, where existing retention and access policies apply. Memory should store enough information to resume the workflow, not automatically duplicate every byte the workflow encountered.
Retention Is Part of the Data Model
A memory record without a retention policy is an indefinite record. That is rarely the right default. Different memory types need different lifetimes:
- Temporary inference state: minutes
- Failed-run diagnostics: days
- Approval checkpoints: until completion plus audit window
- Long-term user preferences: policy dependent
- Audit decisions: regulated retention schedule
Retention metadata should travel with the record:
{
  "thread_id": "thread-55",
  "memory_class": "workflow_checkpoint",
  "created_at": "2026-08-10T18:00:00Z",
  "expires_at": "2026-09-10T18:00:00Z"
}
A background lifecycle process can enforce expiration. The agent itself should not decide how long regulated records remain available.
Memory Needs Versioning
Long-running workflows introduce another problem: application code changes while old checkpoints still exist. A state written by version 3 of an agent may be resumed by version 5. Without state versioning, deserialization can fail or, worse, succeed with changed semantics.
Persist a schema version:
{
  "state_version": 3,
  "thread_id": "thread-55",
  "node": "approval",
  "payload": {}
}
The runtime can then migrate older states explicitly:
state = store.load(thread_id)

if state.version < CURRENT_VERSION:
    state = migrate(state)
This is the same discipline used in database schema evolution. Agent memory is application data and should be engineered accordingly.
Resumption Must Not Duplicate Side Effects
Checkpointing becomes especially important around tool execution.
Suppose a workflow:
- Creates a ticket
- Saves state
- Crashes
If the save occurred after ticket creation but failed before recording success, the resumed workflow may create the ticket again.
State transitions and side effects need idempotency.
A tool call can include a stable operation key:
tool.execute(
    operation_id="thread-55-step-8",
    payload=request
)
If the same step is retried:
operation_id already completed
return previous result
This makes resumption safe.
Durable memory without idempotent side effects can actually make failure recovery more dangerous because the system confidently resumes into duplicate operations.
Audit Memory Access
Memory reads should be observable. For sensitive workflows, the system should record:
- Actor
- Thread
- Operation
- Timestamp
- Purpose
- Policy decision
A user should not be able to silently inspect another user’s stored agent state. An administrator may have legitimate access for incident response, but that access should be auditable. Memory governance is not limited to protecting writes. Reads can expose every question, document, and decision associated with an agent run.
Separate Long-Term Memory From Workflow Checkpoints
Long-term memory deserves an especially strict boundary. A checkpoint answers:
Where was this workflow when it stopped?
Long-term memory answers:
What information should this agent remember in future interactions?
Those are very different questions. Do not promote checkpoint data into long-term memory automatically. A user may want an investigation to resume tomorrow without wanting every detail of that investigation retained as a permanent preference or profile.
Long-term memory should require explicit policies about what qualifies, who owns it, how it is updated, and when it expires.
Memory Is Infrastructure, Not Model Context
Reliable enterprise agents need to remember enough to continue useful work. That requirement should not turn every interaction into an indefinitely retained transcript.
The architecture should separate transient context, durable run state, checkpoints, and long-term memory. It should isolate threads by principal, redact sensitive values before storage, version persistent schemas, enforce retention policies, audit memory access, and make resumed side effects idempotent.
Once an agent can say “I remember where we stopped,” the storage behind that sentence becomes part of the enterprise data architecture. That means it deserves the same rigor as any other stateful production system.
Durable memory makes agents more useful. Governed memory makes them safe enough to resume.
Opinions expressed by DZone contributors are their own.
Comments