

Understanding Vector Databases: Concepts, Similarity Search, and Trade-offs for Enterprise Applications
Explore vector databases, similarity search, and how Eclipse JNoSQL brings vector persistence to enterprise Java applications.
 CORE
·
For decades, enterprise applications have used databases to store, retrieve, and process information through structured queries, indexes, and defined relationships. Relational and NoSQL databases have supported a wide range of use cases, from financial transactions to distributed applications. However, artificial intelligence (AI) presents a new challenge: how can applications search for meaning instead of exact values?
Vector databases offer a new approach to data retrieval by enabling applications to use semantic similarity rather than relying only on traditional matching. This unlocks new possibilities for recommendation engines, intelligent search, and AI-powered applications. For Java developers and software architects, understanding vector databases is increasingly important — not to replace existing solutions, but to identify when an alternative data model can address challenges that traditional approaches cannot.
Why Vector Databases Matter
Traditional databases are effective when applications search for exact values. For example, an application storing animal information might return records containing the word “pet” if queried directly. However, it may not return records about dogs or cats, even though they are closely related to the concept of a pet.
Semantic search changes this approach. Instead of comparing words directly, an AI embedding model represents their meanings as numerical vectors. Concepts like “pet” and “dog” are sit close together in a multidimensional space, enabling applications to retrieve relevant information even when search terms don't match exactly.
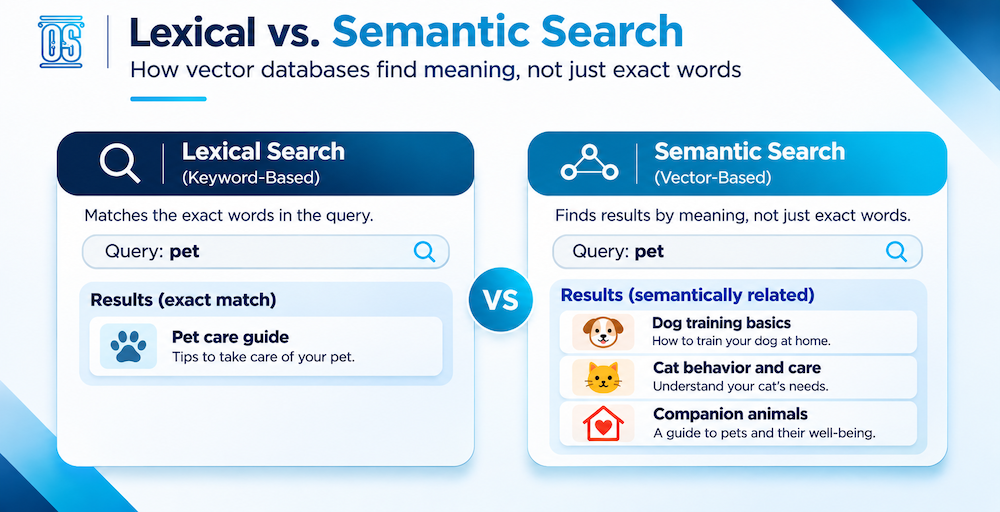
This distinction is especially important in enterprise systems. For example, a customer support application could find relevant solutions without requiring customers to use exact documentation terms, or a recommendation engine could recognize similarities beyond predefined categories. Previously, these capabilities required extra application logic, manual relationships, or specialized search infrastructure.
As large language models (LLMs) and retrieval-augmented generation (RAG) become more common, vector search is now a key component of many AI architectures. However, vector databases do not automatically improve search accuracy or replace relational databases. Their effectiveness depends on the embedding model, similarity measures, indexing strategies, and data characteristics.
For enterprise Java architects, the key question is not just how to persist information, but how to represent and retrieve it based on meaning. To inform these architectural decisions, we first need to examine how vector databases represent information and the types of vectors they support.
Understanding Vector Data: Structure and Types
Unlike traditional records that use fields and values, vector database records use numerical representations to enable similarity searches. Each record, or point, includes an identifier, a vector, and a payload.
The following simplified JSON example represents a document about dogs:
{
  "id": 101,
  "vector": [0.12, -0.35, 0.87, 0.24],
  "payload": {
    "title": "Dog Care Guide",
    "category": "animals",
    "description": "A guide to caring for dogs"
  }
}
Each component serves a specific purpose:
- ID: Uniquely identifies the record for retrieval, update, or deletion.
- Payload: Contains the original information or metadata and supports filtering, such as searching by category.
- Vector: Encodes information as numerical values, enabling the database to calculate similarity between records.
Developers typically do not define vector values manually. Instead, a machine learning model, known as an embedding model, converts text, images, or other data into numerical representations. For example, a model may generate similar vectors for “dog” and “pet” because it has learned their relationship.
The individual numbers are not meaningful on their own. Their significance comes from their position in multidimensional space and their relationship to other vectors from the same model. The four-dimensional vector above is simplified; production models often generate vectors with hundreds or thousands of dimensions.
This creates an architectural consideration: generating embeddings and storing them are separate tasks. A Java application might generate embeddings using an external AI service or a local model, then store them in a vector database. Some databases also provide integrated embedding generation.
Three Types of Vector Representations
While vectors share a mathematical foundation, their representations vary by application. The three main types are dense, sparse, and multi-vectors.
Dense vectors represent information using a fixed-length sequence of numerical values. They are widely used in semantic search, recommendation systems, and RAG applications because embedding models can encode complex relationships into compact numerical representations.
{
  "vector": [0.12, -0.35, 0.87, 0.24]
}
Sparse vectors represent information where most dimensions are zero. They store only the positions and values of nonzero elements, making them useful for keyword-based retrieval and specialized search models.
{
  "vector": {
    "indices": [2, 15, 98],
    "values": [0.8, 0.4, 0.9]
  }
}
Multi-vectors link multiple vectors to a single record. Some models generate separate embeddings for individual tokens or components, enabling more detailed similarity comparisons but increasing storage and computation costs.
{
  "vector": [
    [0.12, -0.35, 0.87],
    [0.24, 0.51, -0.18],
    [0.63, -0.21, 0.42]
  ]
}
These JSON structures are examples; actual representations depend on the database API and vector configuration.
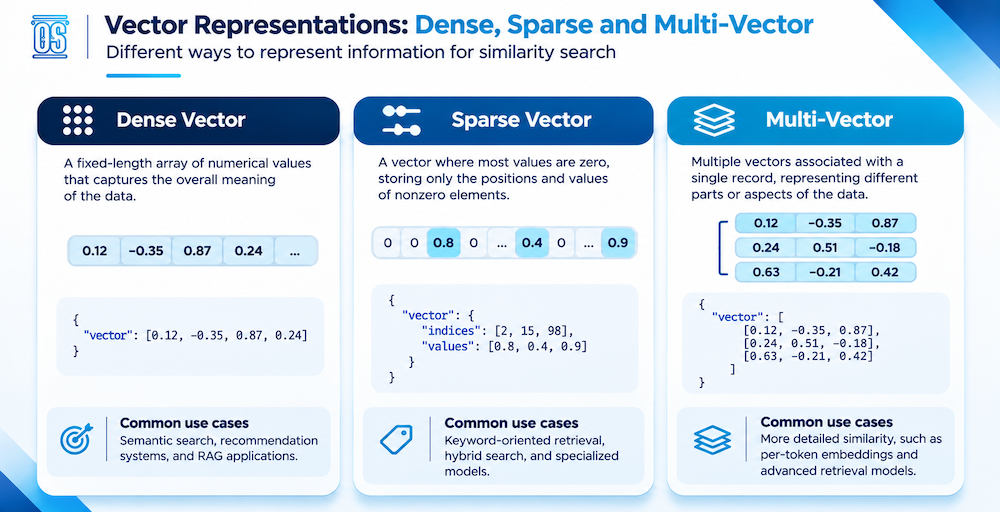
Choosing between these representations involves trade-offs in search quality, memory consumption, indexing, and computational cost. No single representation is universally superior; the right choice depends on the problem, the embedding model, and the database's capabilities.
However, representing information as vectors is only part of the solution. How does a database determine whether two vectors are similar? This is where similarity metrics such as cosine similarity, Euclidean distance, and the dot product come in. Understanding how these measurements work, along with the algorithms used to search and index vectors, is essential before implementing them in Java.
How Vector Similarity Search Works
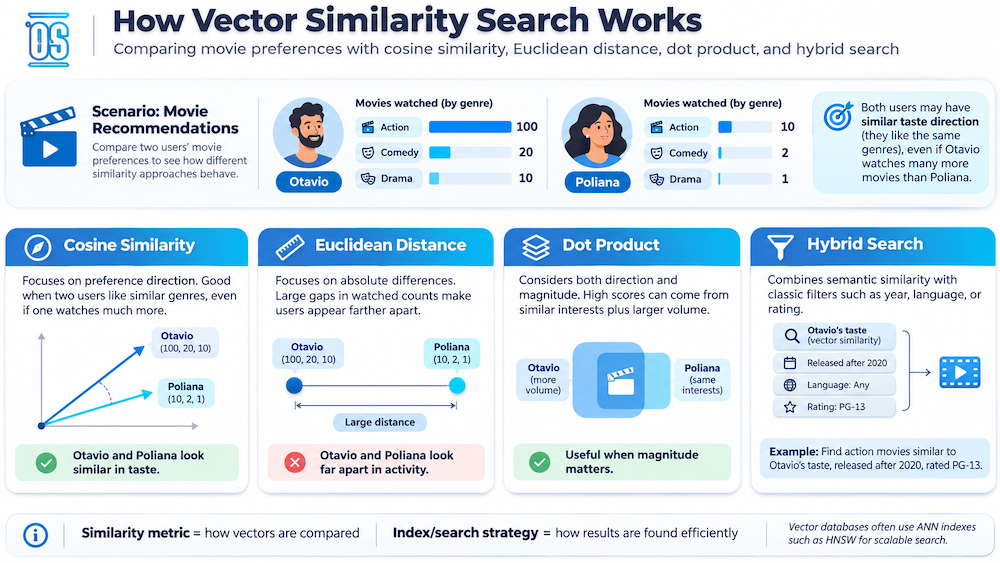
Storing vectors is only part of the challenge. A vector database must also identify which records are closest to a query. Unlike traditional searches that match exact conditions, vector searches use mathematical measures such as cosine similarity, Euclidean distance, and dot product. Each method evaluates similarity differently, even though all operate on numerical vectors.
Consider a movie recommendation application that represents user preferences across genres such as action, comedy, and drama. Otavio has watched 100 action movies, while Poliana has watched 10. Should the system recommend more action movies to Otavio just because he has watched more? The answer depends on what we want to measure.
Cosine Similarity: Comparing Direction
Cosine similarity evaluates the direction of two vectors, not their magnitude. For example, if Otavio has watched 100 action movies and 20 comedies, and Poliana has watched 10 action movies and 2 comedies, their viewing volumes differ, but their genre distributions are identical. Cosine similarity would consider these preference vectors equivalent in direction.
This approach is useful when recommendations should reflect user preferences rather than content consumption. Highly active users and occasional viewers can share similar interests despite different activity levels.
Euclidean Distance: Comparing Absolute Differences
Euclidean distance measures how far apart two vectors are in multidimensional space. In this example, Otavio’s and Poliana’s vectors would be far apart because their absolute viewing counts differ.
This method is useful when data magnitude matters, such as comparing consumption patterns or activity levels. However, raw counts can be misleading, as watching more movies does not always indicate stronger preferences.
Dot Product: Considering Direction and Magnitude
The dot product considers both alignment and magnitude. Two vectors in similar directions will produce a larger score as their magnitudes increase.
For recommendation systems, this is useful when vector magnitude reflects meaningful information, such as modeled preference strength. However, magnitude does not always represent enthusiasm. Otavio may have watched 100 action movies but rated most poorly, while Poliana watched 10 and loved each one. A recommendation model should incorporate ratings or other feedback to capture this distinction.
Bringing Vector Databases to Enterprise Java with Eclipse JNoSQL
While understanding vector databases matters, integrating them into enterprise applications is challenging because drivers, configurations, and query APIs differ. Eclipse JNoSQL 1.2.0 addresses this by adding support for vector databases like Qdrant, Milvus, and Weaviate. With Jakarta NoSQL mapping and a fluent API, developers can work with vector persistence while using familiar Java concepts.
Consider an application that stores technical articles and enables users to search by meaning instead of exact keywords. With Eclipse JNoSQL, an article can be represented as a standard Java entity:
@Entity
public class Article {

    @Id
    private String id;

    @Column
    private String content;

    @Column
    private String author;

    @Column
    private int year;

    @Column
    private Vector embedding;

    // Constructors, getters, and setters
}
This entity uses the same mapping model as Jakarta NoSQL, with an added Vector attribute for similarity search. Eclipse JNoSQL supports DenseVector, SparseVector, and MultiVector representations, though availability depends on the database provider.
Eclipse JNoSQL does not generate embeddings. A separate model handles embedding generation, which you can integrate using libraries like LangChain4j. After generating an embedding, the application can associate the vector with an entity and persist it using VectorTemplate.
@Inject
VectorTemplate template;

template.insert(article);
The real advantage shows up in search. Imagine a developer looking for articles about “building scalable Java applications” without requiring those exact words to appear in the content.
Vector queryVector = embedder.embed(
    "building scalable Java applications"
);

List<Article> articles = template.search(Article.class)
        .vector(queryVector)
        .limit(Limit.of(10))
        .result();
In this example, embedder is an embedding service the application provides. The query retrieves semantically similar articles and returns them as mapped Java entities.
Enterprise applications often require additional constraints. For instance, you may want to retrieve similar articles by a specific author published in recent years.
List<Article> articles = template.search(Article.class)
        .vector(queryVector)
        .where("author").eq("Example Author")
        .and("year").gte(2024)
        .limit(Limit.of(10))
        .result();
This approach combines vector similarity with traditional metadata filtering in a single fluent API. However, it differs from hybrid lexical-and-vector ranking, which uses separate retrieval mechanisms.
Beyond the API, choosing a database is an architectural decision. Qdrant, Milvus, and Weaviate vary in indexing, supported vector types, filtering, and operational features. Eclipse JNoSQL reduces Java-level coupling but doesn't eliminate these trade-offs or guarantee identical capabilities across providers.
Conclusion
Vector databases introduce new possibilities for enterprise applications by enabling similarity searches that go beyond traditional keyword matching. Understanding vector representations, similarity metrics, and their trade-offs helps Java developers and software architects choose the right approach without unnecessarily replacing existing persistence solutions. With Eclipse JNoSQL 1.2.0, developers can explore vector persistence through familiar Java APIs while integrating databases such as Qdrant, Milvus, and Weaviate. To explore these capabilities further, check out the practical code examples and visit the Eclipse JNoSQL website for documentation and additional resources.
Opinions expressed by DZone contributors are their own.