

Who Should Grade Your AI? Rules vs LLM Judges vs Humans
Learn when to use rule-based graders, LLM-as-a-judge, or human review to build more accurate, scalable, and reliable AI evaluation systems.
Join the DZone community and get the full member experience.
Join For FreeThe Real Question Is Not: Which Grader Is Smartest?
When teams begin building AI evaluations, it is tempting to reach for an LLM-as-a-judge because it can read almost anything and return a score. That flexibility is useful, but it can also hide a simpler option.
Suppose an agent is asked to process a refund. The final response says, "Your refund has been completed." You could ask another LLM whether that answer sounds correct. A better grader is to check the transaction state in the database or test environment. The database is closer to ground truth than the prose.
That leads to a practical rule: Grade the strongest evidence the task exposes. The more objective the evidence, the less judgment the grader needs. A unit test should beat an opinion. A database state check should beat a natural-language claim. A schema validator should beat an LLM deciding whether JSON "looks valid".
The four grader families below form a useful spectrum. They are not competitors. They solve different classes of evaluation problems. This same layered pattern appears in modern evaluation guidance and tooling, which combine code-based, reference-based, model-based, and human grading rather than relying on one universal judge.
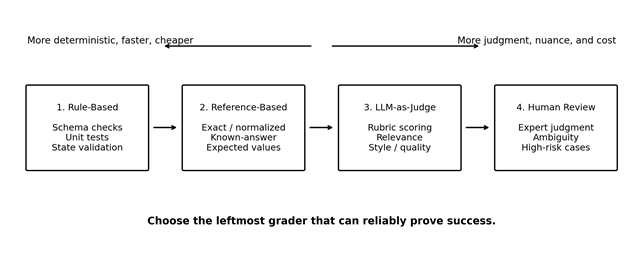
Grader Comparison at a Glance
|
Grader |
Best For |
Speed |
Cost |
Main Risk |
|
Code / rules |
Schemas, calculations, unit tests, system state |
Fast |
Low |
Brittle if checks are too narrow |
|
Reference matching |
Known answers, labels, expected values |
Fast |
Low |
Rejects valid variations |
|
LLM-as-a-judge |
Relevance, groundedness, quality, style |
Medium |
Medium |
Bias and non-determinism |
|
Human review |
Ambiguous, expert, or high-risk decisions |
Slow |
High |
Cost, fatigue, disagreement |
1. Rule-Based Graders: When Correctness Can Be Executed
Rule-based graders use code to verify a condition. They include exact assertions, regular expressions, schema validation, unit tests, static analysis, calculations, tool-call checks, and environment-state verification.
These graders should be the default whenever correctness is machine-verifiable. They are fast, inexpensive, reproducible, and easy to debug. If the same input and output are evaluated twice, the result should normally be the same.
Consider an extraction task where the model must return JavaScript Object Notation (JSON) with an order_id and confidence field. The most important questions are not subjective: Does the output parse? Are the required fields present? Is confidence between 0 and 1? A validator can answer those questions exactly.
import json
def grade(output: str) -> bool:
try:
data = json.loads(output)
return (isinstance(data.get("order_id"), str)
and isinstance(data.get("confidence"), (int, float))
and 0 <= data["confidence"] <= 1)
except (json.JSONDecodeError, TypeError):
         return False
This check is intentionally boring. That is a feature: the grader does not need to understand the prose, only the contract.
Rule-Based Graders Are Strong, But They Can Be Too Rigid
Deterministic does not automatically mean well-designed. A grader can still be too rigid if it checks a specific implementation detail instead of the required system behavior.
For example, suppose an AI coding agent is asked to fix an API endpoint so that it returns HTTP 404 when a requested record does not exist. The agent implements the behavior correctly, but uses a different code path than the reference solution.
A grader that compares the submitted code with the reference patch may incorrectly mark the solution as wrong simply because the implementation is different. A stronger deterministic grader would call the API with a missing record and verify that the response is actually 404.
The principle is simple: validate the required behavior, not whether the implementation matches one expected solution.
2. Reference Matching: When a Known Answer Exists
Reference-based graders compare an AI output with an expected answer. This works well for questions with a stable target: classification labels, extracted identifiers, translations with controlled terminology, benchmark answers, known numerical results, or expected API fields.
The simplest version is exact match. In practice, normalization often makes it more useful: trim whitespace, ignore capitalization where appropriate, normalize date formats, or compare structured fields instead of raw strings.
Reference matching becomes weaker as the answer space becomes more open-ended. If a question asks, "Why did the deployment fail?" there may be several correct explanations with different wording. Exact match can then punish correct answers. Fuzzy or semantic similarity can help, but as the comparison becomes more interpretive, you are moving closer to model-based judgment.
A good rule is to use references for facts, labels, and values, not as a universal definition of good writing.
3. LLM-as-a-Judge: When Quality Requires Interpretation
Some AI outputs cannot be graded with a simple pass/fail rule. For example, you may need to judge whether an answer is relevant, clear, complete, or supported by the provided context. These are good use cases for an LLM-as-a-judge.
An LLM judge usually receives the original task, the AI-generated response, and a grading rubric. It then returns a score, label, or short explanation. This makes it useful when you need to evaluate many responses that require human-like judgment.
The rubric should be specific. Instead of asking: “Is this a good answer?” Grade separate qualities such as:
- Relevance
- Factual support
- Instruction following
- Completeness
- Clarity
The judge should also receive any source material it needs to verify the response. If there is not enough evidence, it should be allowed to return something like “insufficient evidence” instead of guessing.
LLM judges are useful, but they are not perfectly objective. Their scores can be influenced by things such as answer order, response length, or writing style.
For that reason, the judge itself should also be evaluated. A common approach is to compare its scores with a smaller set of human-reviewed examples and check whether the two generally agree.
How to Make an LLM Judge More Trustworthy
Start with a clear rubric and narrow the question being graded. A judge that evaluates five unrelated dimensions in one prompt is harder to debug than several focused checks.
Next, calibrate it against human-labeled examples. If experts say 40 responses pass, and the judge disagrees on 15 of them, the problem is not solved by running the judge on 10,000 more examples. Improve the rubric, examples, model choice, or grading method first.
For preference tasks, pairwise comparison can sometimes be easier than assigning an absolute 1-to-10 score: show two answers and ask which better satisfies a specific rubric. But pairwise graders should also be tested for position effects by swapping answer order on a sample of cases.
Finally, do not ask an LLM to judge a fact that your system can verify directly. A judge can assess whether a support response explains a refund clearly. It should not be the authority on whether the refund actually exists in the transaction system.
4. Human Review: When Judgment Is the Ground Truth
Human review remains important when success is ambiguous, domain expertise is required, the cost of a wrong decision is high, or you need a trusted reference for calibrating automated graders. For example, OpenAI's GDPval uses expert graders as the primary standard and treats an automated grader as an approximation rather than a replacement.
Humans are especially useful for creating the first high-quality labels, reviewing disagreements between graders, evaluating unusual edge cases, and periodically checking whether an LLM judge has drifted away from expert expectations.
Human review is not perfectly deterministic either. Two experts can disagree about tone, completeness, or acceptable risk. Structured rubrics, reviewer training, and inter-rater agreement help turn human judgment into a more consistent signal.
The goal is therefore not to put humans in every evaluation loop. It is to spend human judgment where it adds information that automated checks cannot provide.
A Practical Decision Framework
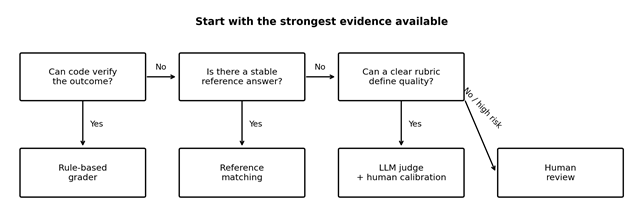
A grader-selection decision can usually be made by walking from objective evidence toward subjective judgment.
First ask whether success can be verified with code. If yes, stop there. If not, ask whether there is a stable reference answer. If there is, use reference matching. If the task is open-ended but has a clear rubric, use an LLM judge and calibrate it with humans. If experts themselves must interpret context, or the decision carries significant risk, use human review directly or as the final escalation layer.
One AI Task Can Need More Than One Grader
Real AI systems rarely have only one definition of success. A customer-support agent, for example, may need to take the correct action and communicate it well. Those two requirements should not be collapsed into one subjective score.
Imagine an agent that handles a refund request. A robust evaluation could check four different things:
|
What to Grade |
Best Grader |
Example Check |
|
Refund actually processed |
Rule-based |
Check transaction/database state |
|
Refund amount is correct |
Reference-based |
Compare with expected amount |
|
Response is clear and helpful |
LLM-as-a-judge |
Rubric for clarity and relevance |
|
Novel policy edge case |
Human review |
Subject-matter expert decision |
This layered design makes failures easier to diagnose. If the database check fails, you have an execution problem. If the action succeeds but the LLM judge flags the explanation, you have a communication-quality problem. A single overall score would hide that distinction.
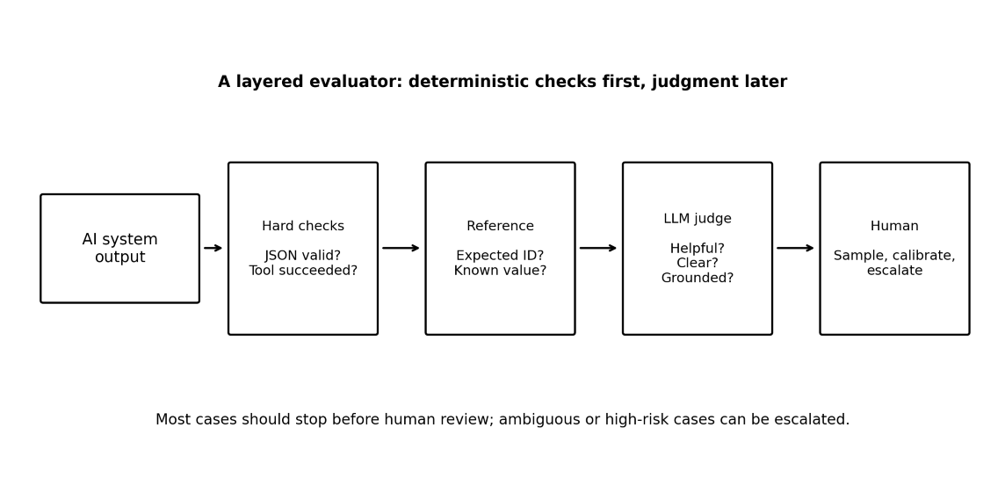
It also creates a natural escalation path. Most evaluation cases can stop after cheap automated checks. Only the cases that remain uncertain, disagree across graders, or carry high risk need human attention.
Common Grading Mistakes
- Using an LLM judge for deterministic facts. Arithmetic, JSON validity, tool success, API status, database state, and unit-test results should normally be checked directly.
- Using exact match for open-ended answers. Correct responses can use different wording, ordering, or reasoning. Match the grader to the size of the valid answer space.
- Grading what the model says happened instead of what happened. For agents, inspect the environment or system of record whenever possible.
- Writing vague LLM rubrics. "Good, helpful, and accurate" sounds reasonable but leaves too much room for interpretation. Define dimensions and observable criteria.
- Never calibrating the judge. An automated grader is another model or program in your system. It can be wrong, biased, or brittle. Test it against trusted examples.
- Treating human review as infallible. Humans also disagree and fatigue. Use structured criteria and measure disagreement on important evaluations.
A Better Default: Build a Grading Stack
Instead of choosing one universal grader, route each quality requirement to the least subjective evaluator that can answer it reliably.
A useful production stack is: hard checks first, reference checks second, LLM judgment third, and human escalation last. This ordering keeps evaluation fast and explainable while preserving a path for nuance.
The key is not to maximize automation at all costs. It is to preserve strong evidence. If an LLM score conflicts with a unit test, the unit test should usually win. If a rubric-based judge repeatedly conflicts with expert reviewers, the judge needs recalibration. The grading hierarchy should reflect how close each signal is to the actual definition of success.
Conclusion
There is no single best grader for AI systems because AI tasks expose different kinds of ground truth.
- Rule-based graders are best when correctness can be executed.
- Reference matching works when a stable expected answer exists.
- LLM-as-a-judge is valuable for scalable evaluation of open-ended qualities, but it needs a clear rubric and human calibration.
- Human review remains essential for ambiguity, expertise, calibration, and high-risk decisions.
The simplest rule is still the most useful: use the most deterministic grader the task allows. Do not ask an LLM to guess what a test, parser, database, or reference answer can prove. Save judgment for the parts of the system that actually require judgment.
Opinions expressed by DZone contributors are their own.
Comments